

Certainly one of my elementary beliefs concerning the world is that Ramez Naam must weblog extra. Ramez is without doubt one of the world’s biggest futurists — he predicted the photo voltaic and battery revolutions lengthy earlier than these have been extensively understood. If you happen to have been studying Ramez in 2011, you have been in a position to perceive the way forward for each vitality know-how and local weather change, lengthy earlier than different individuals did. His earlier e-book Greater than Human continues to be an important information to the type of organic enhancements that AI would possibly make doable. Ramez can also be a superb science fiction creator, having written a trilogy of novels through which nanotechnological telepathy is distributed as a celebration drug (I’m undecided if he truly expects that to occur, but it surely’s a really cool concept).
Sadly, though he does have a Substack (which you need to completely comply with), Ramez doesn’t weblog usually. Nevertheless, after having a prolonged non-public debate with him about Recursive Self-Enchancment, I used to be in a position to prevail upon him to write down up his ideas for my weblog.
To say that RSI is an enormous deal within the AI world could be a colossal understatement. Amongst AI researchers, entrepreneurs, and AI security individuals, there’s a widespread perception that as AI will get higher at bettering itself, there can be a “quick takeoff” or “FOOM”, through which AI’s capabilities “take off” and create a technological Singularity. This occasion is a staple of science fiction, together with works by my favourite sci-fi creator, Vernor Vinge.
Lots of people within the business consider that this second is now shut at hand, and are racing towards that prize:

Tanay Jaipuria@tanayj
Noam Brown says that recursive self-improvement / the power of AI fashions to do AI analysis is the highest precedence for OpenAI by a large margin.
OpenAI ranks it above making fashions that promote.
(through @theinformation podcast)
12:24 AM · Sep 27, 2026 · 4.01K Views
4 Replies · 2 Reposts · 44 Likes
However Ramez — usually among the many most wide-eyed of techno-optimists — is very skeptical that we’ll see something just like the “FOOM” of Vernor Vinge novels. On this prolonged, well-researched submit, he explains his skepticism.
Personally, I’m agnostic. Ramez’s case essentially rests on loads of assumptions; though it’s cogently laid out, I believe the actual reply is that we’ll simply have to attend and see whether or not the Singularity arrives. However much more essentially, I don’t know the way a lot this debate issues within the sensible sense — even with out the type of Singularity depicted in sci-fi novels, AI capabilities are bettering so quickly that they’re already superhuman in lots of respects, and shortly will in all probability be strongly superhuman in most or all dimensions. The AI of 2040 goes to look godlike, whether or not or not it explodes into an precise god in 2027.
Nonetheless, it’s a really fascinating argument, and Ramez’s ideas on the way forward for know-how are all the time price listening to.
AI is already serving to enhance itself. The query is whether or not even totally autonomous recursive self-improvement (RSI) would trigger a runaway intelligence explosion.
The speculation is that every technology of AI might construct a greater successor, quicker than the final technology did. That might result in a “quick takeoff,” with capabilities surging to synthetic superintelligence (ASI) in a yr, months, and even days.
Right here’s my take: Given our greatest present knowledge, the AI self-improvement loop would have to be roughly 5–10× stronger to maintain itself, not to mention run away. I’ll clarify this math in part 8. I anticipate extremely speedy AI progress by the requirements of almost some other know-how. However the proof we’ve got doesn’t counsel a sudden explosion to incomprehensible superintelligence anytime quickly.
I may very well be incorrect. Forecasters have repeatedly underestimated AI progress! I might nicely be subsequent. One factor that’s clear is that we’d like higher knowledge. For now, let’s work with what we will measure, and keep open to breakthroughs that might change the image.
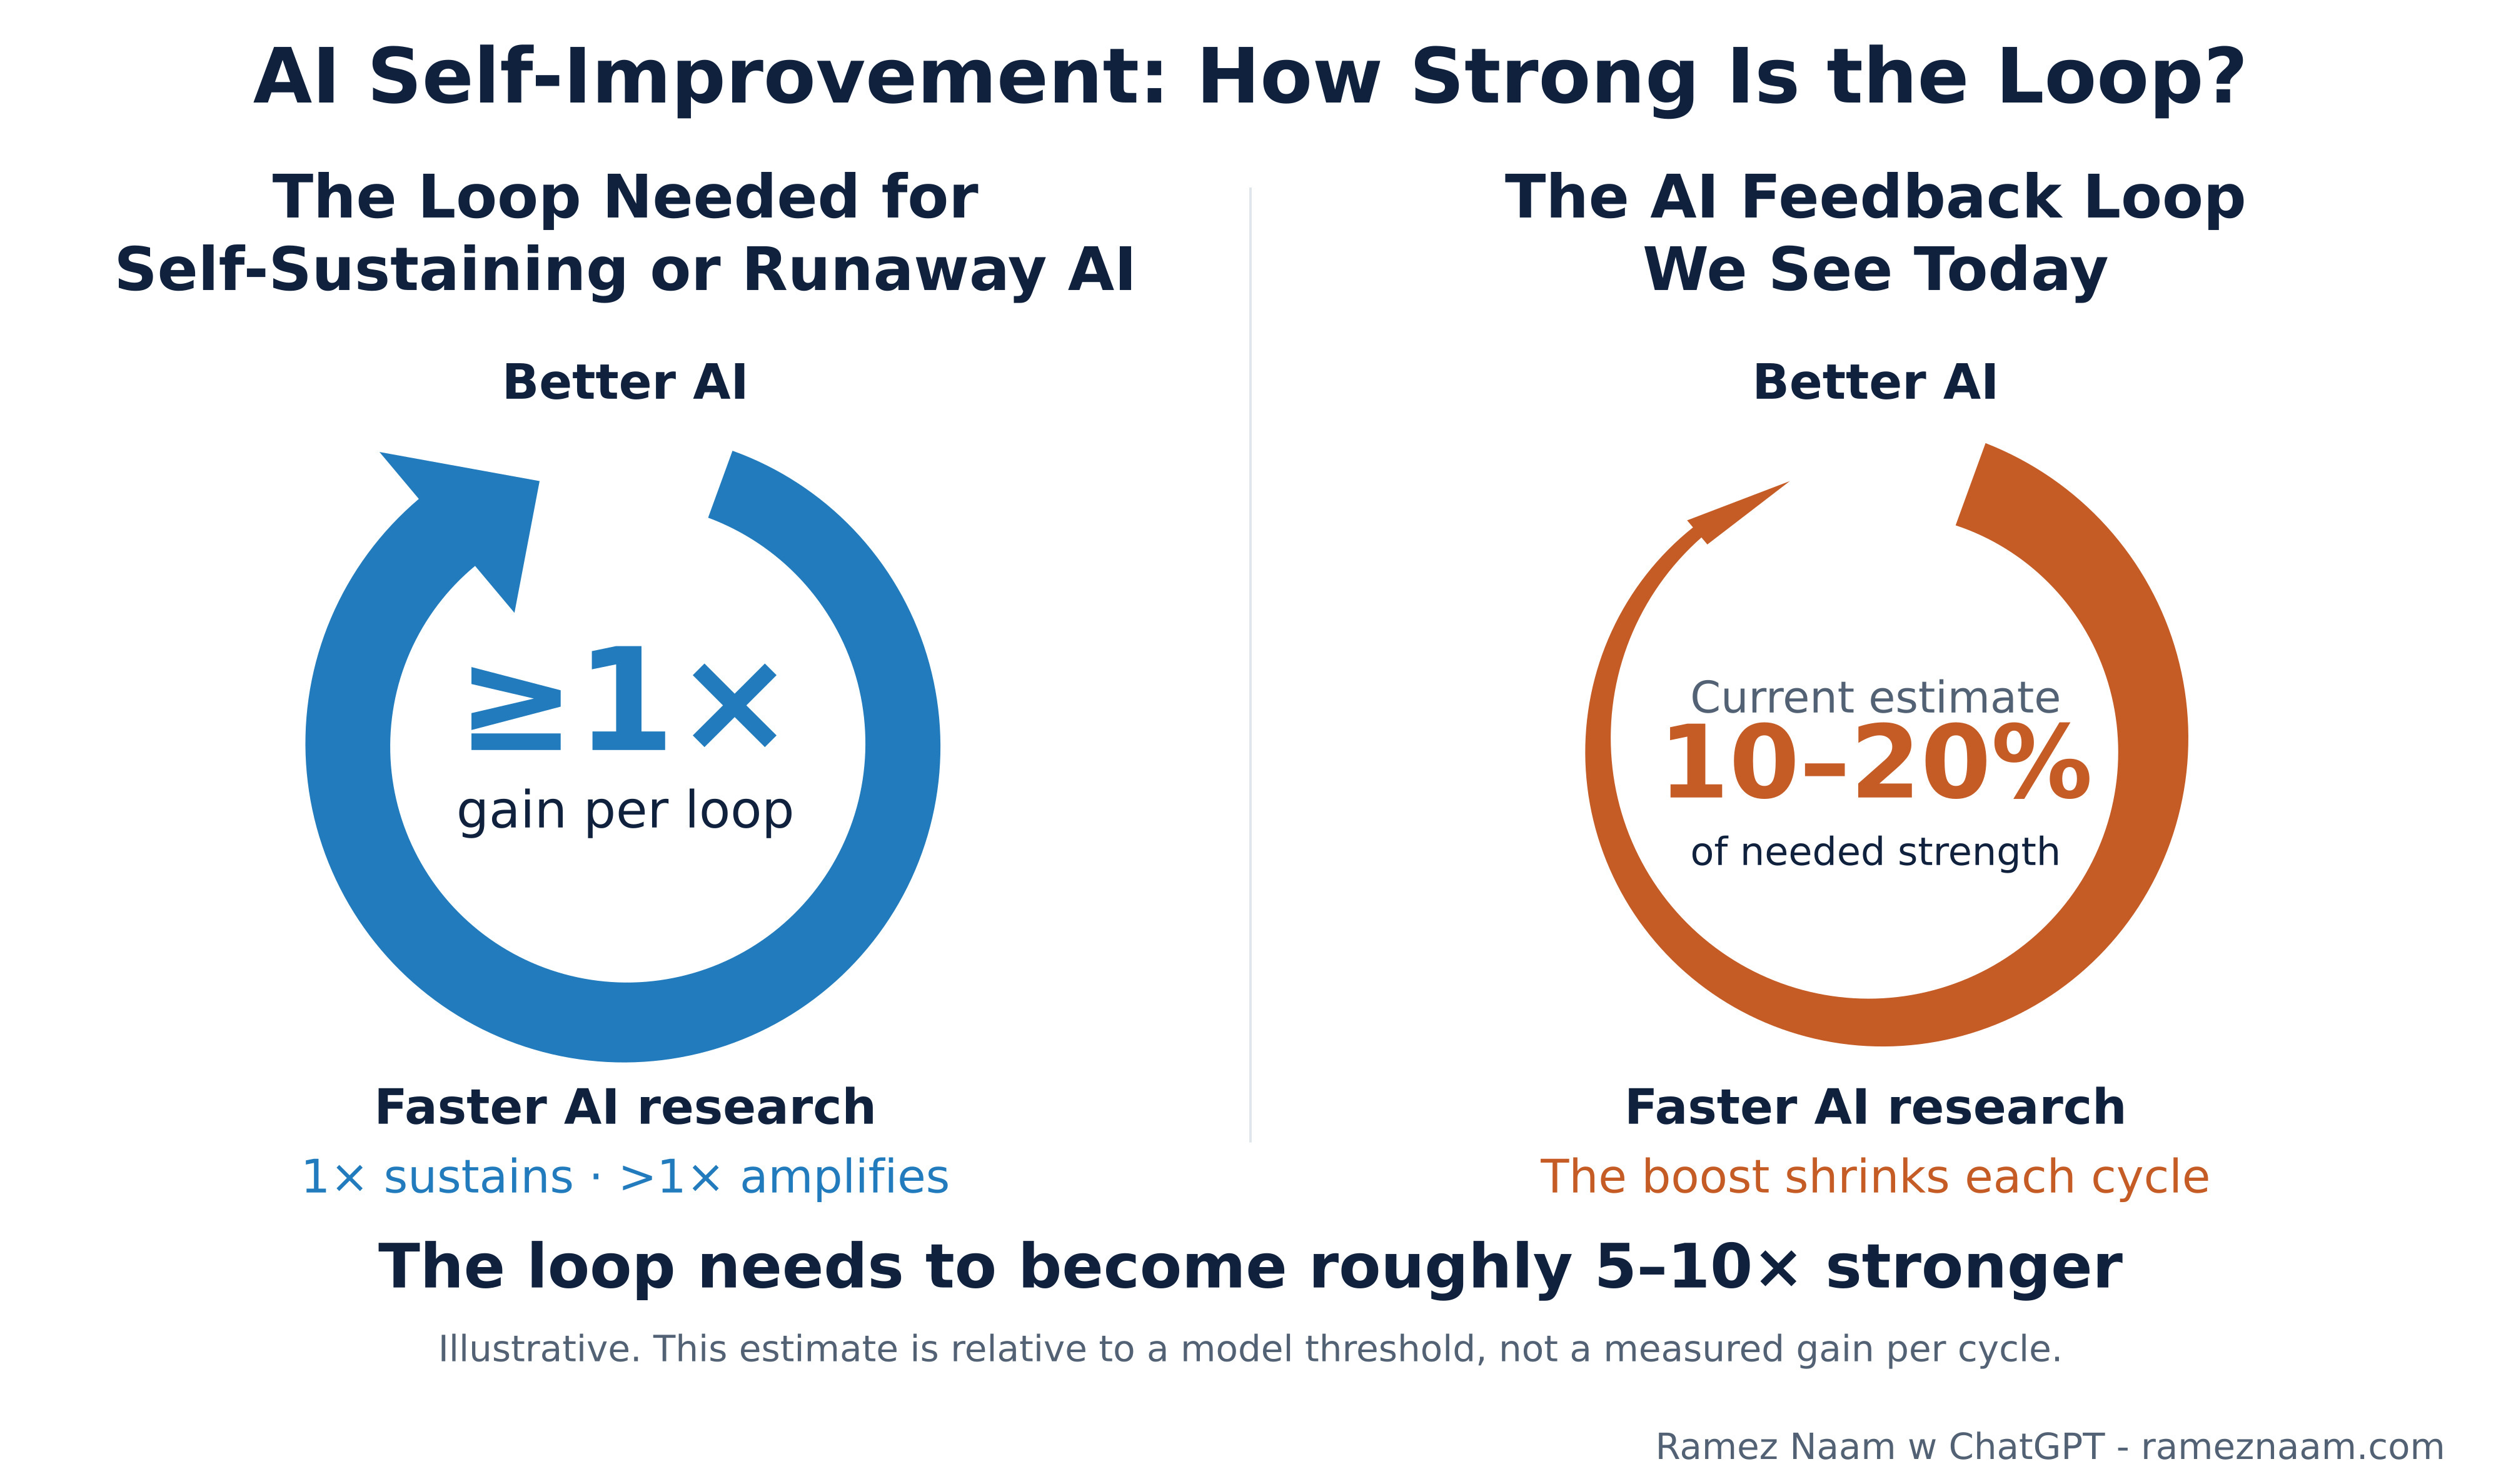
Determine 1. How robust is the self-improvement loop? Mannequin.
Right here’s the case, with hyperlinks to every half:
Key charts: The suggestions loop · Measured vs. forecast progress · Diminishing returns
Folks use “recursive self-improvement” to imply all the things from AI boosting the productiveness of human researchers to AI bootstrapping itself to incomprehensible intelligence. Right here’s my taxonomy: productiveness positive aspects (Kind 1), rising autonomy whereas nonetheless going through diminishing returns (Varieties 2–4), and a runaway loop to superintelligence if we will ever discover accelerating returns (Kind 5).
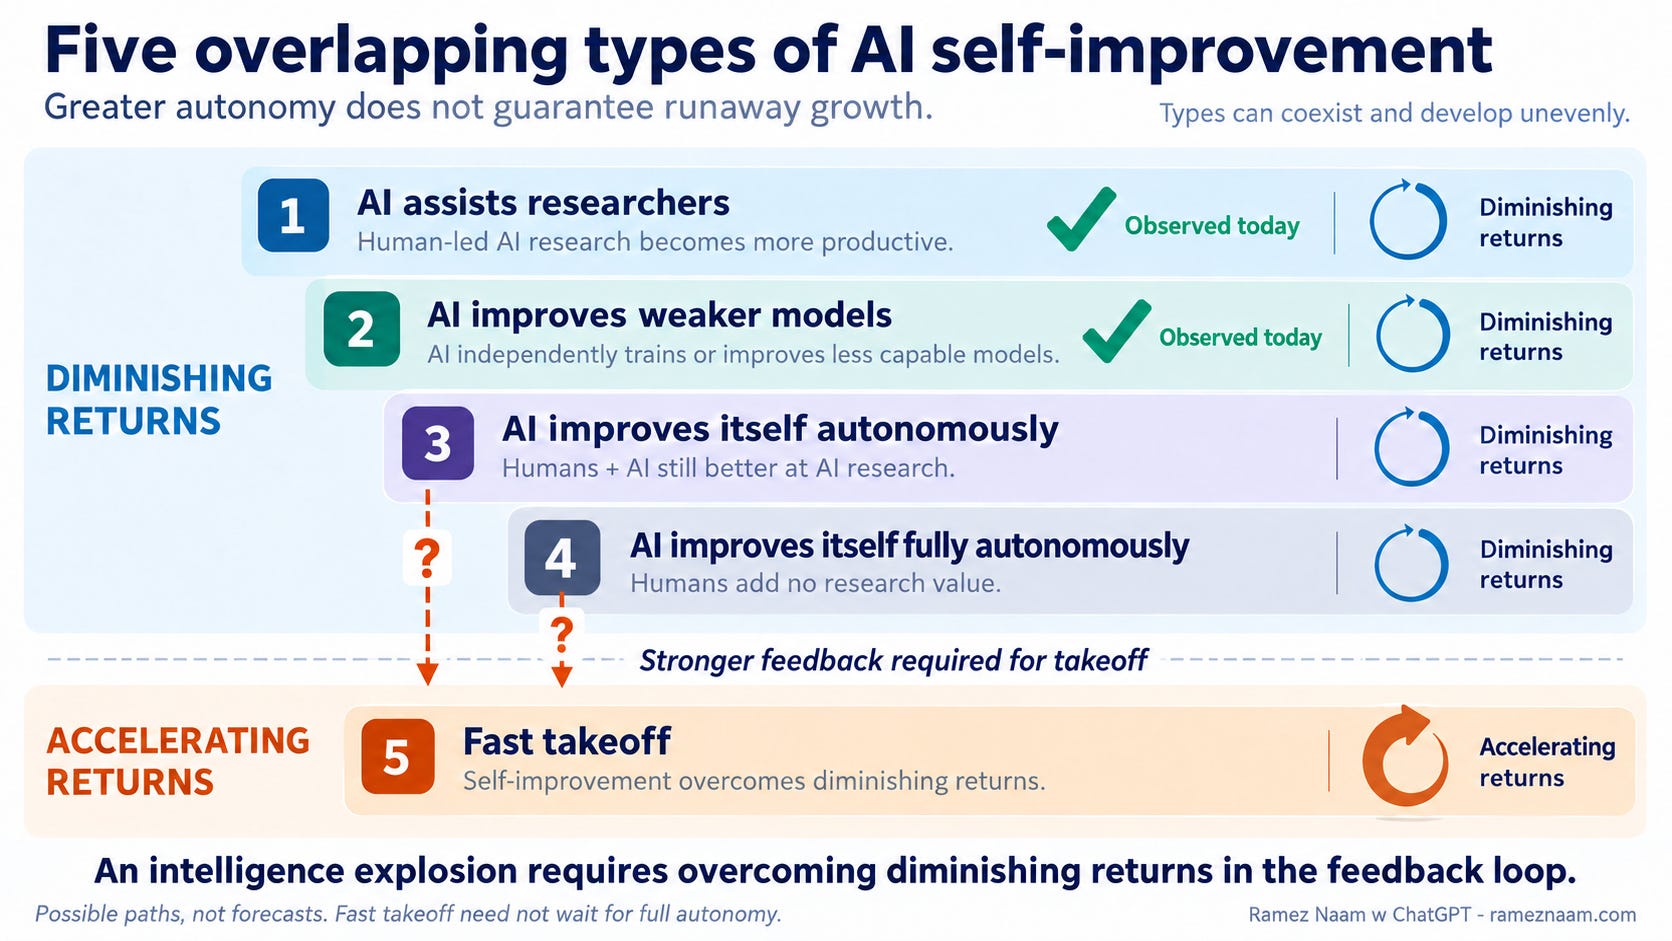
Determine 2. 5 forms of AI self-improvement.
We’ve made actual progress on Varieties 1 and a pair of: AI helps each researchers and engineers within AI firms, and highly effective fashions can prepare and enhance smaller ones. We haven’t but seen clear proof for Kind 3 (although Alibaba simply made some robust claims) and positively not for Kind 4. I do anticipate autonomous self-improvement to reach sooner or later. I’m skeptical that it results in Kind 5 – runaway super-intelligence – with out a main conceptual breakthrough.
There are many different definitions of RSI, which is usually a bit complicated. Weco’s 4 ranges of RSI are near mine. For a broader tour of all of the issues individuals imply after they say ‘RSI’, learn Tom Cunningham’s complete information.
I do anticipate slender superintelligence in extremely verifiable domains. Suppose chess, Go, formal math, elements of pc science and coding. Extremely verifiable domains are largely formal and structured forms of work the place machines can generate limitless coaching knowledge, with good or near-perfect verification of appropriate vs incorrect, and accomplish that completely in software program with out ready on the bodily world or people. That’s a really perfect setting for AI studying.
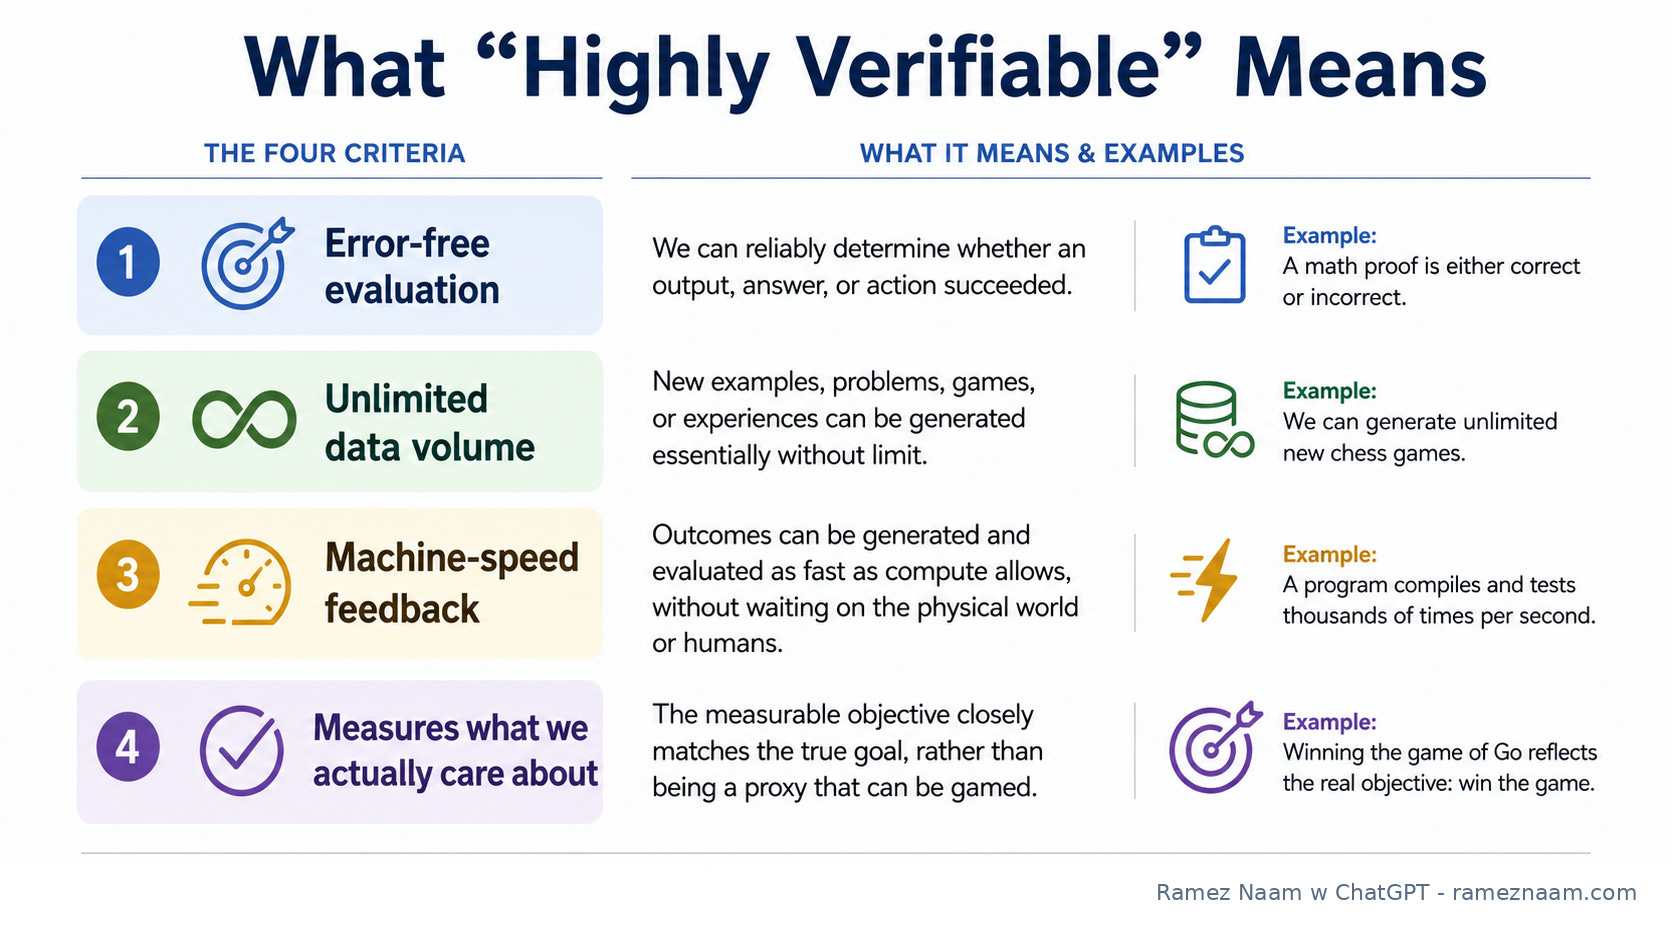
Determine 3. What makes a website extremely verifiable?
In actual fact, we have already got slender superintelligence in recreation plang. We’re seeing it occur now in probably the most formal elements of math, particularly in proofs and to find counter-examples that disprove main conjectures. For instance, OpenAI just lately reported an AI-generated proof resolving the Navier–Stokes existence and smoothness downside. Components of software program improvement are additionally extraordinarily verifiable, whereas others are a bit much less crisp (reminiscent of understanding what people need).
That isn’t the identical as broad superintelligence. Even our strongest fashions want way more coaching knowledge than people, battle to study reliably from ongoing expertise, and fail in shocking methods on duties individuals discover simple. Superhuman math doesn’t robotically imply superhuman judgment in all places else.
Benchmarks and forecasts counsel that AI fashions ought to reliably succeed at coding duties that take people hours, with out human assist. The actual world is messier. OpenAI’s inside knowledge exhibits a lot shorter stretches of autonomous work on analysis duties.
In its Analysis Acceleration / RSI report, OpenAI confirmed how typically its fashions accomplished duties with and with out human assist, grouped by how lengthy a human would wish to do the work.
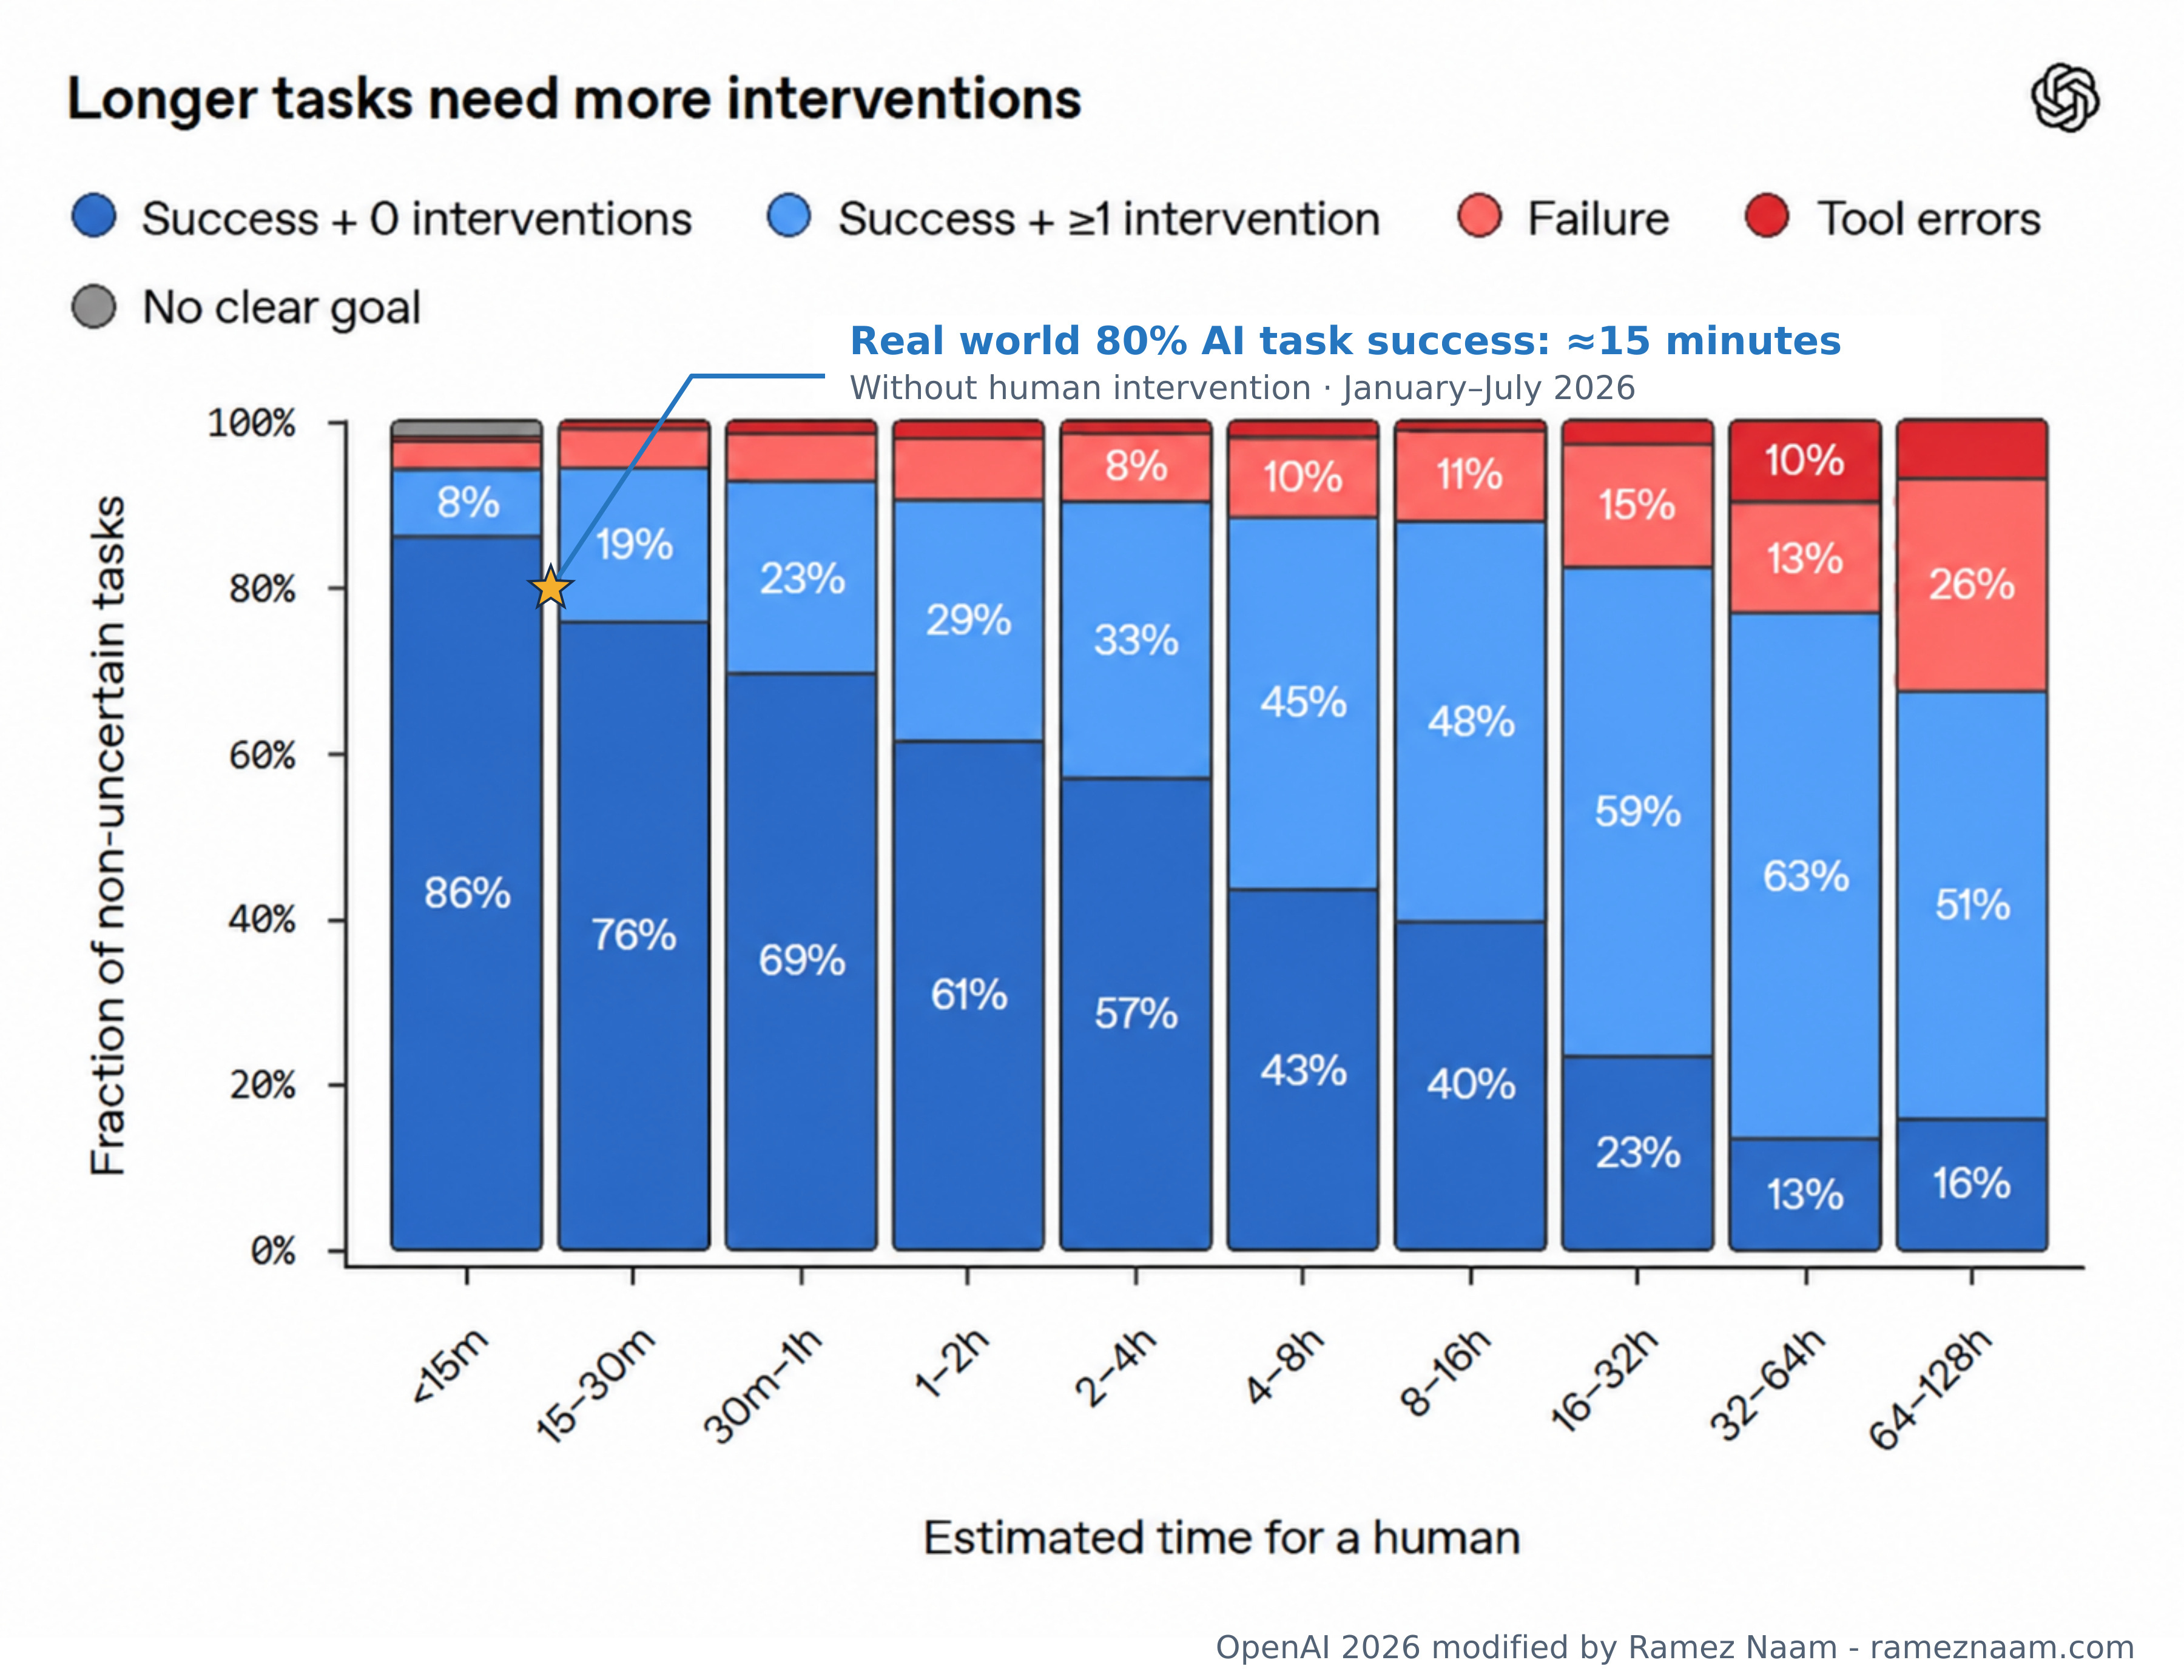
Determine 4. OpenAI’s inside analysis duties. Supply.
Even on duties that might take a human lower than quarter-hour, OpenAI’s fashions succeeded with out human intervention solely 86% of the time. The estimated process size at 80% success was roughly quarter-hour over the primary seven months of the yr. July’s outcomes have been just like the entire interval common.
Absolutely autonomous RSI would require an AI to string collectively an important many analysis duties reliably, stretching out over complicated duties that people want weeks or months to perform. OpenAI’s knowledge means that we aren’t shut.
Anthropic additionally launched a graph exhibiting how Claude accelerates AI analysis. It exhibits that inside AI fashions collaborate on and even lead greater than 90% of R&D duties. That’s objectively spectacular. On the similar time, the graph studies zero circumstances of AI autonomously finishing AI R&D duties.
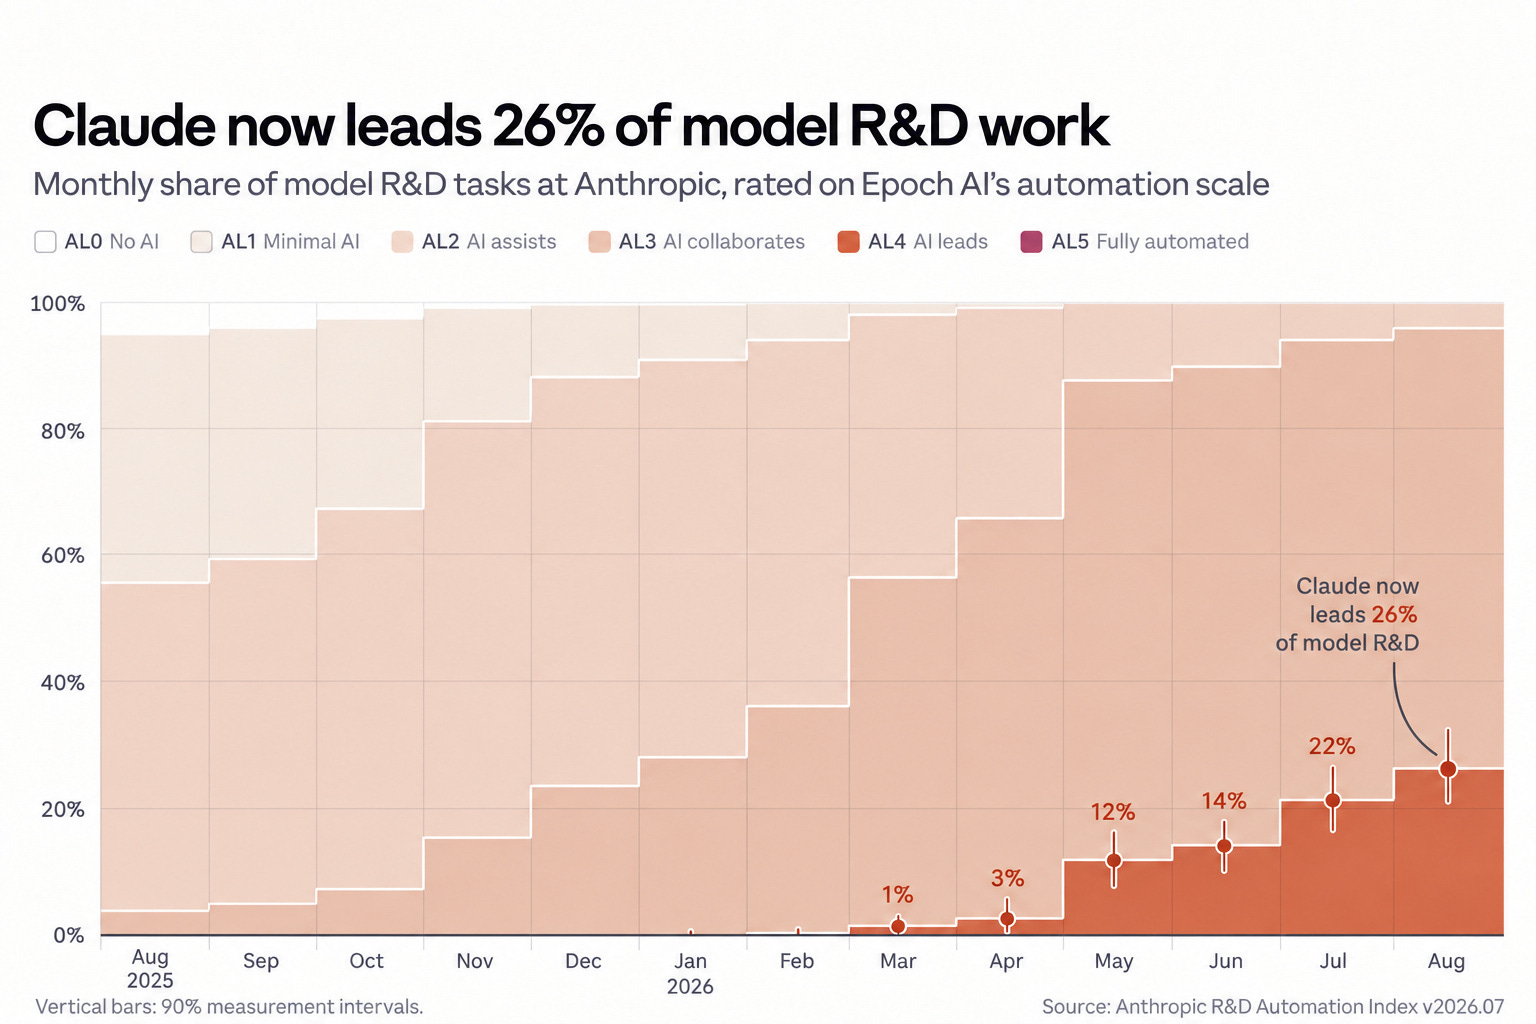
Determine 5. Claude’s position in inside AI R&D. Supply.
These are unbelievable instruments. However they nonetheless want expert individuals to set course and get them again on observe.
For years, METR has been publishing a chart exhibiting what size of coding process (measured in human hours to finish) best-in-class AI fashions can obtain. It’s been referred to as a very powerful graph in AI. METR’s Mythos Preview analysis estimated that the mannequin might succeed at 80% of coding duties that took people three hours.
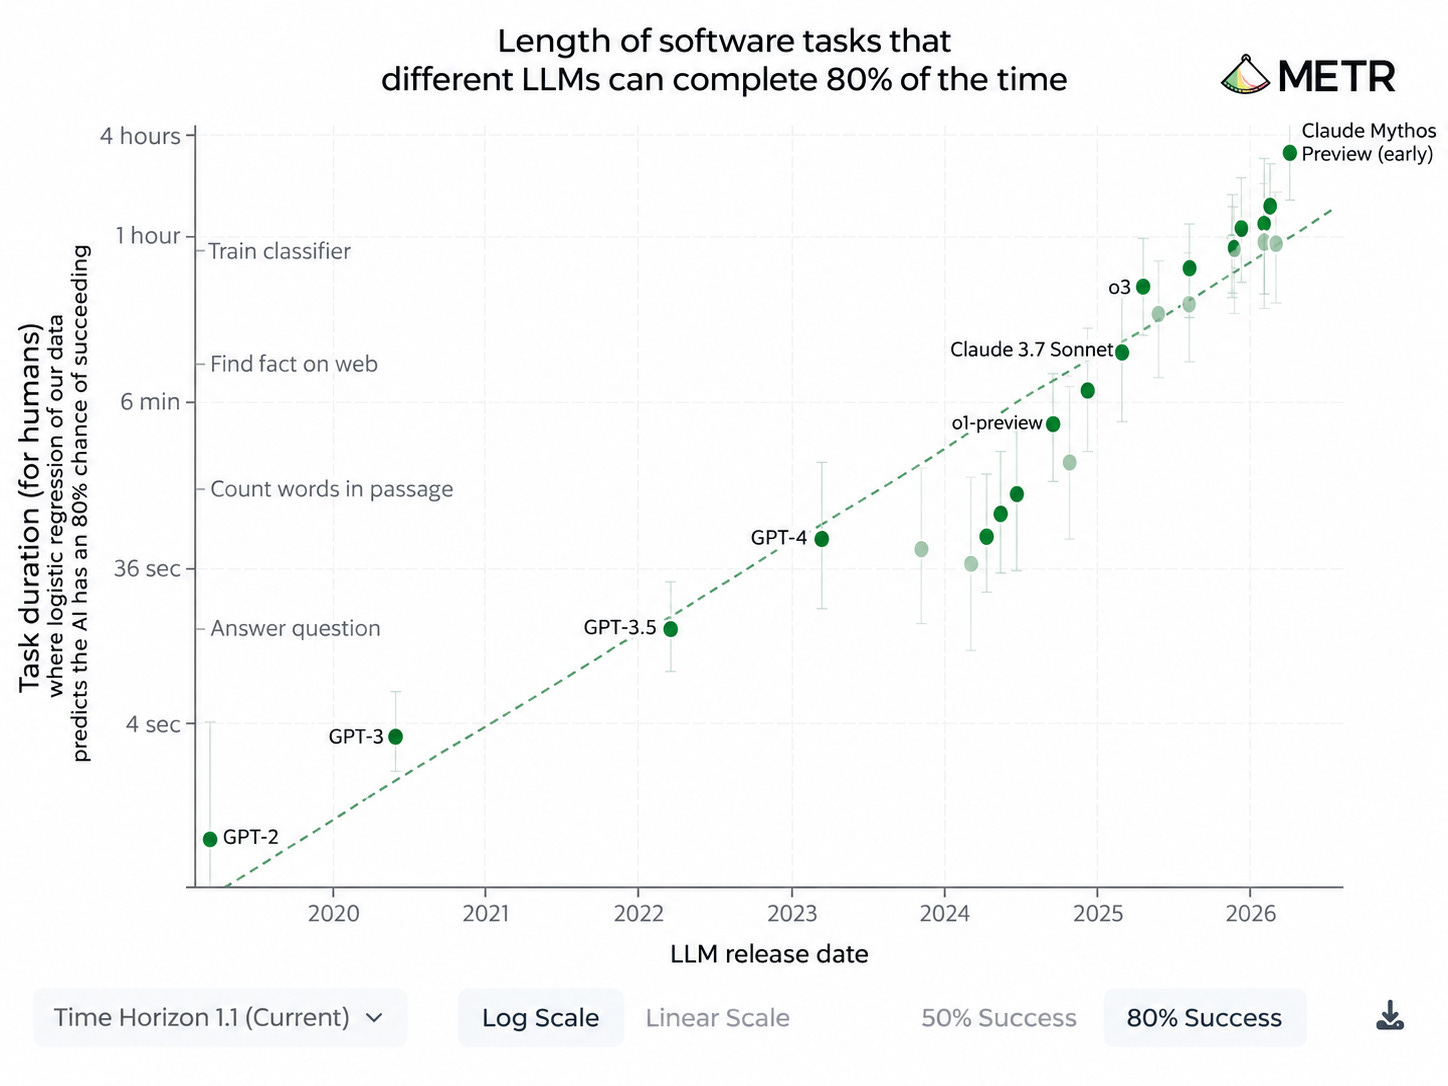
Determine 6. METR’s 80% process horizons. Supply.
Epoch’s personal rule of thumb is that each 5 extra factors of ECI (their general benchmark of AI functionality) correspond to roughly a doubling of METR’s process horizon. Utilizing that formulation, we’d anticipate GPT 5.6 Sol and GPT 6 Astra to be 80% profitable at finishing duties of round 4 hours and 11 hours of human size, respectively.
One other estimate (a forecast) of AI process size comes from the AI 2027 situation, which estimated that by July 2026, frontier AIs could be 80% profitable undertaking duties of round 11 hours. Pretty related.
The AI 2027 Tracker charts all of those.
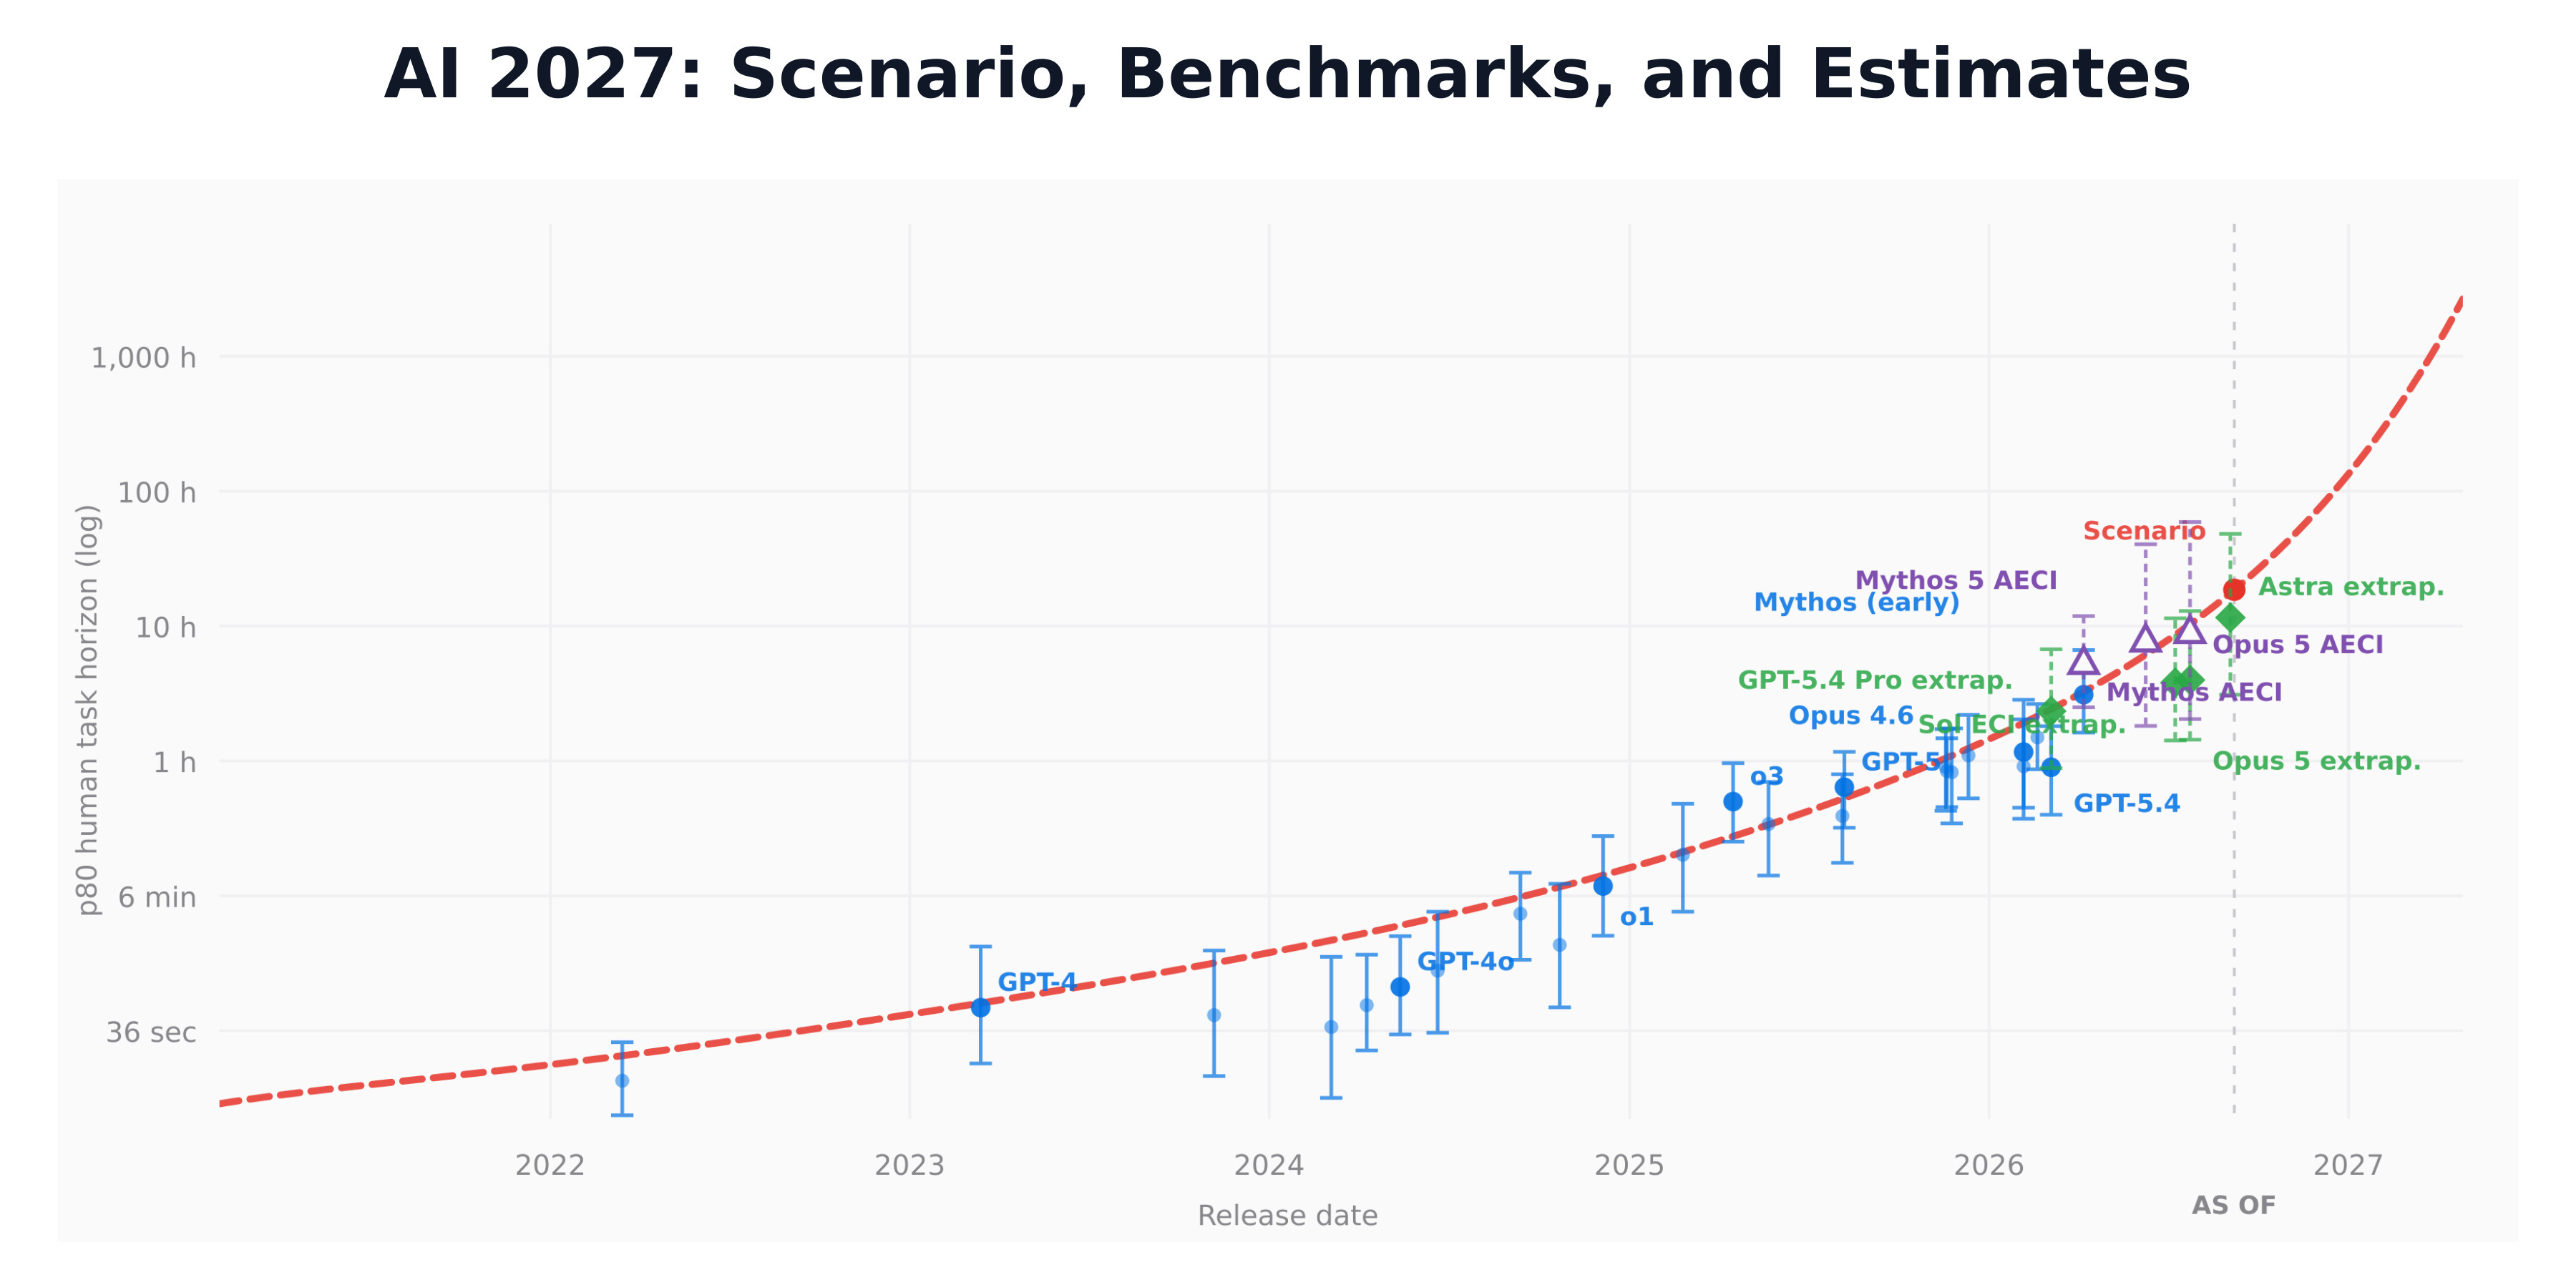
Determine 7. The AI 2027 Tracker. Supply.
Inside OpenAI, although, the July research-task horizon at 80% success was roughly quarter-hour.
Right here’s the hole:
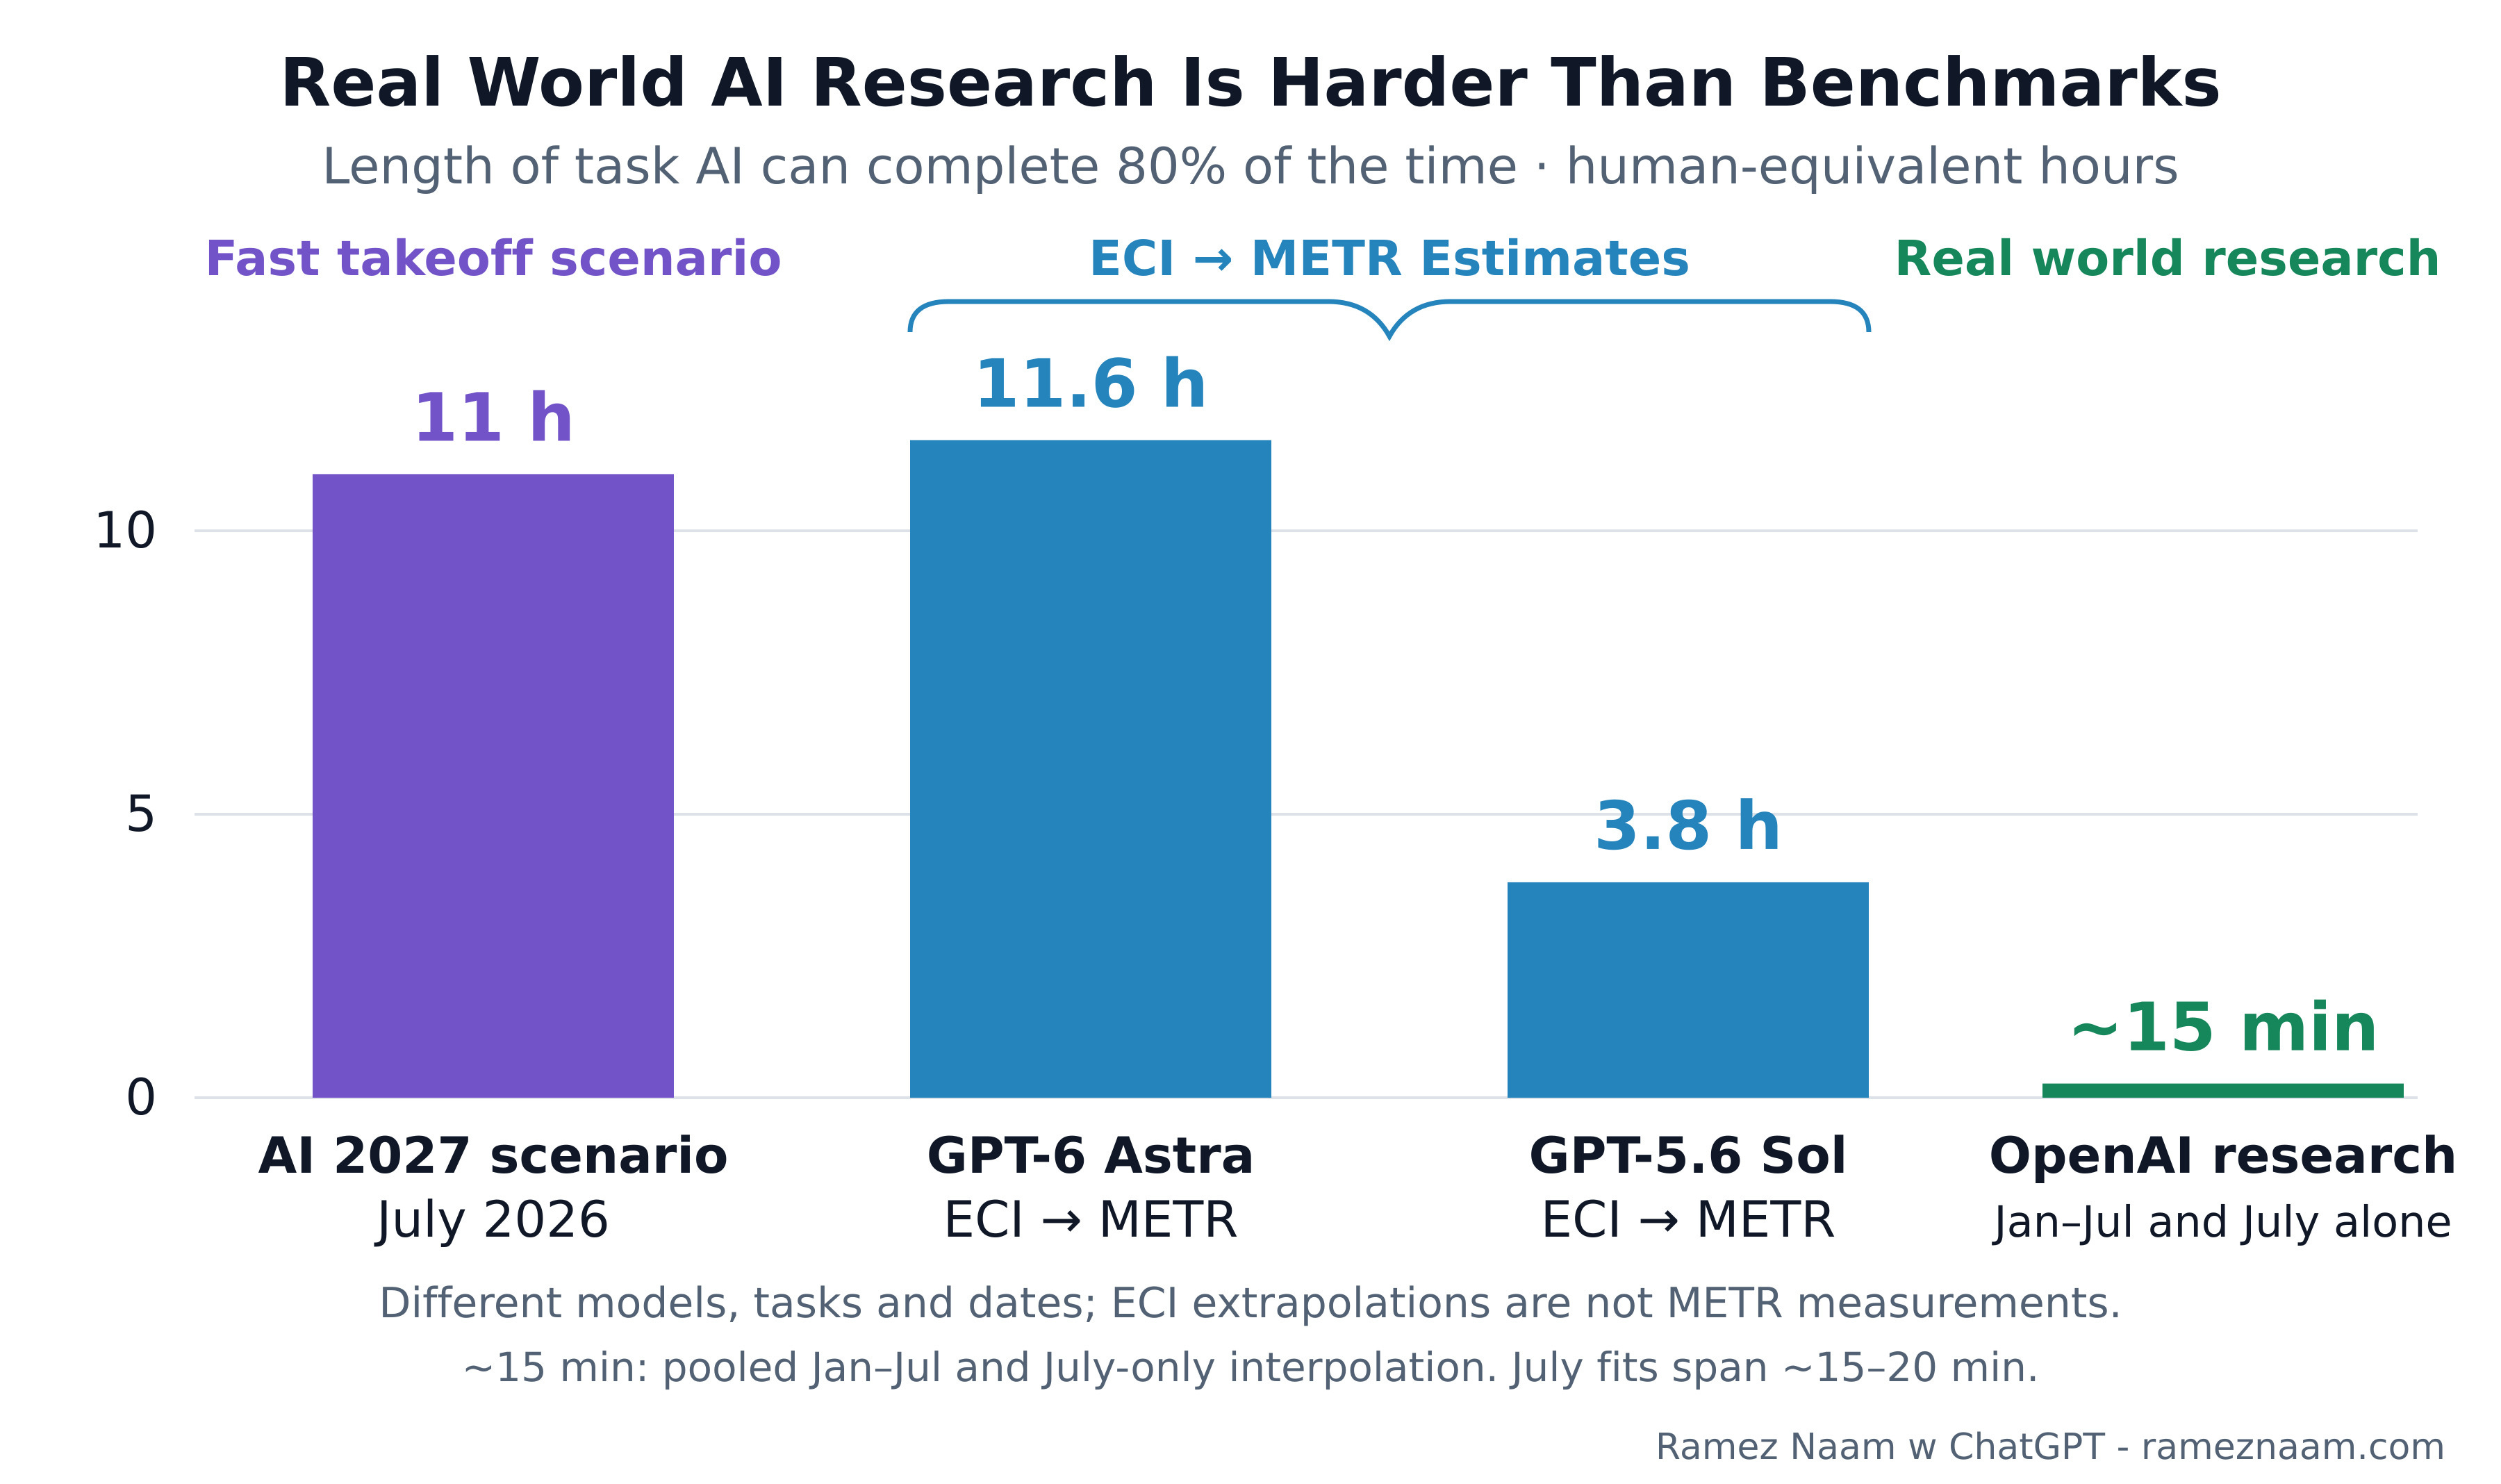
Determine 8. Forecasts, benchmarks, and actual AI analysis. Tracker · OpenAI.
A four-hour benchmark horizon is about 16 instances longer than OpenAI’s analysis horizon. AI 2027’s 11-hour forecast is about 44 instances longer. After all, the duties being carried out by researchers at OpenAI aren’t the identical as these within the METR benchmark. So we must always anticipate some discrepancy. This, nevertheless, goes nicely past that.
Precise AI analysis at OpenAI is an order of magnitude or extra tougher than metrics, benchmarks, or forecasts counsel. That ought to make us cautious of relying an excessive amount of on benchmarks, or of claiming that future situations like AI 2027 are ‘on observe.’ The authors of the associated AI 2040 challenge nonetheless describe AI 2027 as roughly the longer term they anticipate, and say actuality is monitoring nearer to it than even they anticipated. That’s not what we see from inside OpenAI. This isn’t an apples-to-apples comparability, however the distinction is outstanding. AI 2027 seems to be considerably over-optimistic on this regard.
In January of this yr, Nathan Witkin made a case that the METR graph was exaggerating progress. The actual world knowledge means that a minimum of a few of his critiques have been appropriate. The hole between benchmarks, forecasts, and knowledge gleaned from precise use of AI ought to affect our expectations concerning the future.
OpenAI’s report additionally exhibits spectacular will increase in AI token utilization, in compute spend per researcher, and in strains of code written. However these aren’t outcomes. They’re intermediate measures. How a lot progress do they really drive?
Researchers used 124x extra tokens per individual. Engineers shipped roughly 7x as many strains of code per individual. Researchers ran 1.6x as many experiments per researcher vs OpenAI’s 2025 complete yr common.
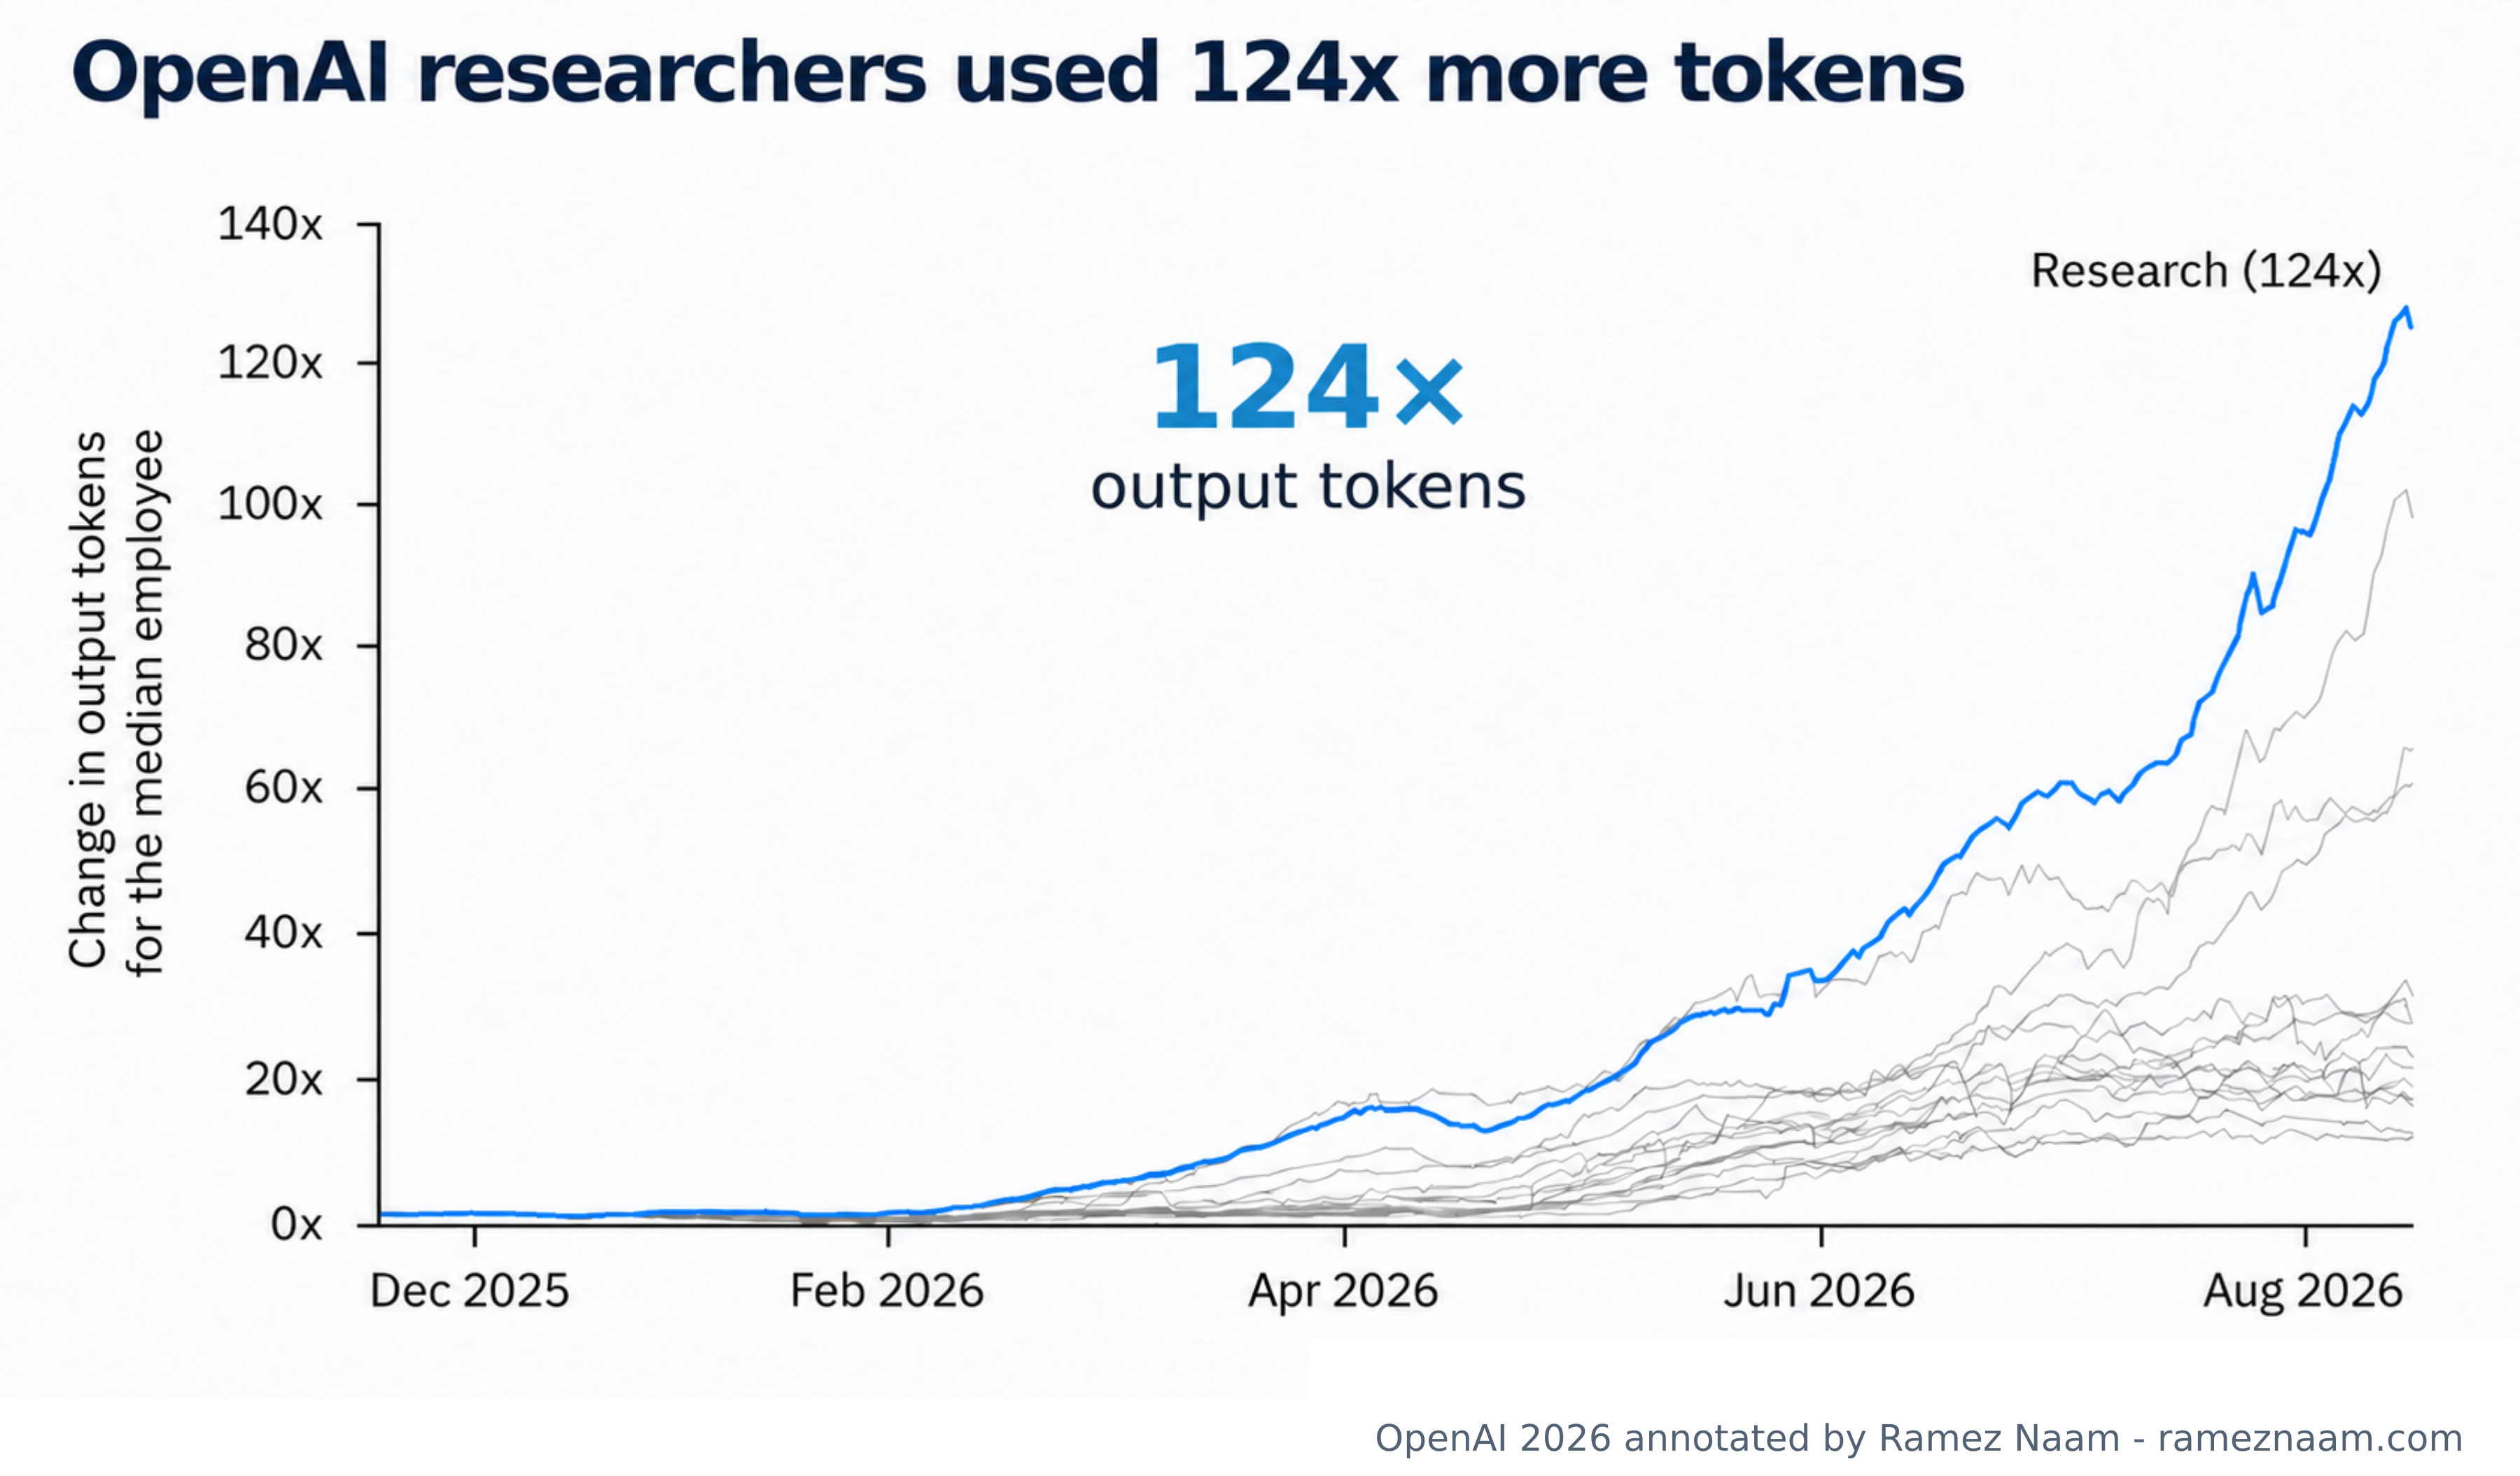
Determine 9. Token use inside OpenAI. Supply.
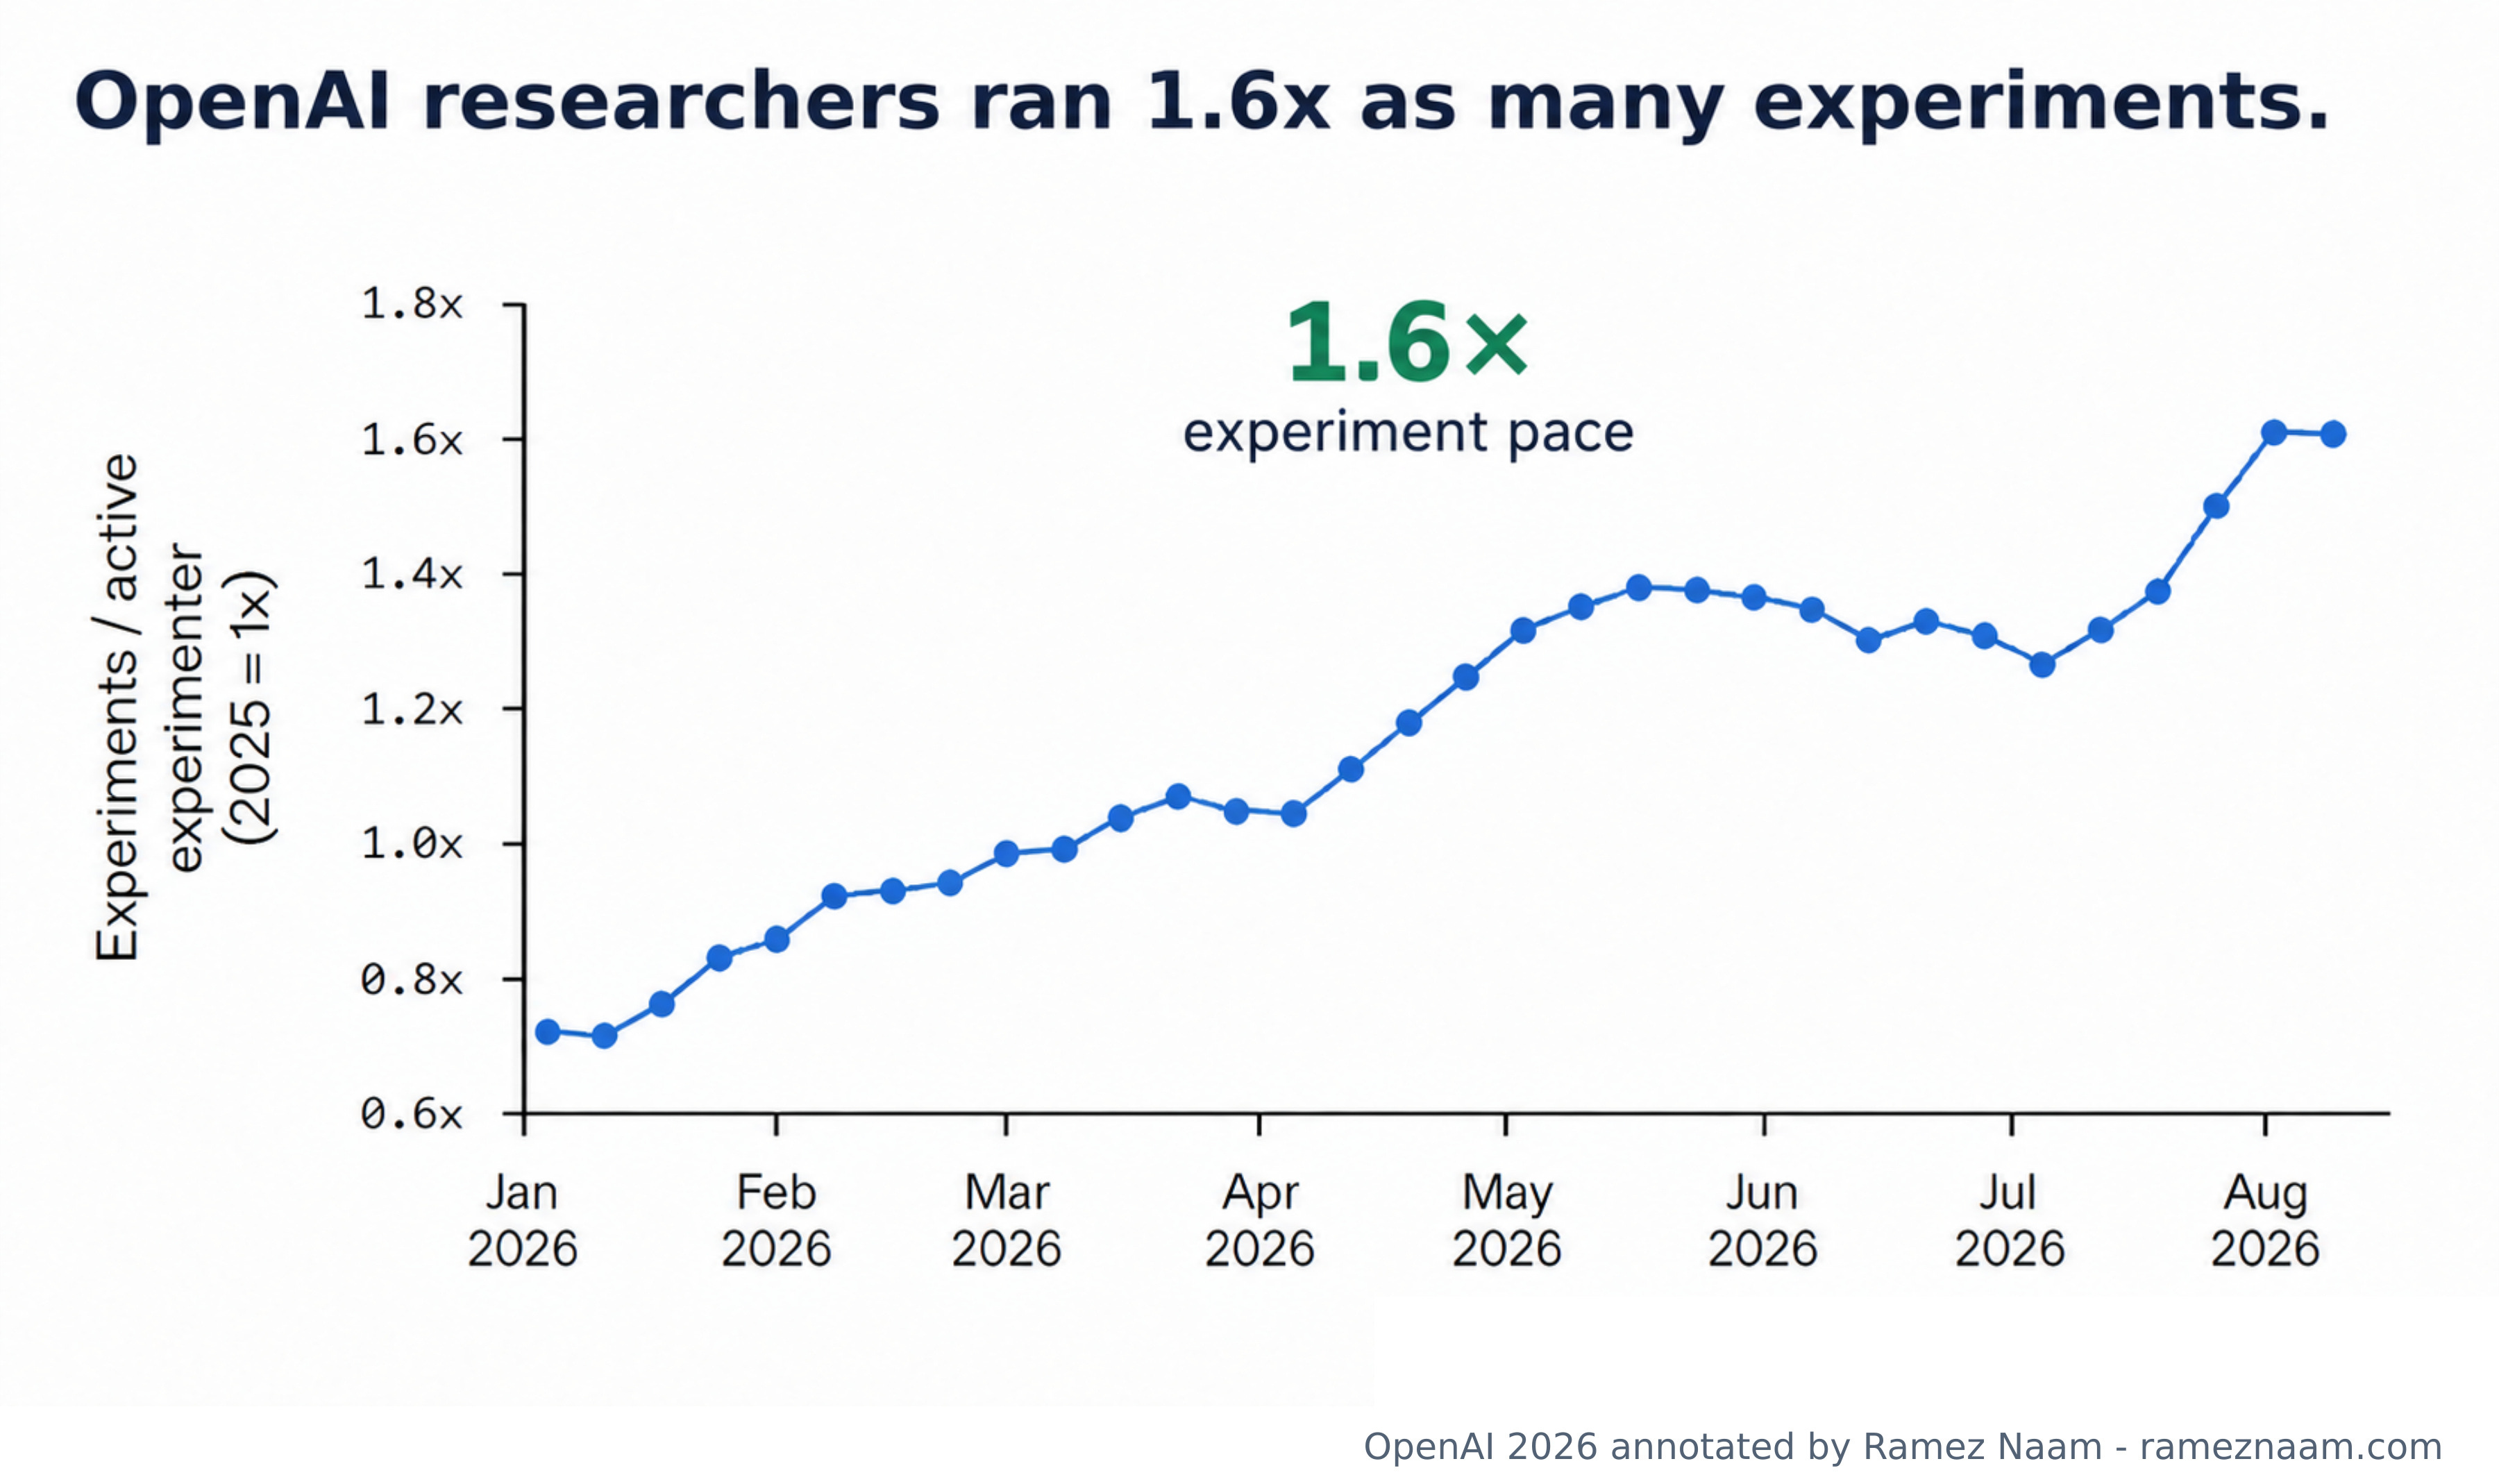
Determine 10. Experiment tempo inside OpenAI. Supply.
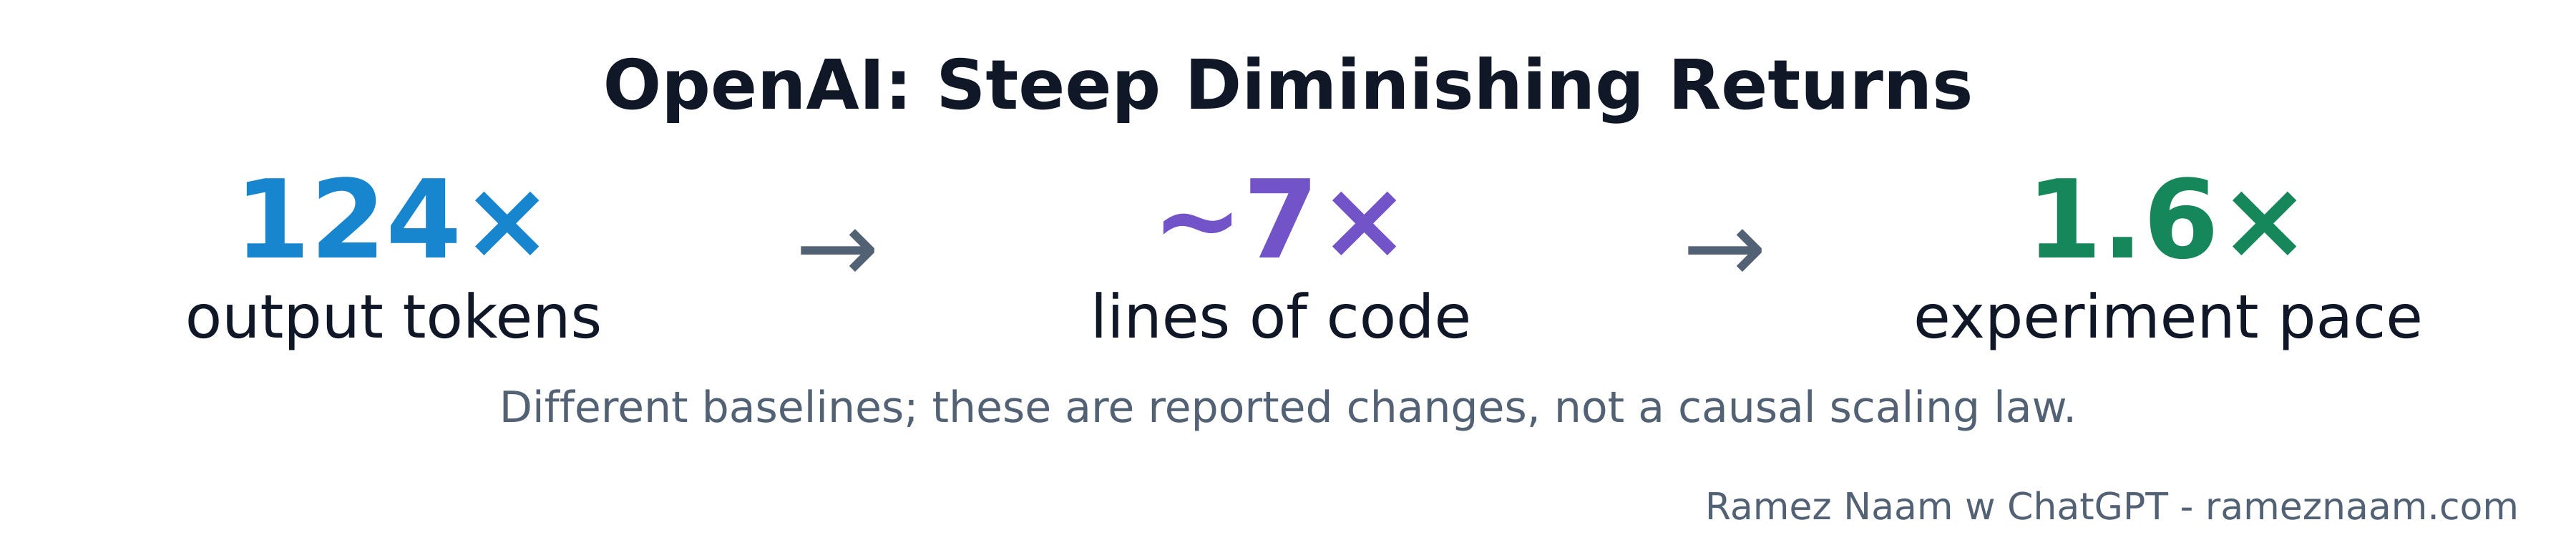
Determine 11. From tokens to code to experiments. Supply.
Extra tokens and code don’t inform us a lot on their very own. The 1.6× experiment tempo is nearer to helpful analysis output. Even that doesn’t imply AI is bettering 1.6× quicker.
An unlimited enhance in AI output has accompanied a a lot smaller enhance in experiments run.
This isn’t a managed experiment. We don’t know what would occur if researchers switched again to an older mannequin. But it surely offers us a helpful view of AI-assisted analysis inside a frontier lab.
It’s not simply OpenAI. Anthropic studies that their engineers at the moment are producing 8x as many strains of code per individual as they did in 2024 – considerably just like OpenAI. Anthropic additionally sees important diminishing returns between productiveness and AI progress. Right here’s a direct quote from its Mythos Preview system card:
“Productiveness uplift doesn’t translate one-for-one to capabilities progress. We surveyed technical employees on the productiveness uplift they expertise from Claude Mythos Preview relative to zero AI help. The distribution is large and the geometric imply is on the order of 4×. […] We estimate that reaching 2× on general progress through this channel would require uplift roughly an order of magnitude bigger than what we observe.”- Anthropic, Claude Mythos Preview System Card; emphasis mine
Translation: To double the tempo of AI progress, Anthropic estimates that AI would wish to extend the productiveness of their workers by roughly an element of 40 relative to no AI help.
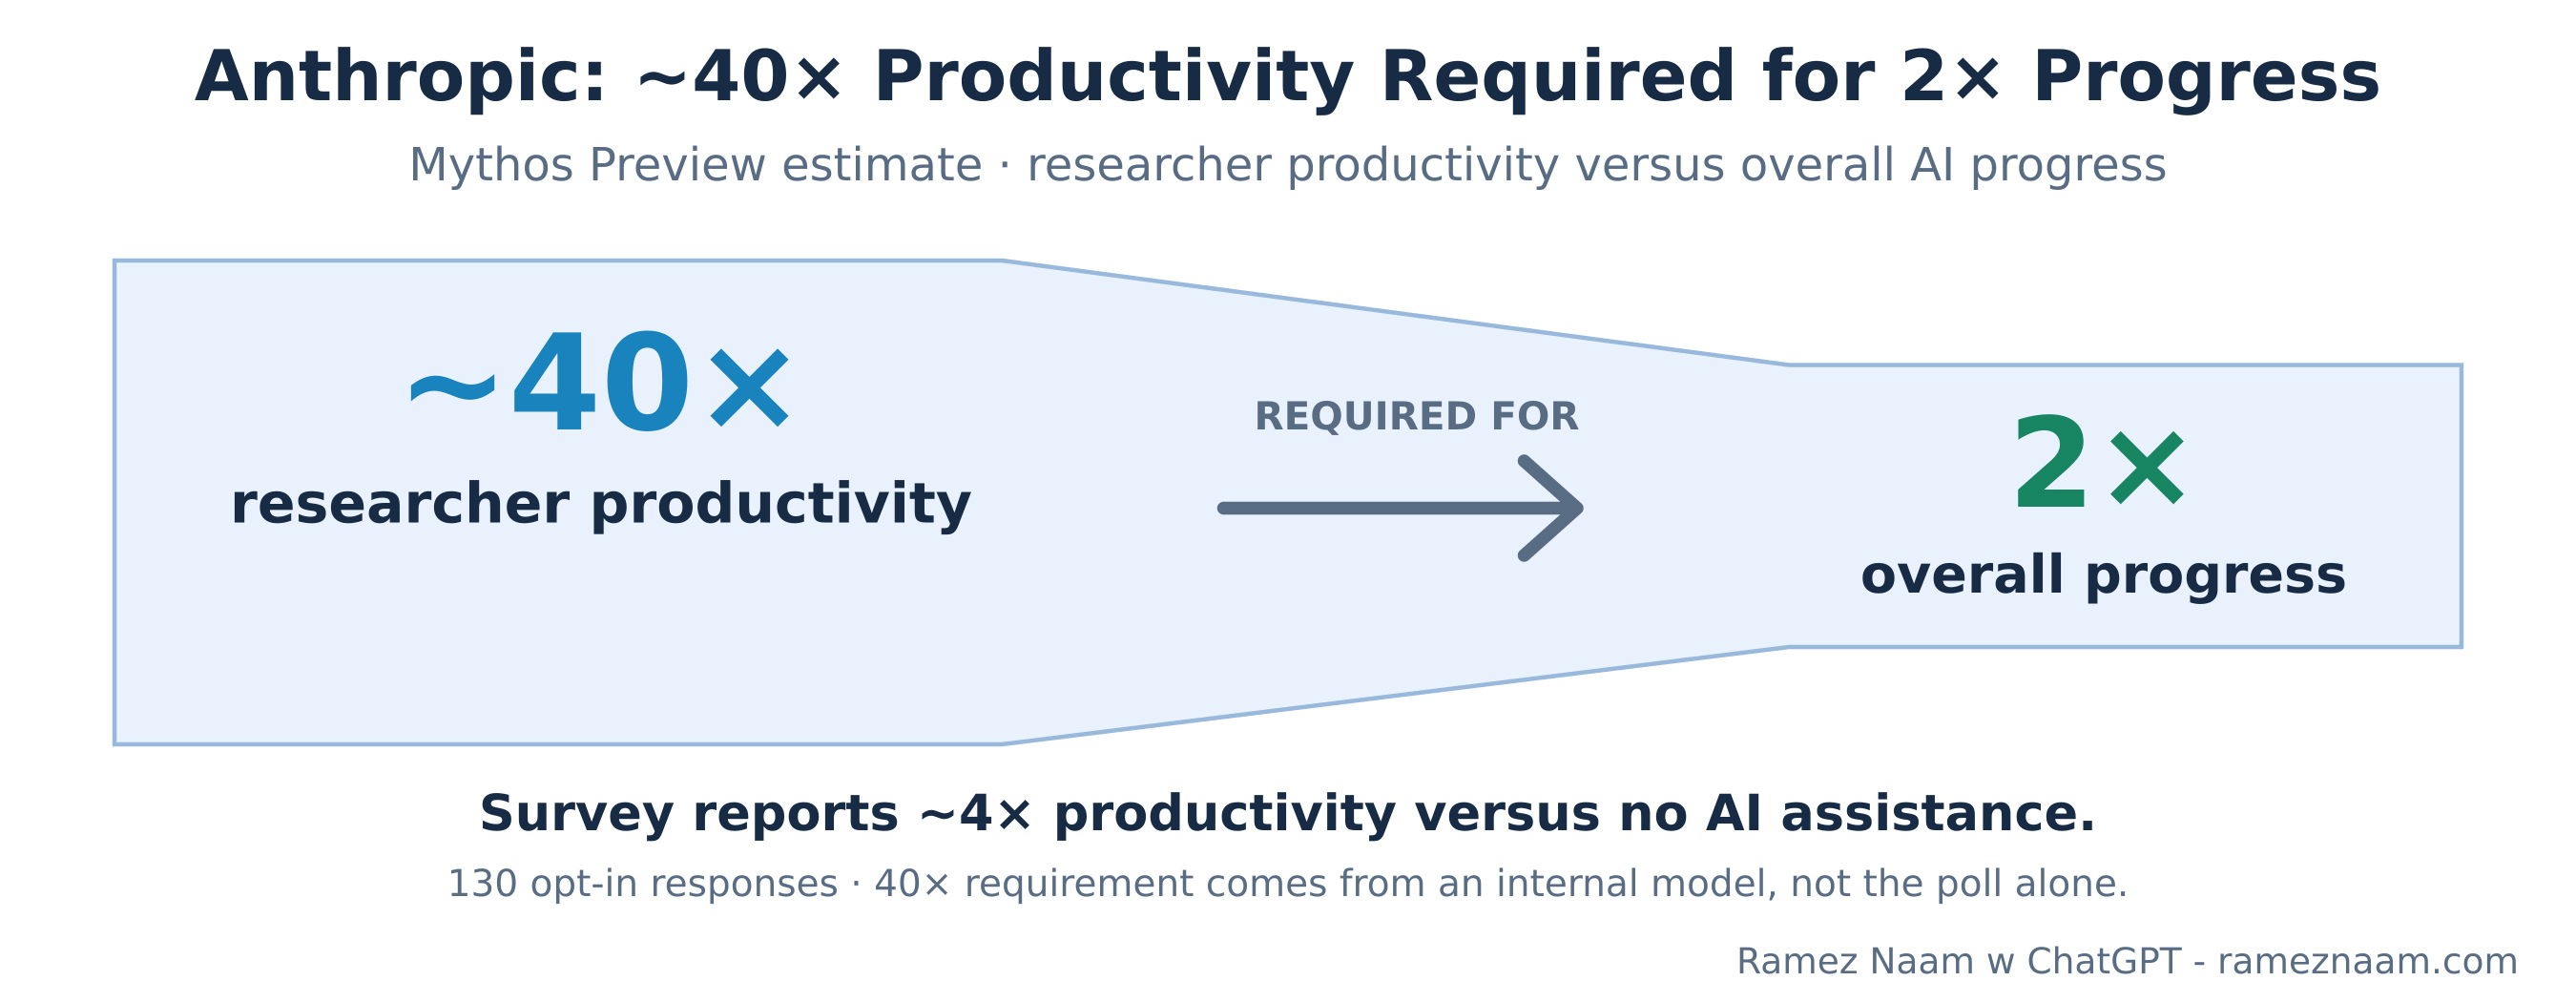
Determine 12. Anthropic’s productivity-to-progress estimate. Supply.
That is an estimate, not a measurement of progress. Even the 4× productiveness determine comes from an opt-in survey of 130 Anthropic employees. I put extra weight on OpenAI’s logged experiments, although the 2 sources measure various things.
We don’t but know the way a lot these additional experiments are accelerating AI enchancment, if in any respect. Usually, there are additionally steeply diminishing returns of extra experiments in most branches of science. That signifies that a 60% enhance in experiment tempo may very well be on the order of a ten% enhance to AI enchancment tempo. (An influence regulation exponent of 0.2, for individuals who wish to do the maths.) That’s hypothesis for now. We’ll study extra because the labs publish outcomes.
What about giving the identical AI mannequin extra time to suppose?
That scales badly additionally. In OpenAI’s just lately publicized outcomes on unsolved math issues, success rises roughly with the log of compute over the vary proven. It exhibits logarithmic diminishing returns. In plain English, every extra doubling of compute for a mannequin buys roughly the identical achieve in success price, whereas costing twice as a lot.
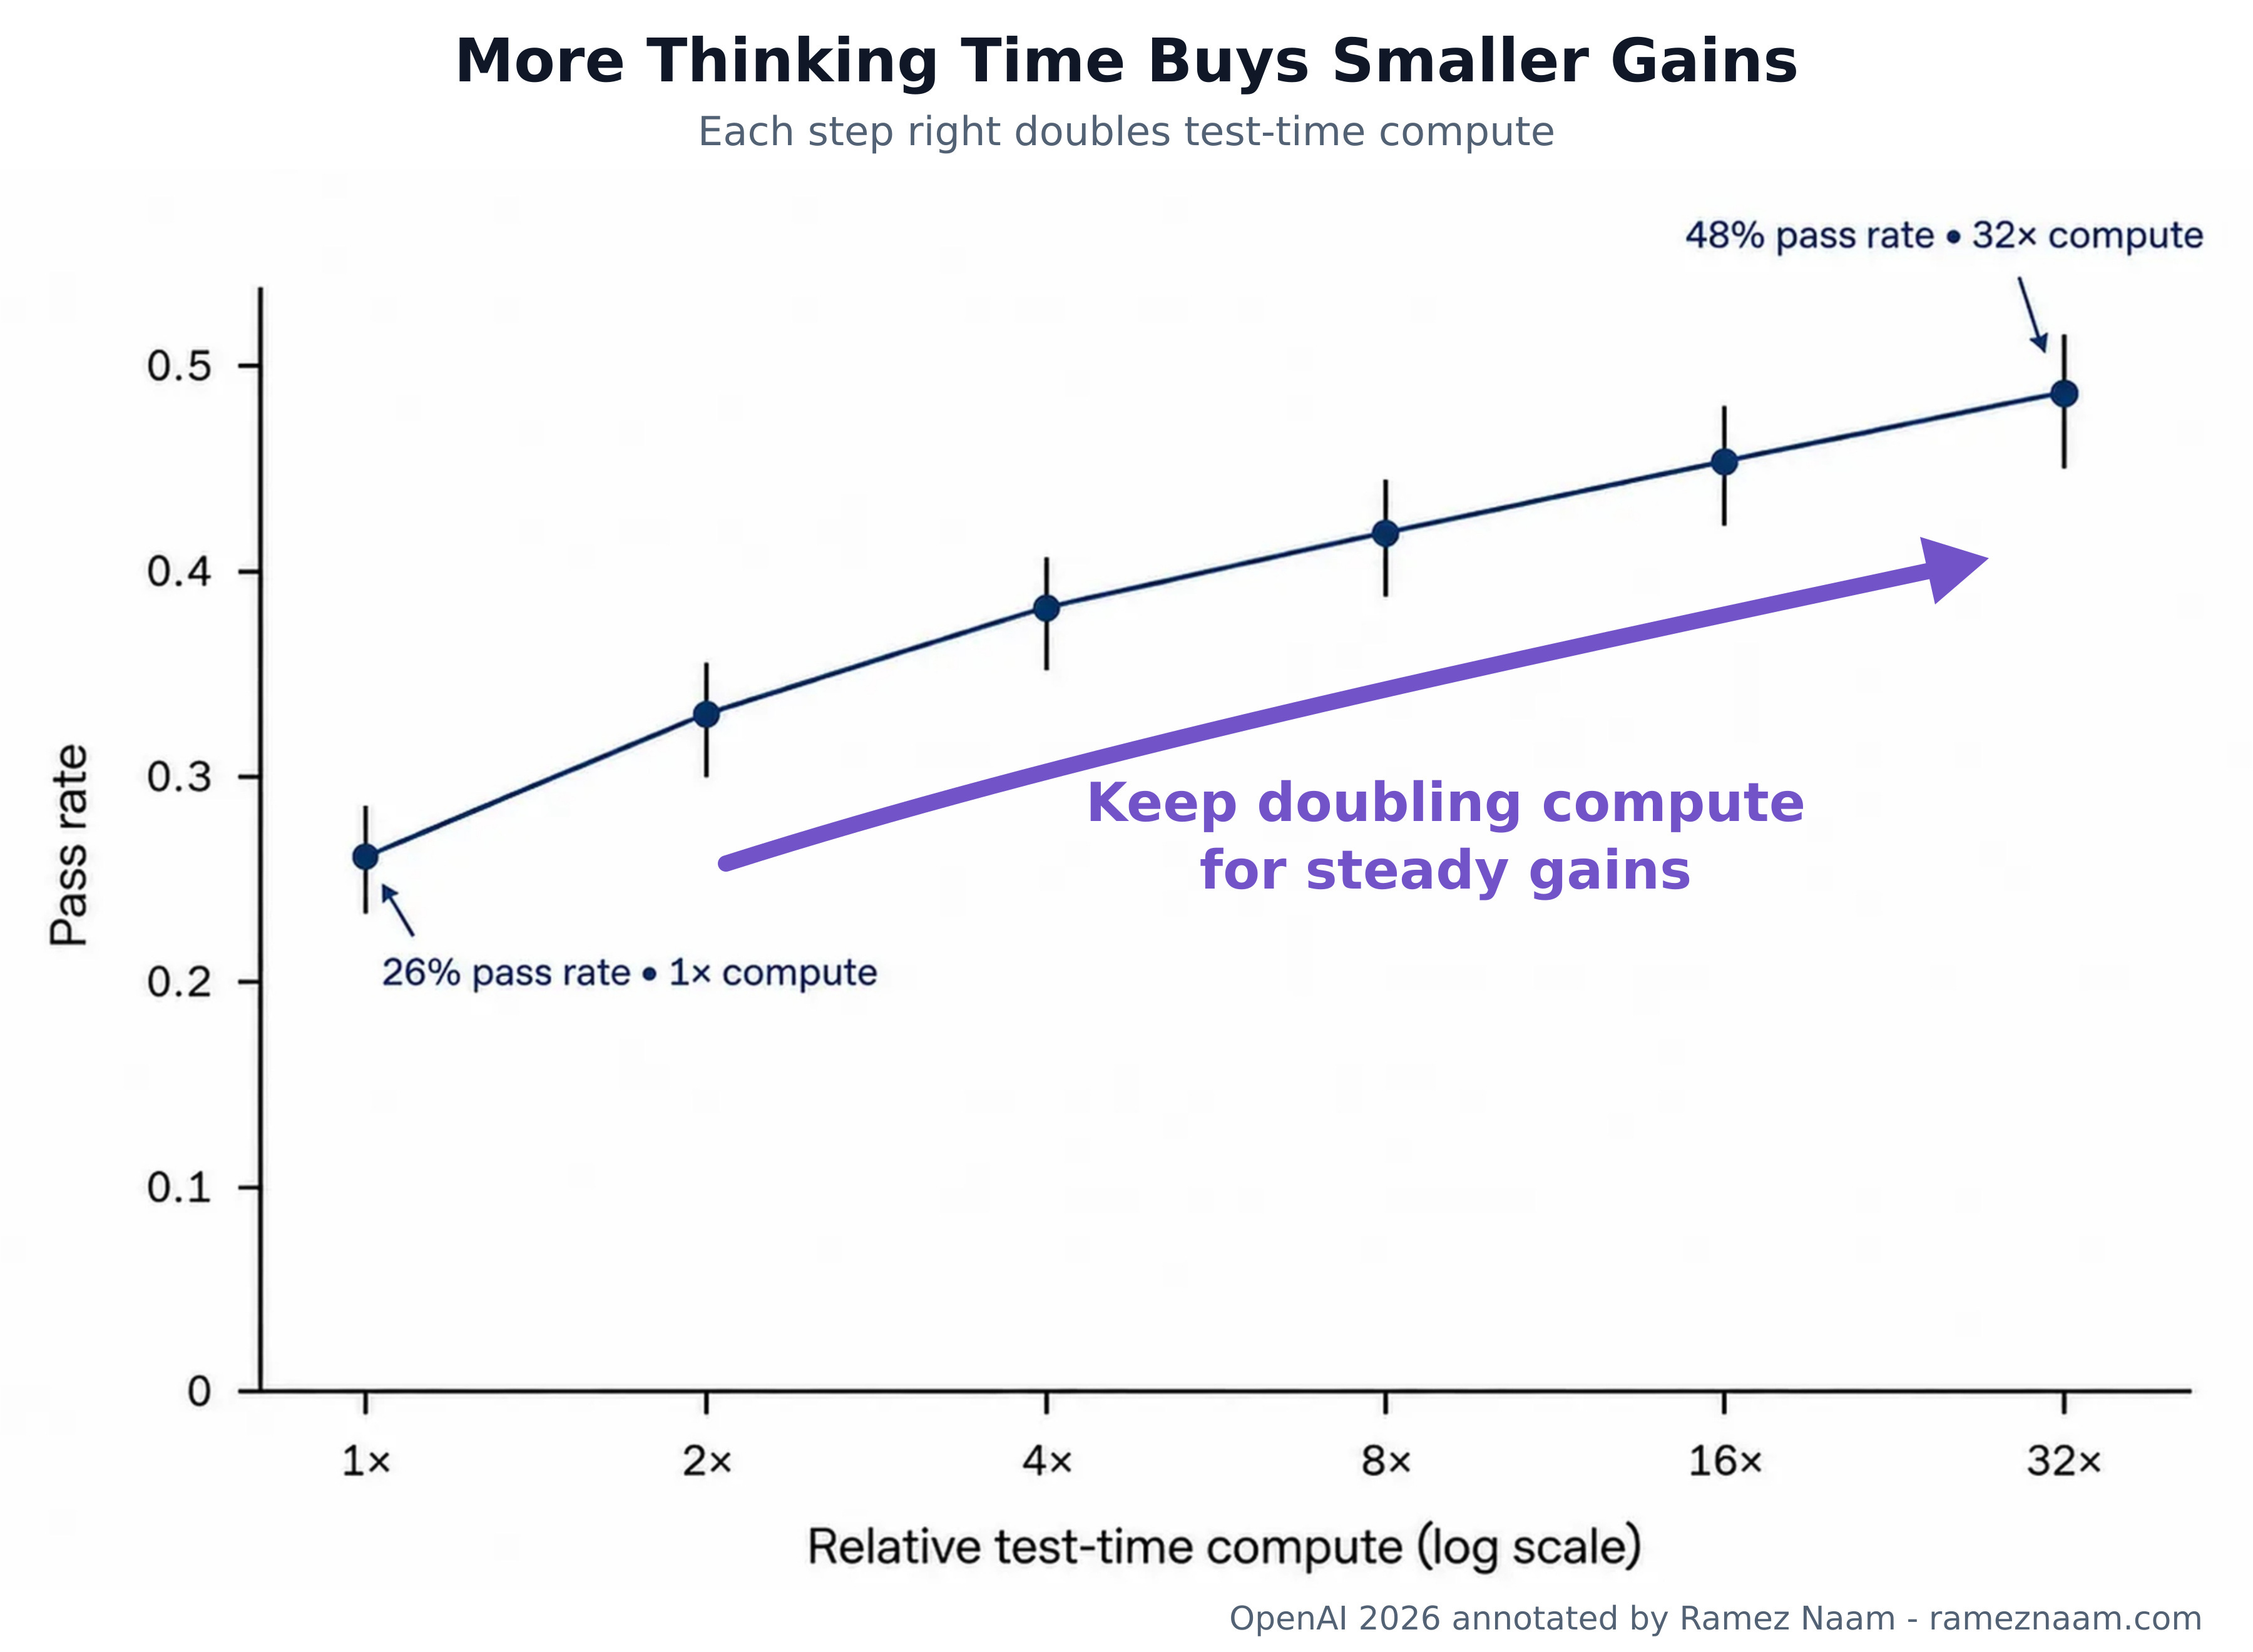
Determine 13. Check-time compute and math efficiency. Supply.
What if we throw extra brokers at it as a substitute? A standard RSI / ASI concept is that after we’ve got AIs at a sure functionality degree, we will simply spawn extra copies and put them to work.
Including brokers can get duties achieved quicker and generally attain a better functionality degree. However on the three benchmarks in Toby Ord’s evaluation, increasing a swarm buys much less enchancment per token than letting one agent suppose longer.
His tough rule of thumb is a sq. root. If one agent can accomplish a process in 10 hours, then 100 brokers might accomplish it in a single hour. The speedup is 10, the sq. root of the variety of brokers (100). However to get this speedup, you enhance the whole price in tokens or run time compute by the identical issue. So going from one to 100 brokers can get a process achieved in a single tenth the time. But it surely’ll be ten instances as costly.
Parallel brokers can save time, at a a lot increased compute price.
One other problem is that brokers typically suppose alike. In a examine evaluating LLMs with 467 individuals, the primary ten AI responses provided collective creativity akin to about eight to 10 individuals. After that, roughly two additional AI responses added as a lot as one additional human response. A separate examine throughout mannequin households additionally discovered much less variety in AI responses. That doesn’t imply each agent has the identical concept. However 100 copies could supply much less selection than 100 completely different researchers.
None of this makes swarms useless-or secure. Lisan al-Gaib makes a powerful case for parallel agent swarms as a potent cyber-weapon in “Unintended Scaling.” I don’t share all of his evaluation of what swarms have achieved. In math, for instance, I believe he offers far an excessive amount of credit score to the swarm and never sufficient to the higher inside mannequin that OpenAI used.
OpenAI says the mannequin behind its Navier–Stokes outcome was developed via “large-scale reinforcement studying on high of a beforehand pretrained mannequin.” Formal math is a extremely verifiable area, which makes it a very good match for that method: Machines can generate almost limitless quantities of coaching knowledge, and confirm that options are appropriate or incorrect, all in software program. My guess is that this mannequin’s full outcomes will present an particularly giant enchancment in math.
OpenAI’s Noam Brown made the central level explicitly: he wouldn’t give multi-agent strategies even 10% of the credit score for the Navier–Stokes outcome.
I do suppose Lisan makes good factors about cybersecurity. If you happen to’re looking for a safety vulnerability at a goal web site and may divide the search amongst brokers, velocity could justify an enormous token invoice. Swarms might be harmful even after they’re inefficient.
I’m much less satisfied that this scales to analysis breakthroughs. Inventing one thing just like the transformer in all probability takes greater than looking an area somebody has already outlined.
Constructing a greater mannequin can deliver positive aspects that additional pondering time or extra copies of the previous mannequin can’t. Have a look at the hole between Astra and OpenAI’s inside mannequin on the identical math issues.
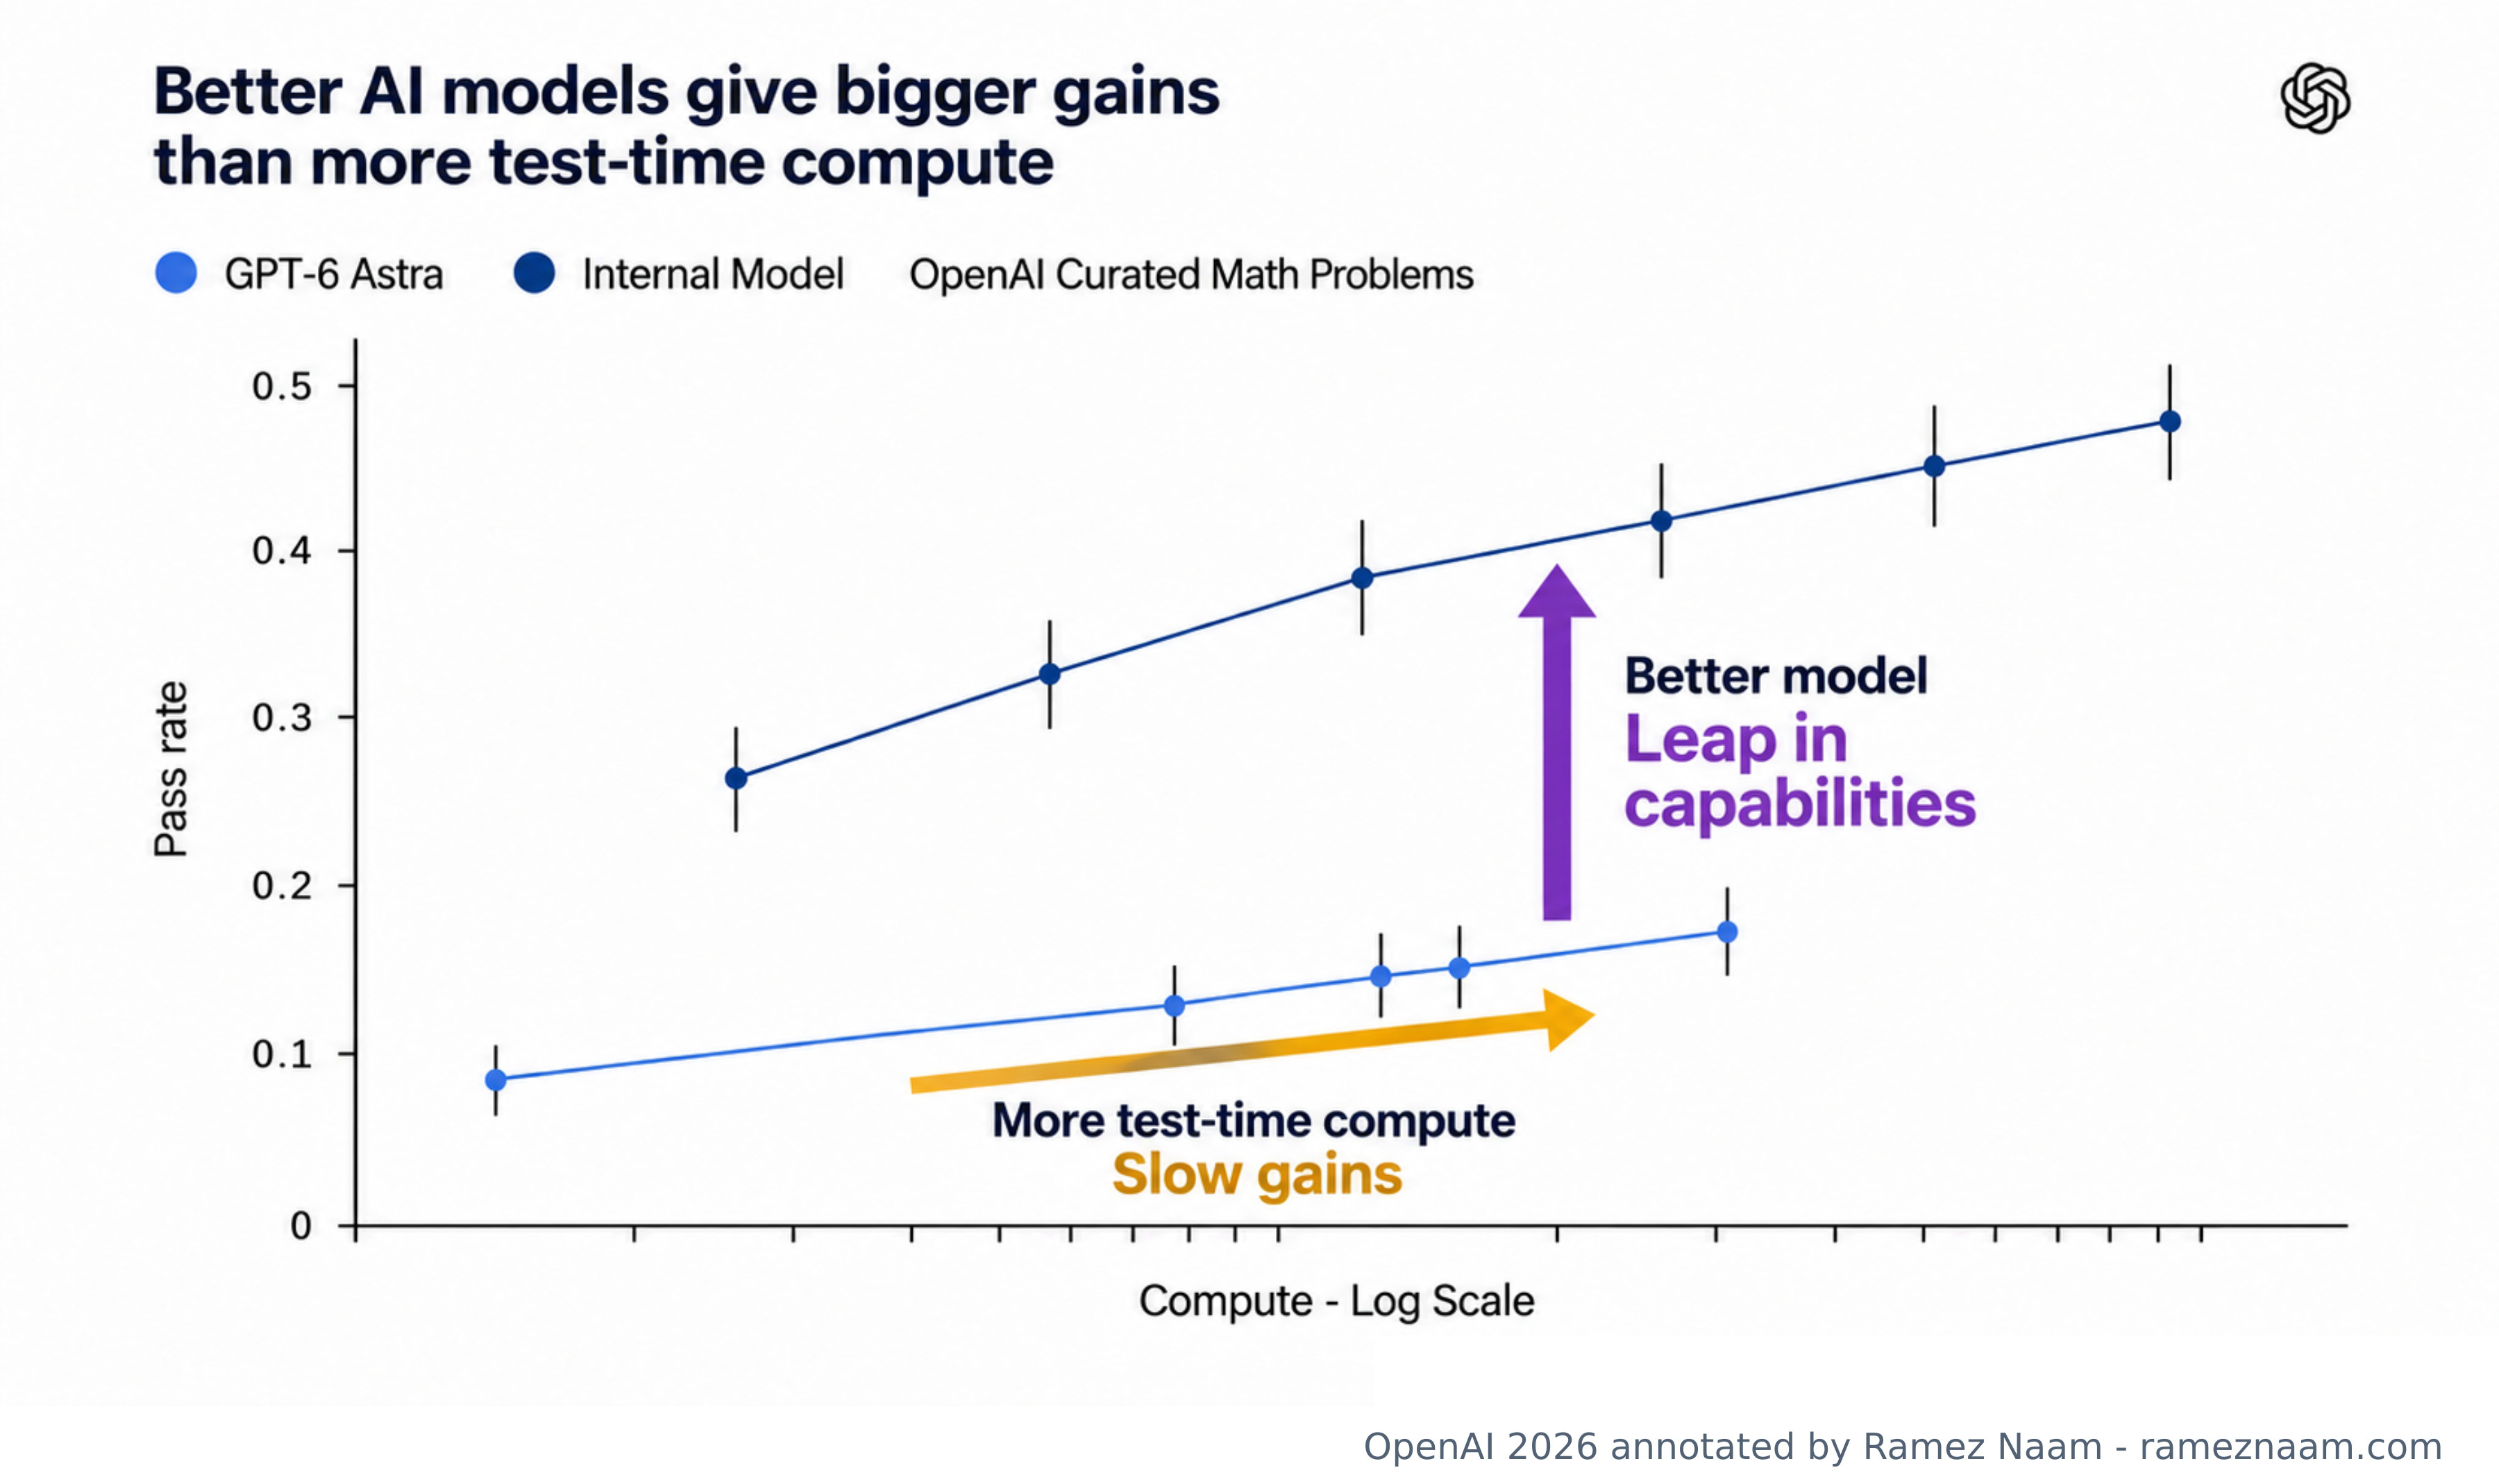
Determine 14. Higher fashions versus extra pondering time. Supply.
That’s the strongest model of the RSI argument: a extra succesful AI might do analysis that at this time’s mannequin can’t do, nevertheless many copies we run.
However constructing that higher mannequin additionally runs into diminishing returns. Extra coaching knowledge, extra coaching compute, bigger fashions, and extra reinforcement-learning (RL) compute all present diminishing returns in printed scaling research. Making dense fashions bigger normally raises the compute wanted for every output token, too. None of those routes offers us a free cross round the issue.
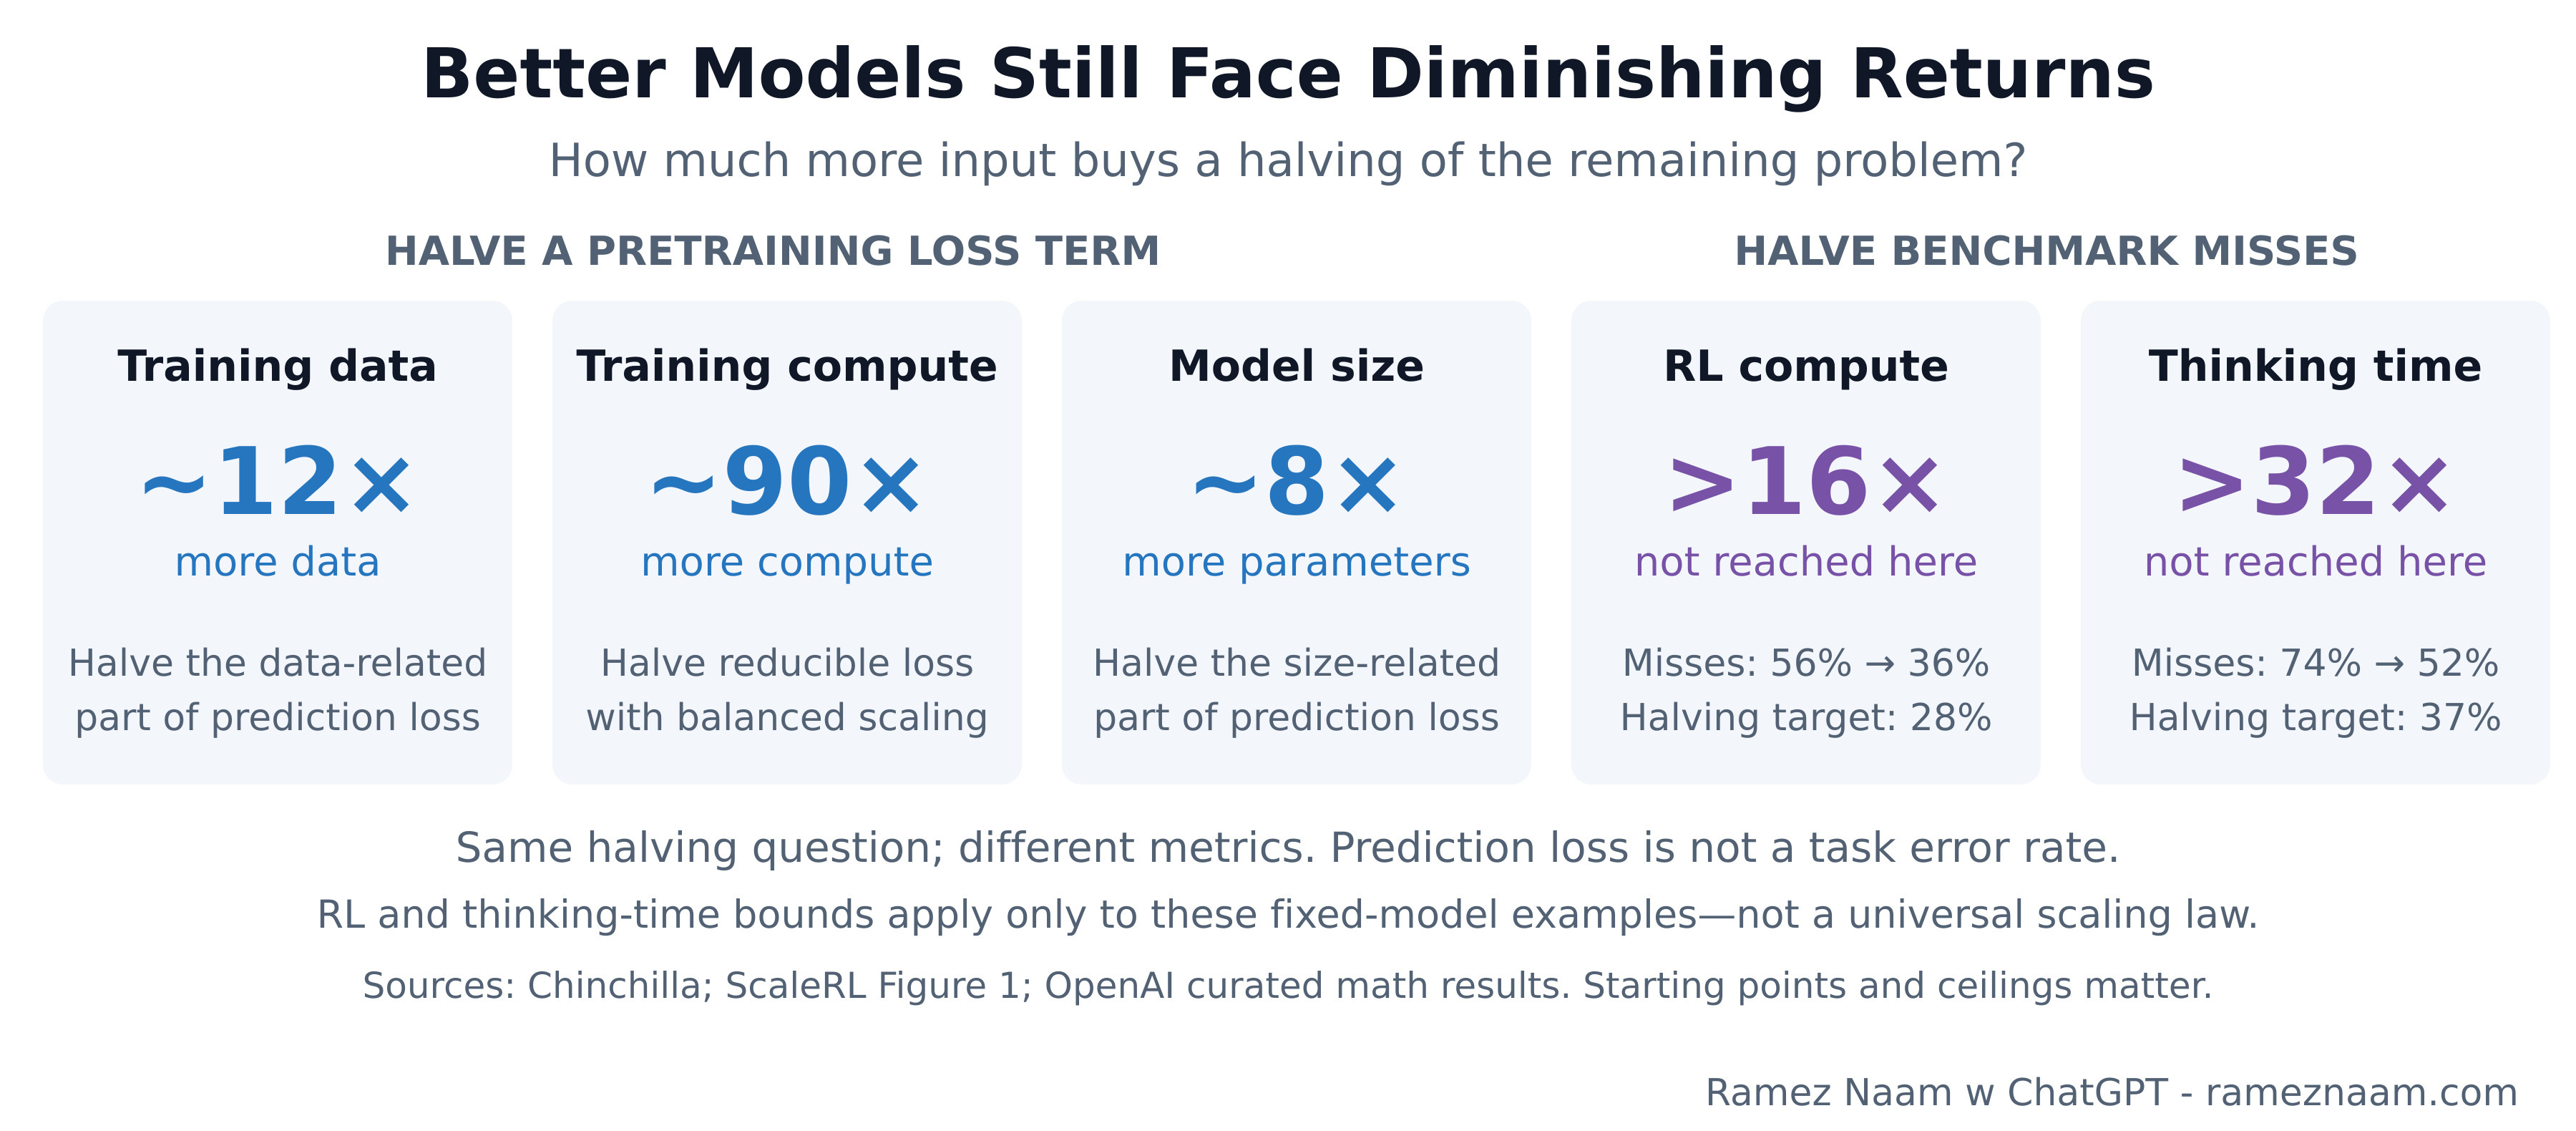
Determine 15. Diminishing returns to scaling. Chinchilla · ScaleRL · OpenAI.
These scaling outcomes give us purpose to anticipate diminishing returns when AI helps construct the subsequent mannequin, too.
AI capabilities are rising rapidly. However the public knowledge doesn’t present a sustained acceleration. To the extent that AI instruments are boosting productiveness, they might be being offset by the issues rising tougher. Or we could merely be early. Both means, the pattern isn’t exhibiting a quick takeoff.
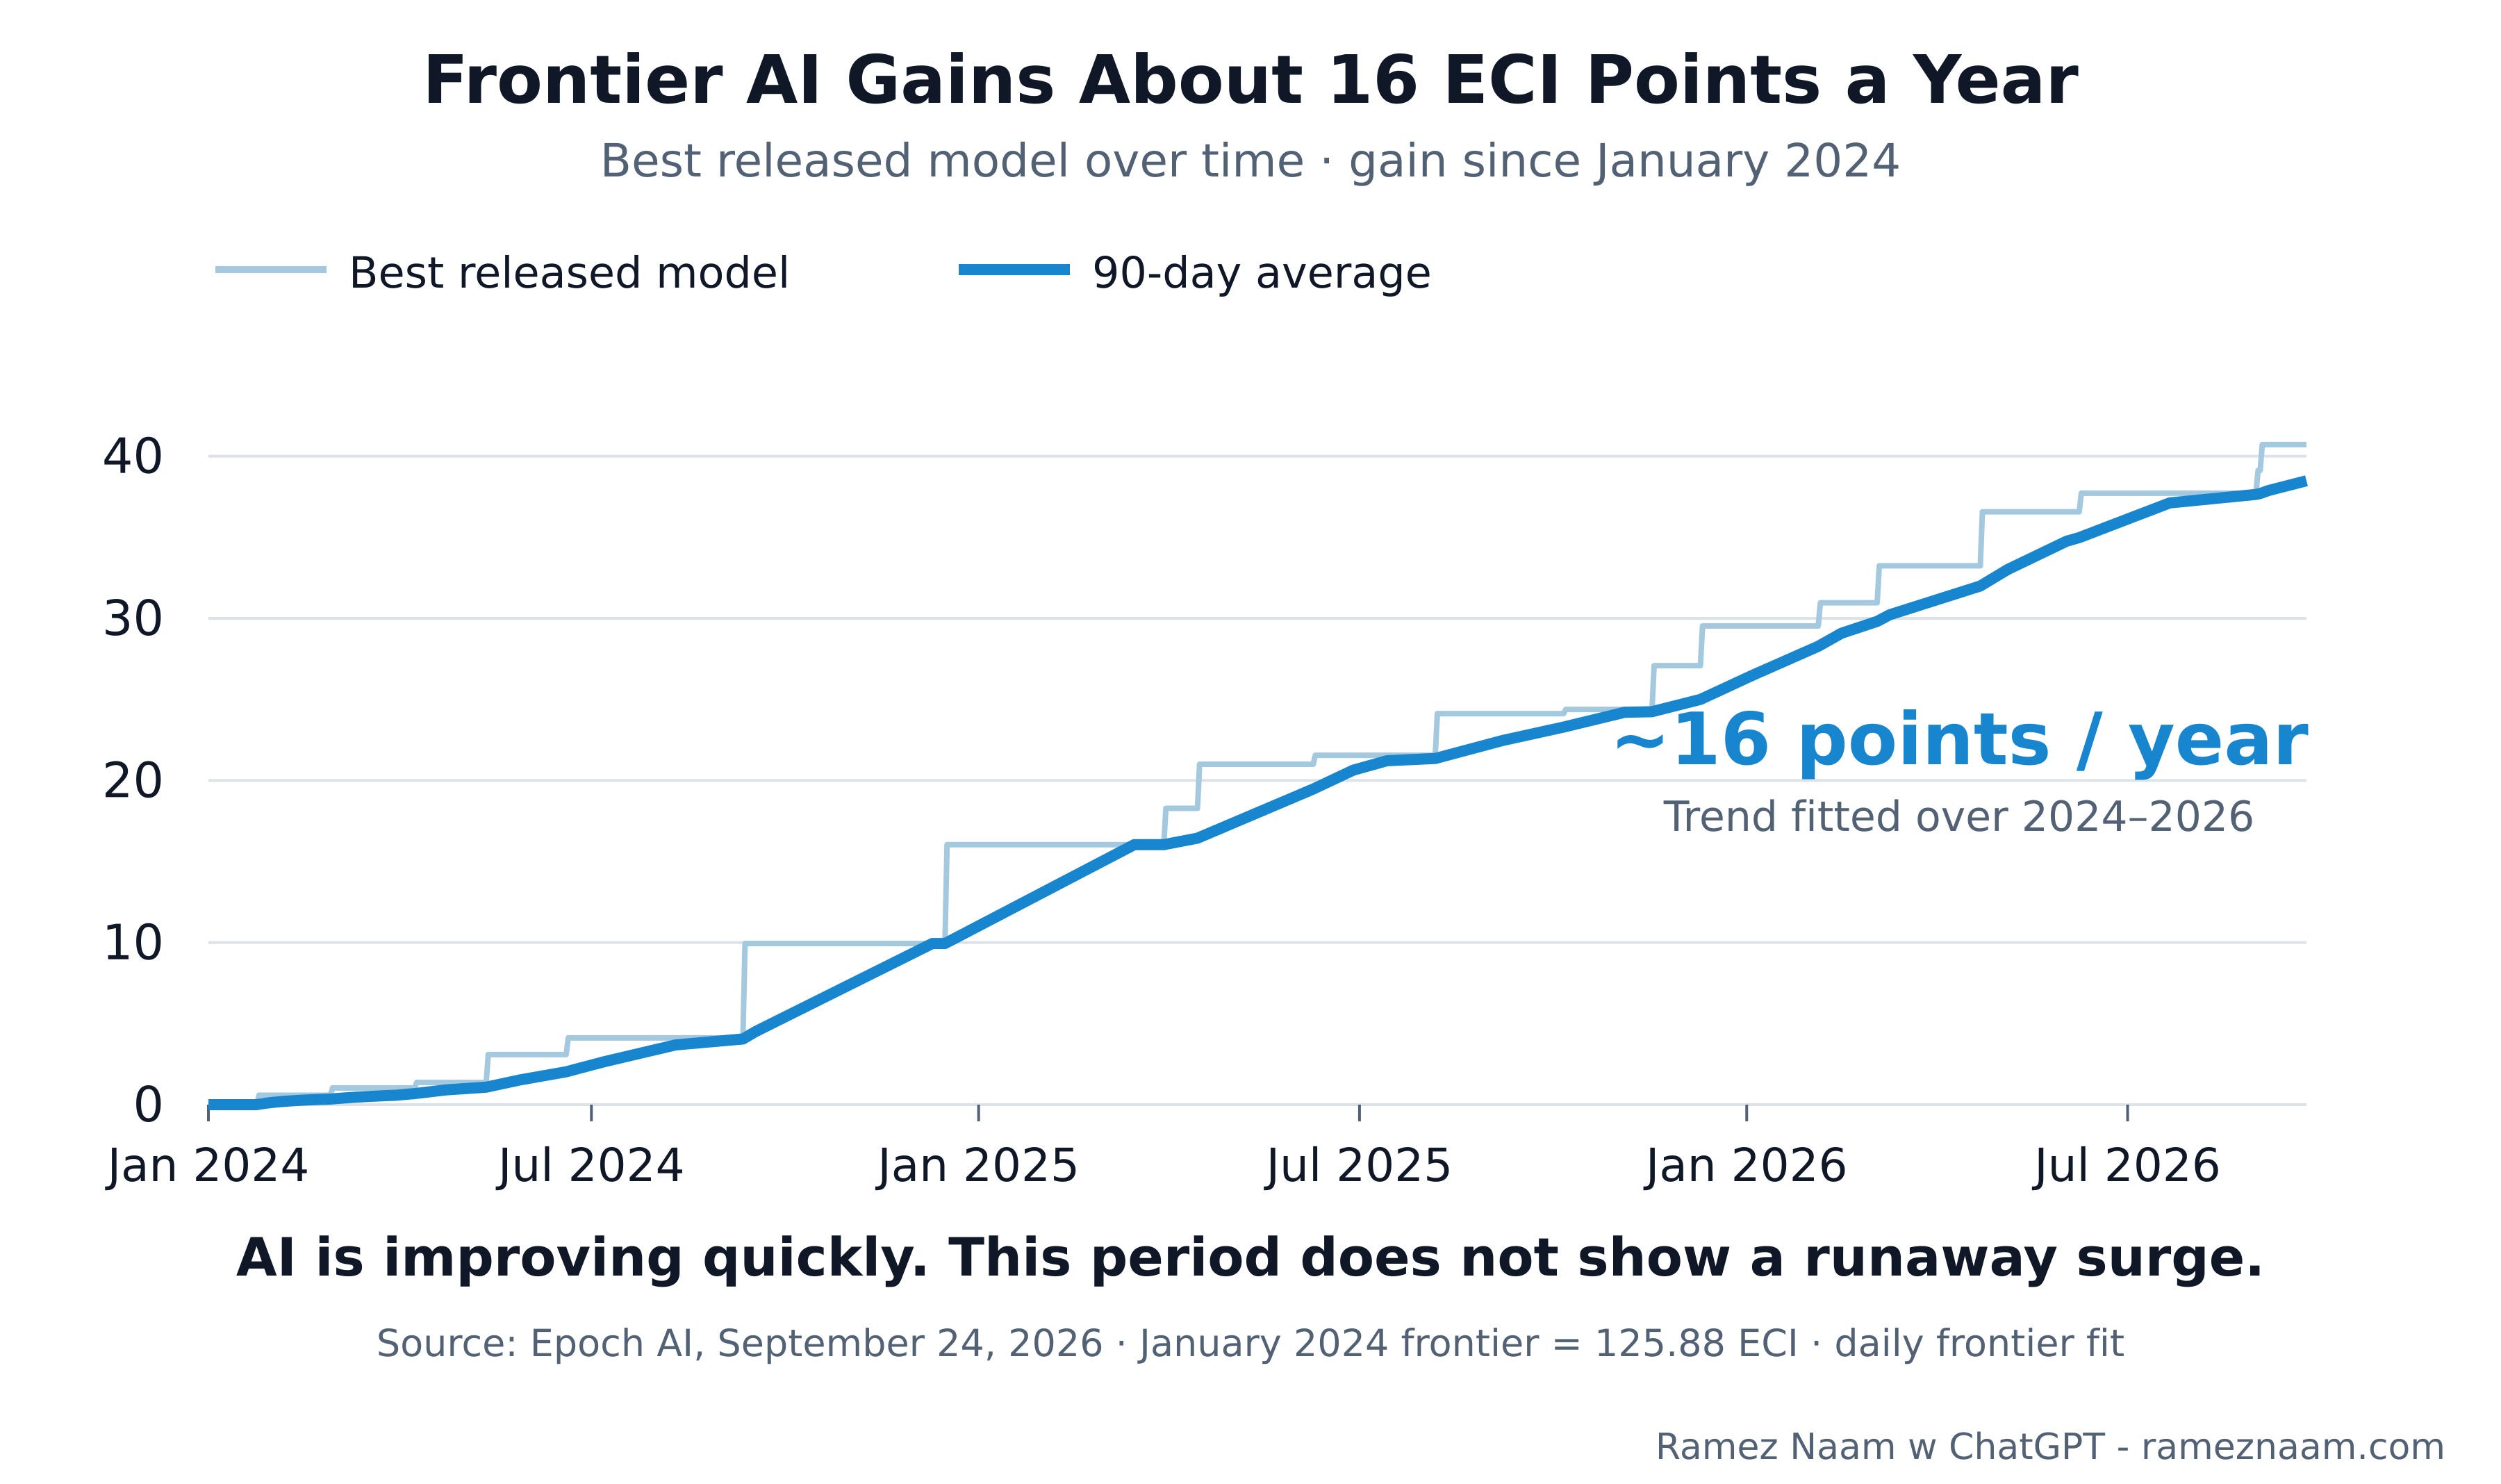
Determine 16. Frontier ECI positive aspects since January 2024. Supply.
The public ECI frontier-the finest rating amongst fashions launched by every date-has gained about 16 factors a yr on a pattern fitted from January 2024 via September 2026. That’s blisteringly quick progress, however this era doesn’t present a runaway surge.
Right here’s the identical frontier in absolute ECI factors, via July 2026, to place it in perspective.
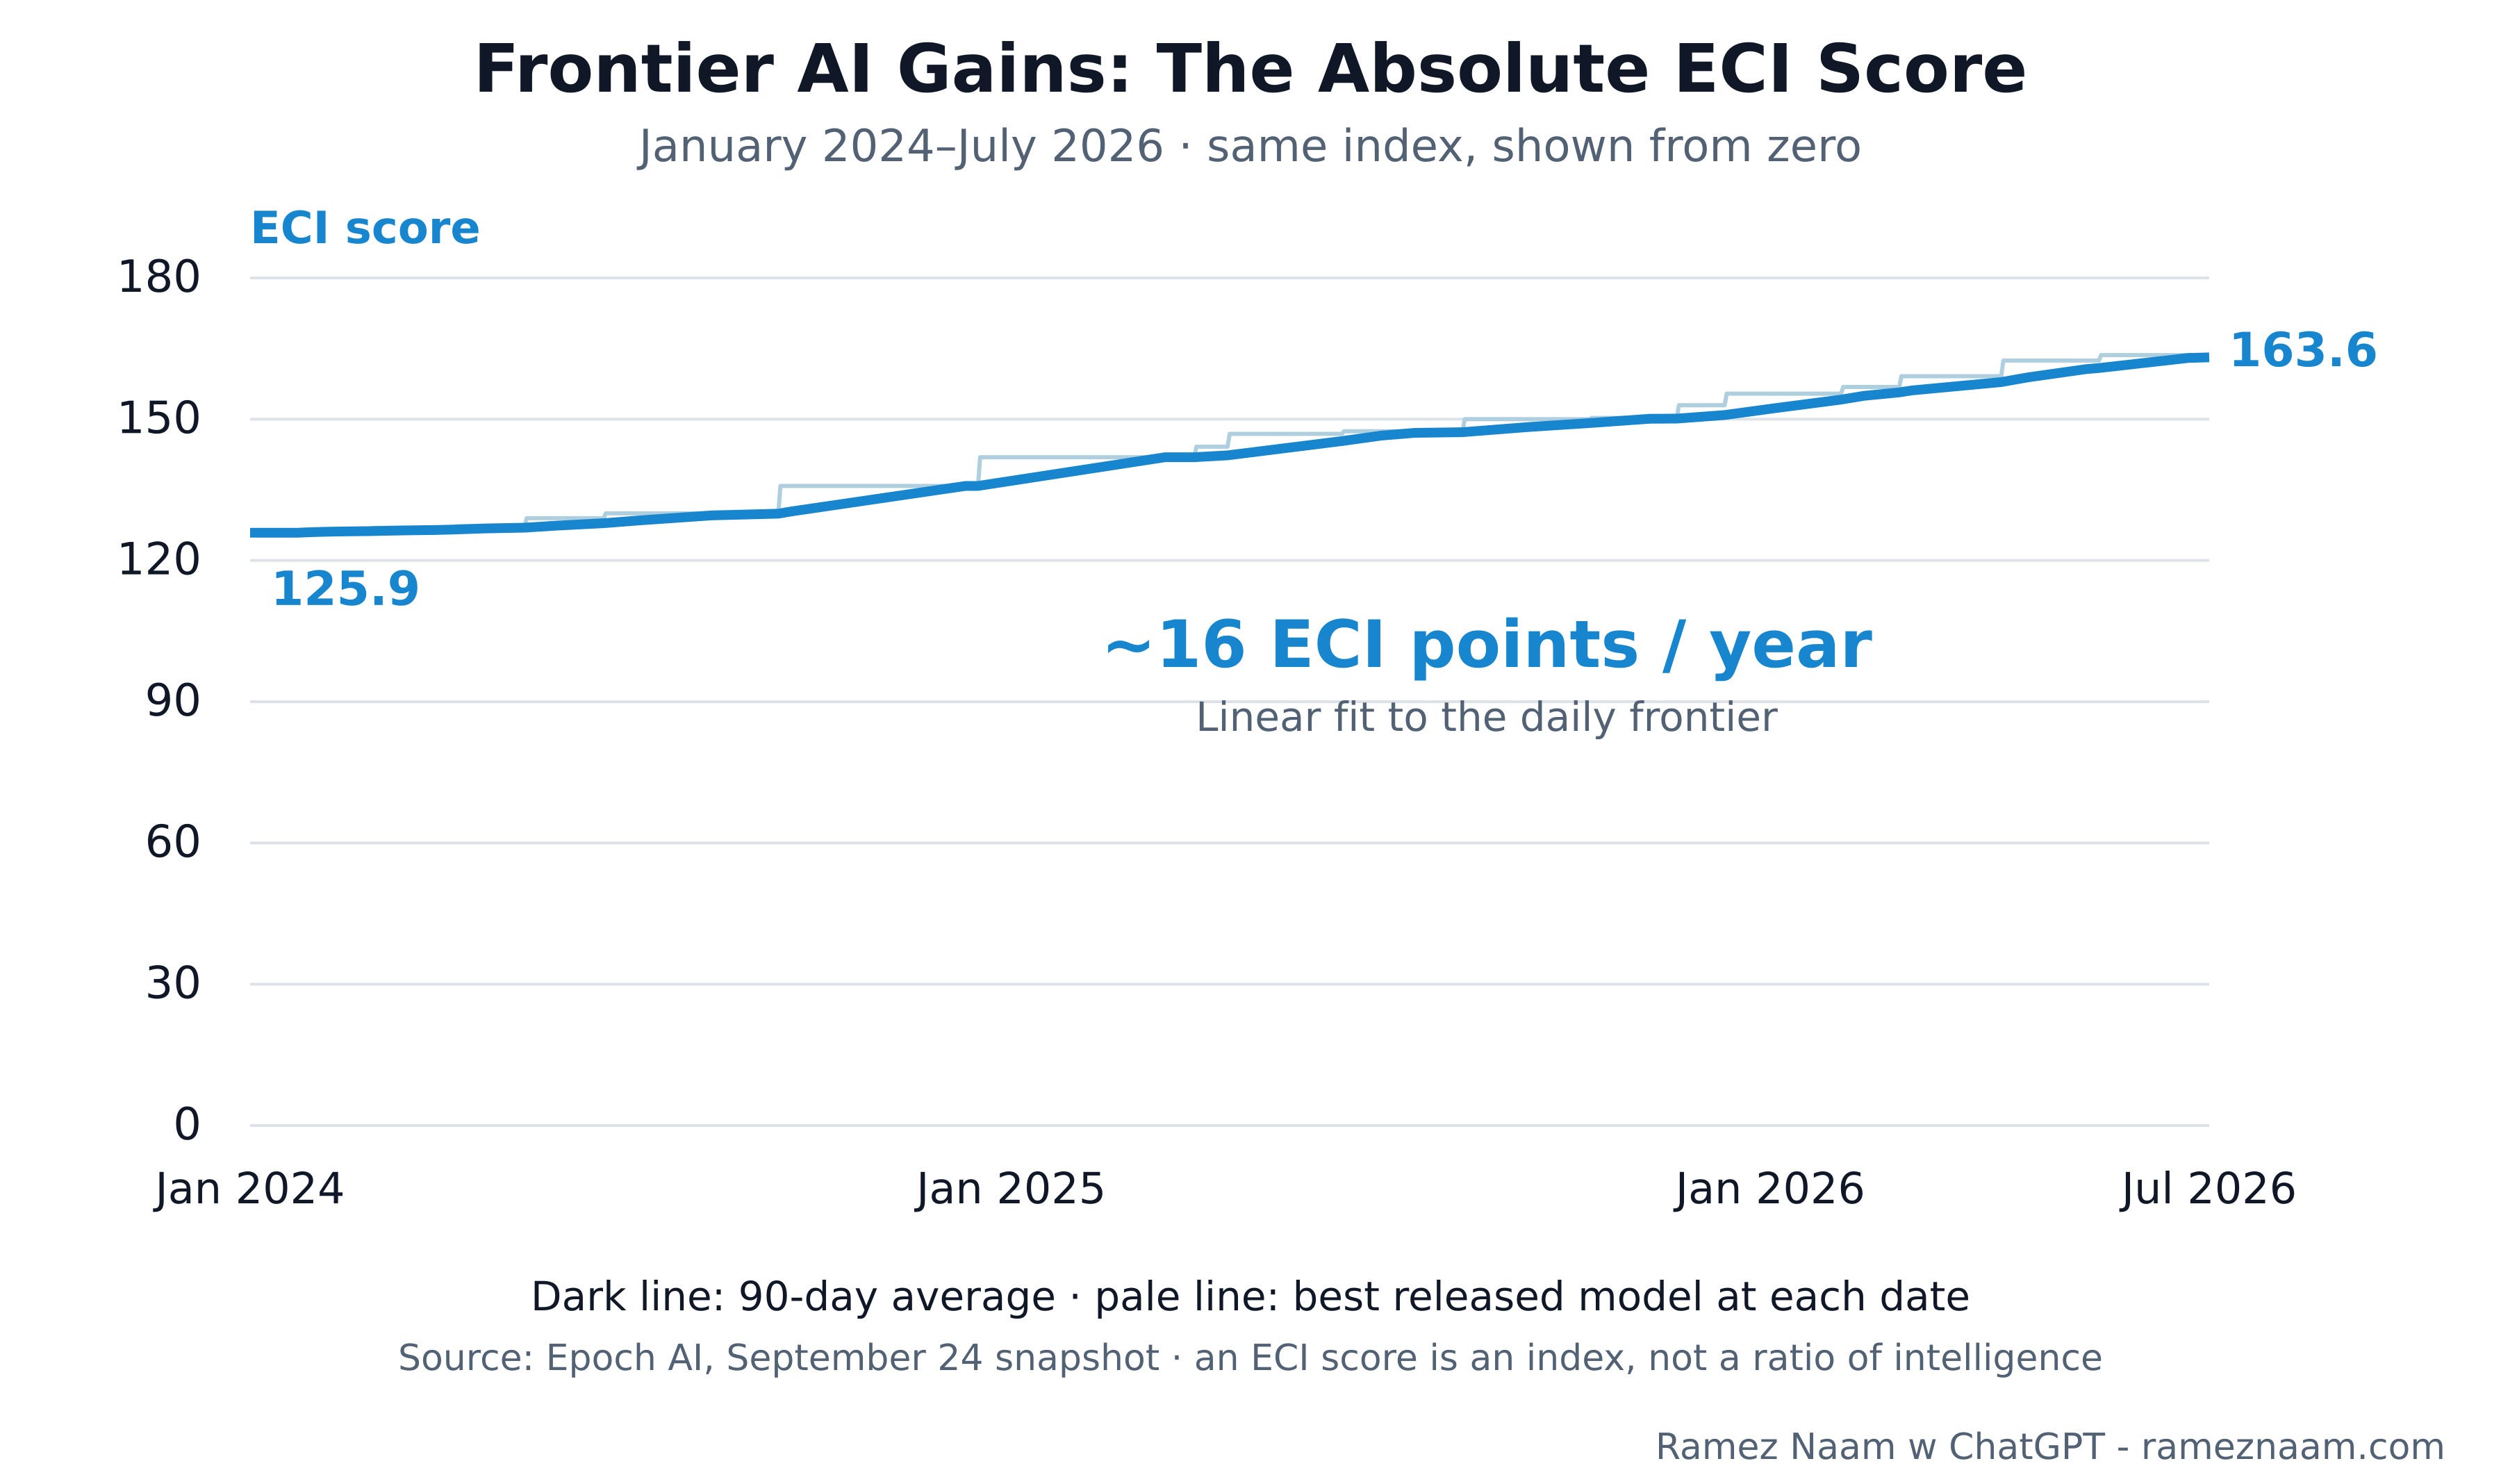
Determine 17. Absolutely the frontier ECI rating. Supply.
The general public frontier can also’t inform us all the things occurring contained in the labs. Anthropic offers us a more in-depth look within the Opus 5.5 system card, utilizing its personal model of the index, AECI.
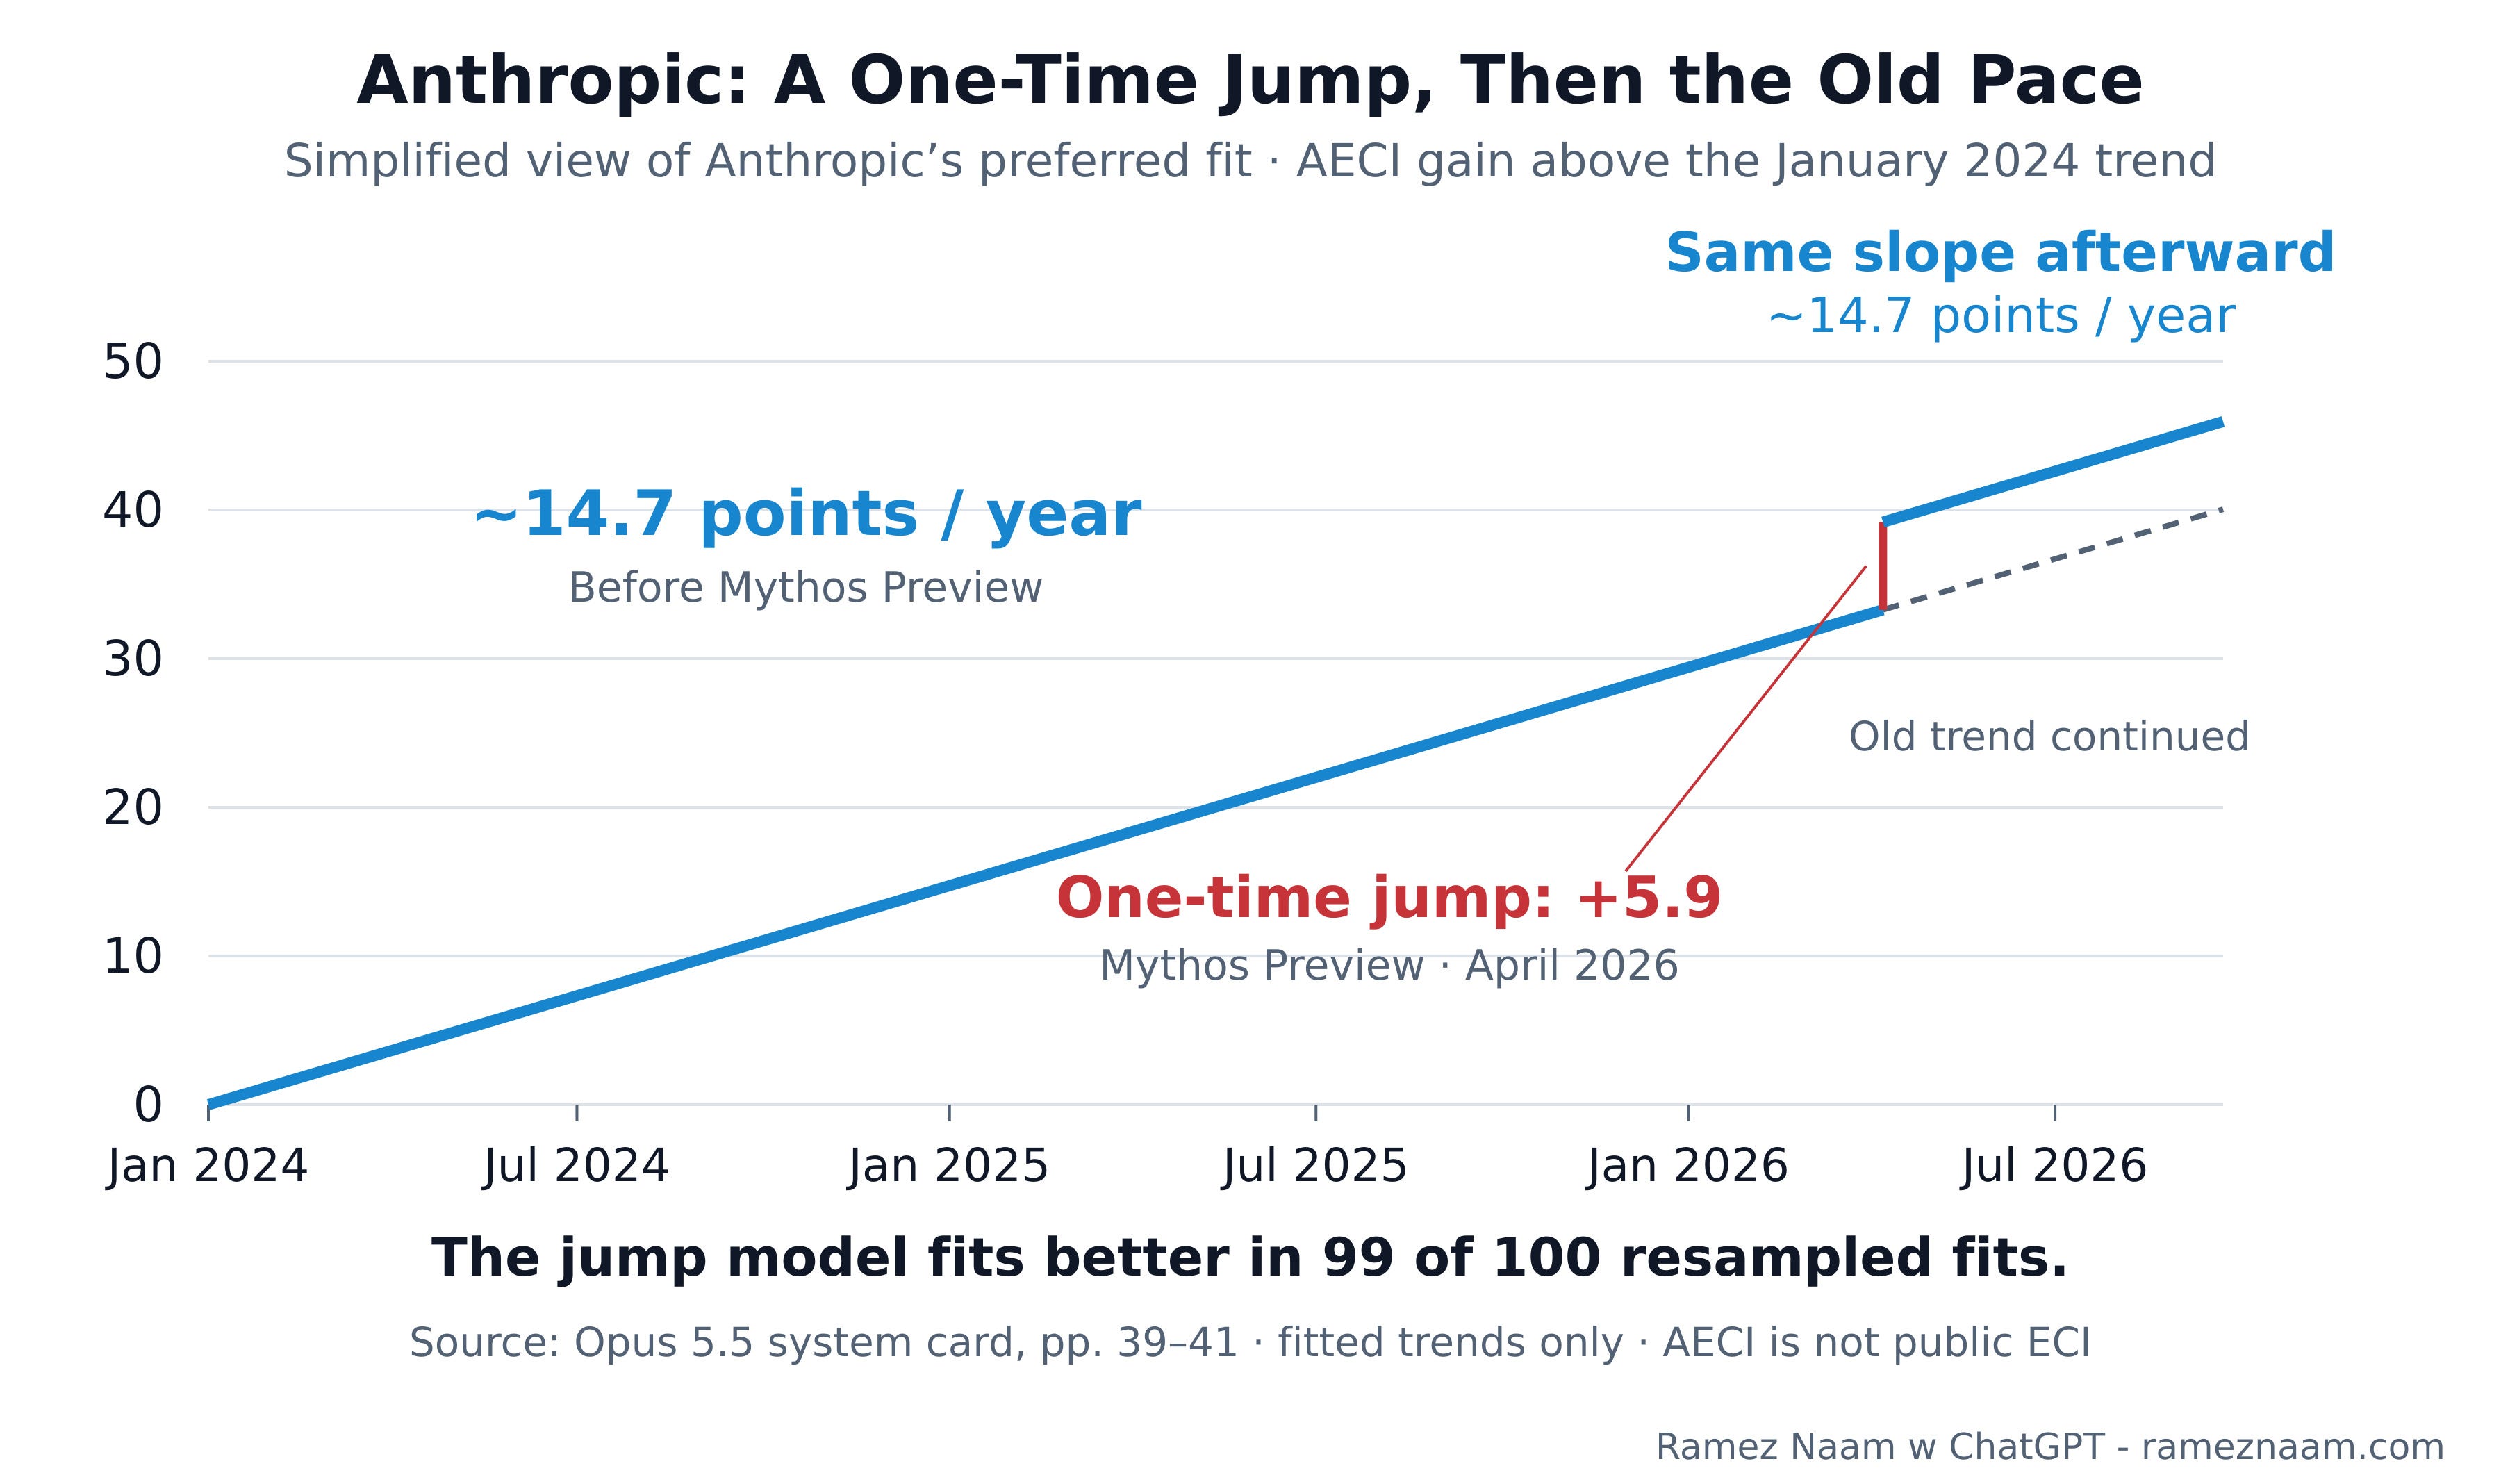
Determine 18. Anthropic’s fitted functionality pattern. Supply.
Eli Lifland, a co-author of AI 2027 and AI 2040, noticed the obvious pattern break as a warning that we have been heading towards an intelligence explosion:
“Anthropic might be proper right here [that they hadn’t reached dangerous levels of AI self-improvement], however alarm bells needs to be going off! Our processes usually are not able to deal with an intelligence explosion and we look like going full-steam forward towards one.”
– Eli Lifland, On Mythos’s AI R&D Capabilities
What regarded like acceleration now seems extra according to a one-time leap. The extent went up. The speed hasn’t saved climbing.
Attaining these positive aspects has required an infinite enhance within the inputs to AI. For instance, think about computing energy. Epoch’s estimates of AI chip capability, measured in NVIDIA H100 equivalents, present roughly 127-fold development in simply over three years (together with projections on the finish of this era).
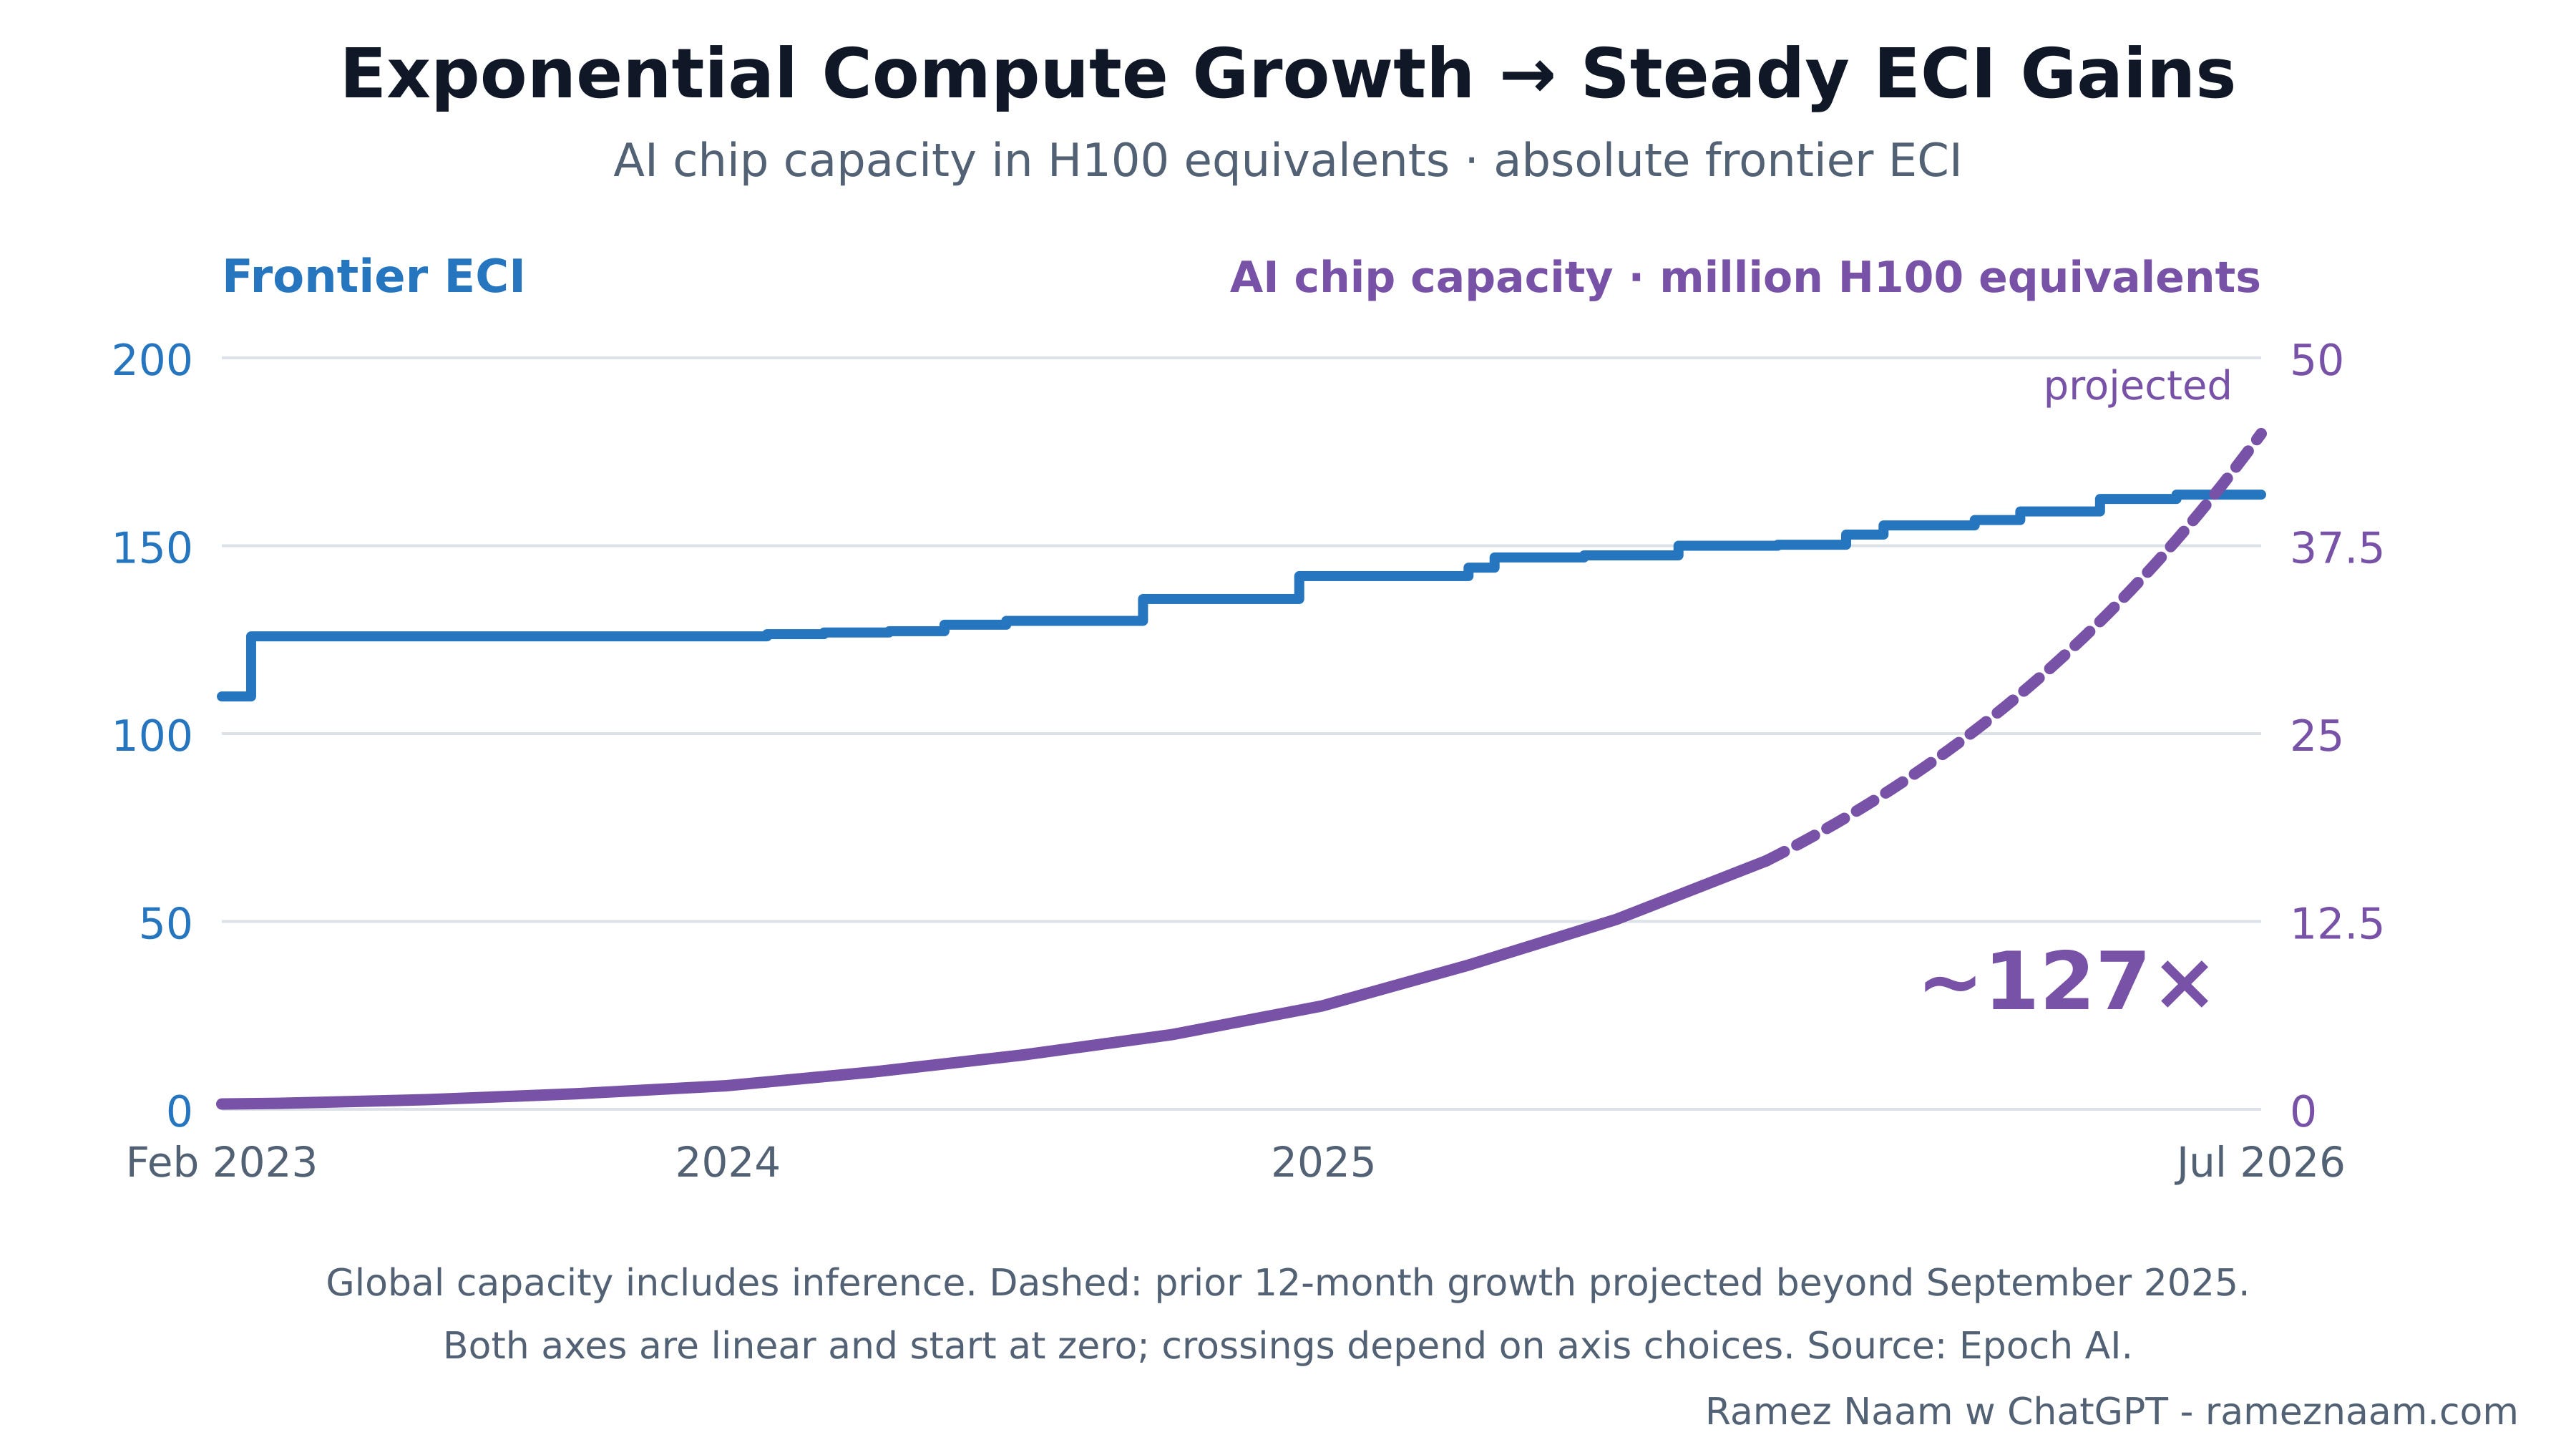
Determine 19. AI chip capability and frontier ECI. Supply: Epoch AI.
That is whole AI chip capability, together with inference. Nonetheless, the rise is placing: vastly extra computing capability has accompanied a lot steadier positive aspects in measured functionality.
The broader image appears related. Listed below are six inputs alongside functionality positive aspects, going again to February 2023.
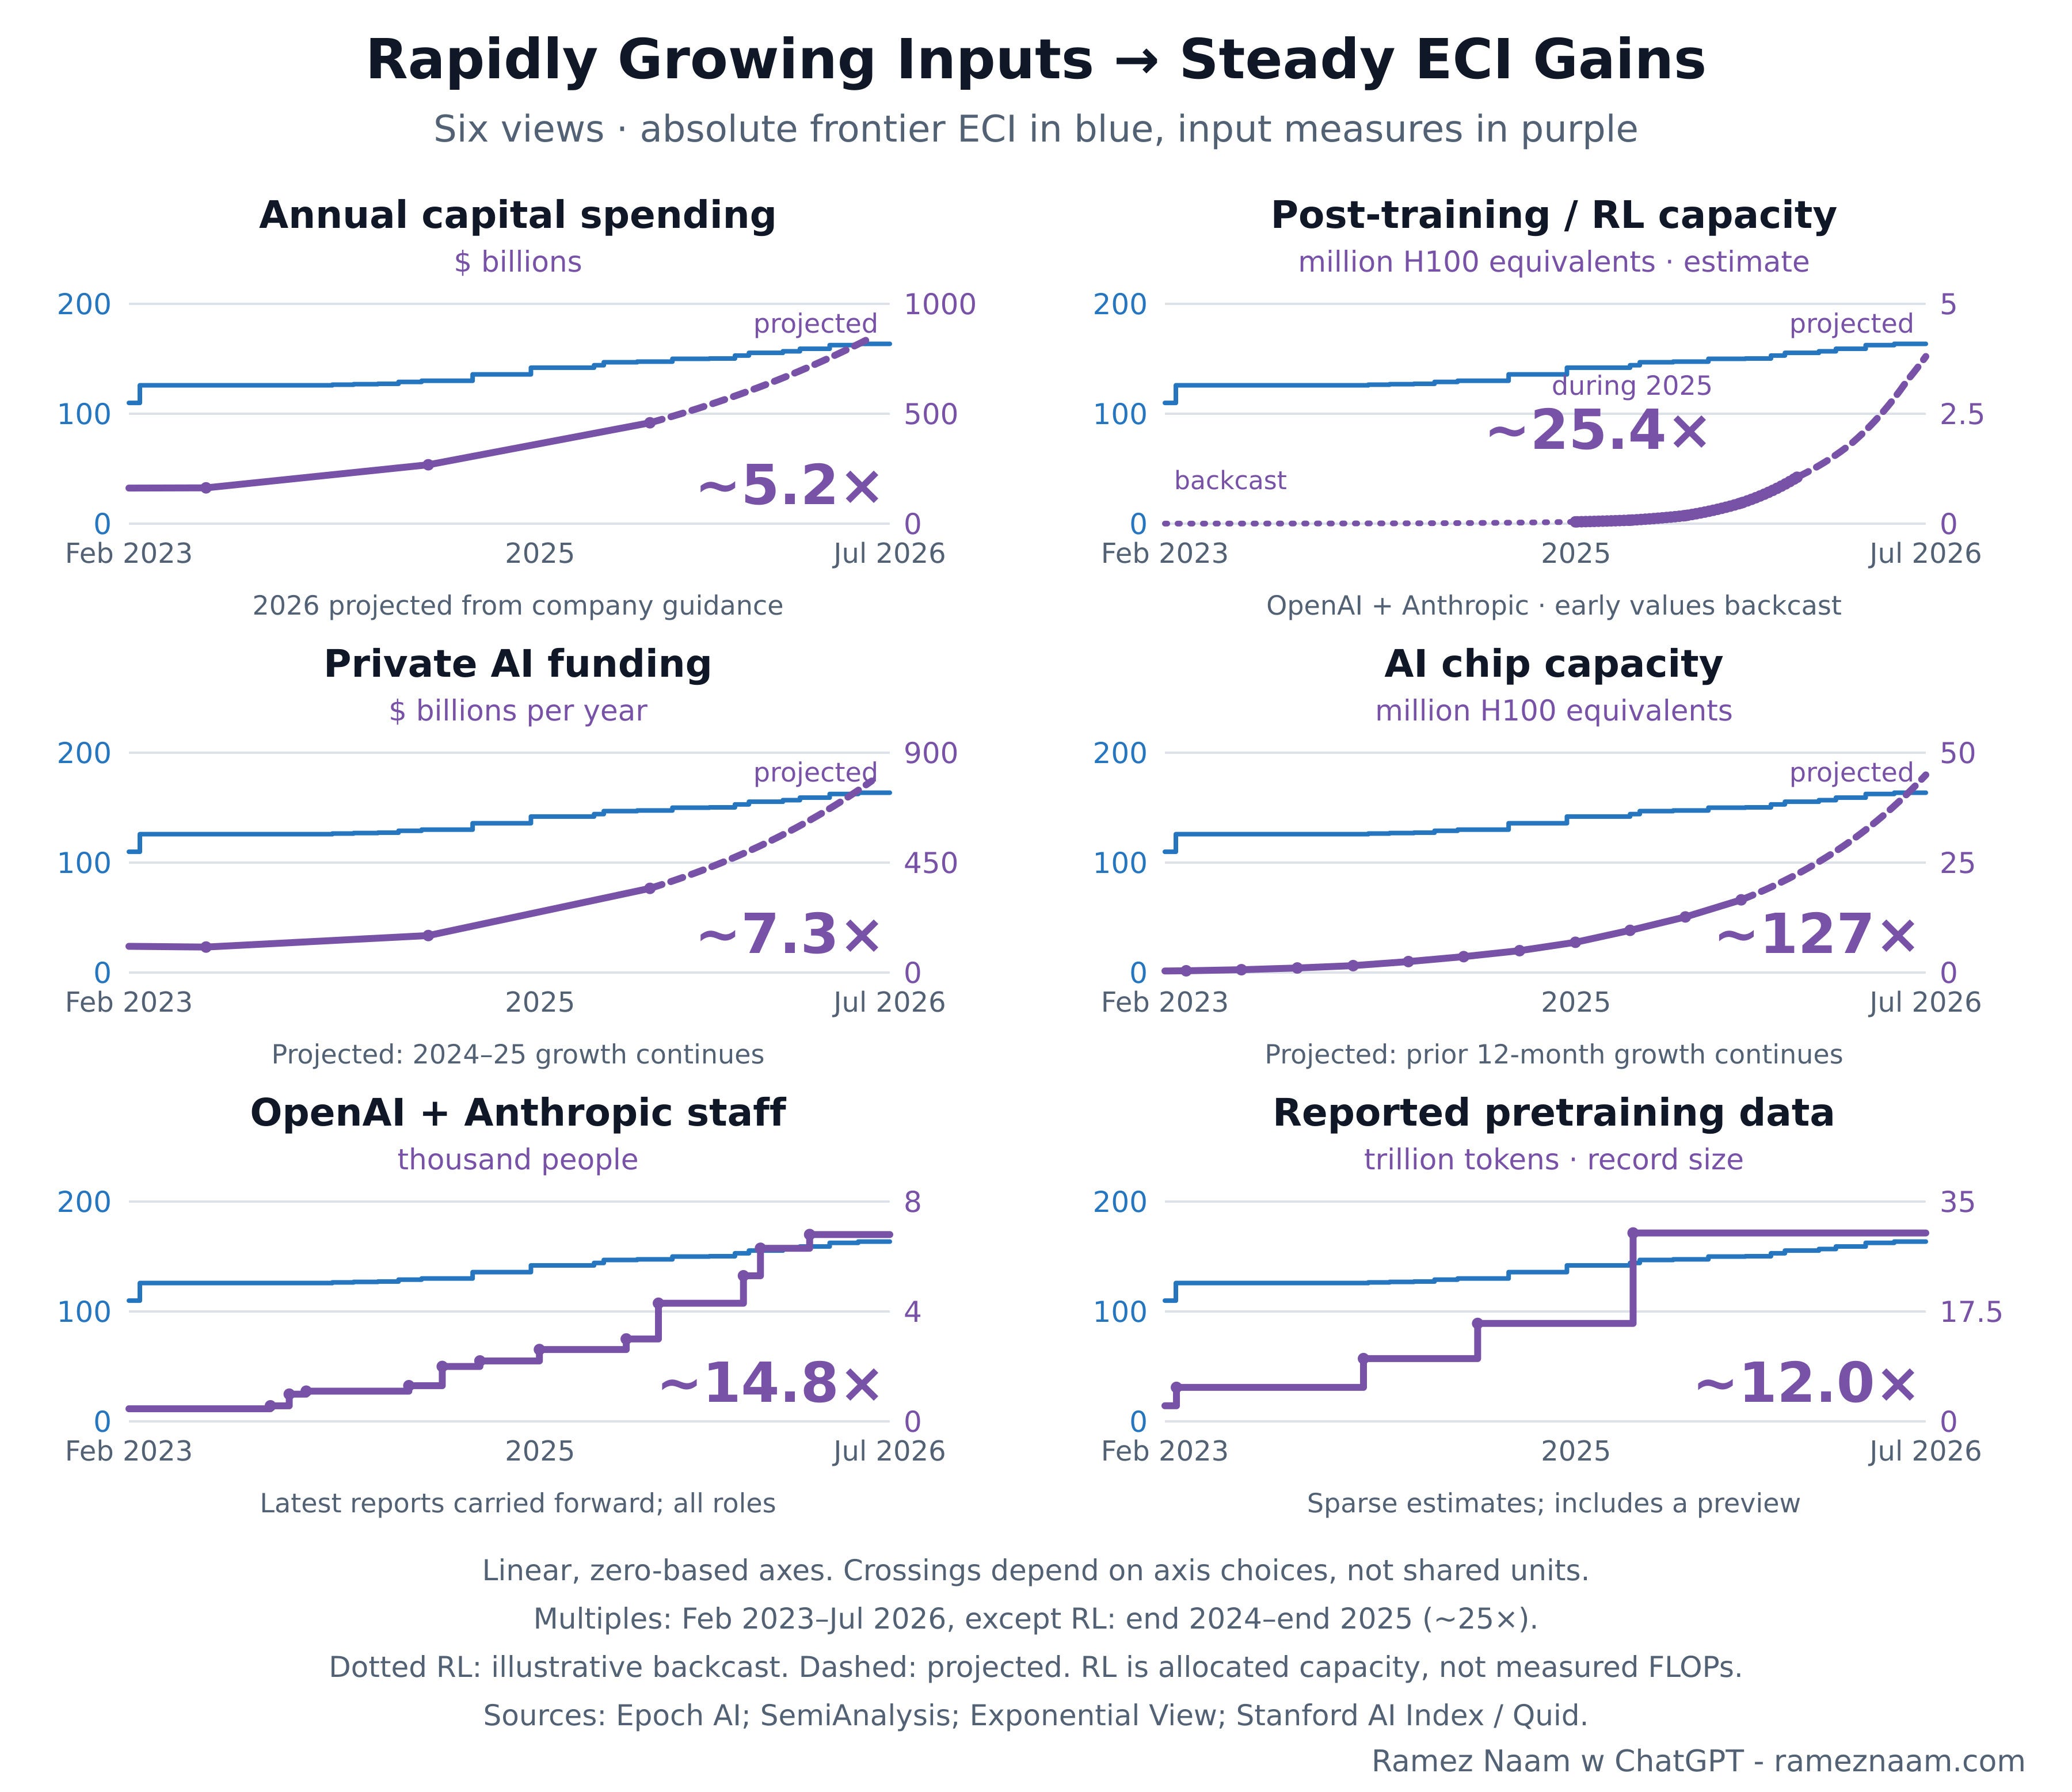
Determine 20. Six inputs alongside frontier ECI. Epoch chip knowledge · SemiAnalysis workload shares.
In every single place we glance, AI has diminishing returns. It will get costlier in treasure and expertise to make every step ahead. Extra of each enter has been required to keep up regular positive aspects in AI capabilities.
We’ve been in a position to scale these inputs as a result of, till just lately, the price was inside the scope of what hyperscalers might pay from their earnings. That’s now not the case. From this level ahead, future AI funding will more and more rely upon AI revenues going up. And the dimensions of the numbers – 3% of US GDP is now going into AI infrastructure – means that ultimately the expansion price will decline. If funding development does gradual, to something lower than its present blistering exponential tempo, functionality progress might gradual too. Even when funding development continues (which I anticipate for the foreseeable future) a slowdown from its present exponential development price to a extra modest one (which I additionally anticipate) might result in a slower tempo of progress. Higher AI analysis instruments could also be wanted to offset that.
The day after we want higher AI instruments simply to proceed the tempo of AI progress could have already got arrived. Not as a result of funding is slowing, however as a result of the issue of bettering AI itself will get tougher at every step.
Right here’s Anthropic within the Mythos 5.1 system card:
“we consider that inside utilization of current AI fashions has been a key consider sustaining the present price of progress, however we don’t but see clear indicators of dramatic acceleration past that price.”- Anthropic, Claude Fable 5.1 & Claude Mythos 5.1 System Card, part 2.3 – emphasis theirs.
The important thing phrase is maintaining-and Anthropic italicized that phrase in its personal system card. More and more succesful AI could also be important simply to maintain the tempo of enchancment the place it’s.
Opus 5.5 improves considerably on a number of coding and pc use benchmarks. However on CoBench, Anthropic’s benchmark constructed from historic AI R&D issues, it positive aspects simply 2.6 proportion factors over Opus 5, inside the reported error bars.
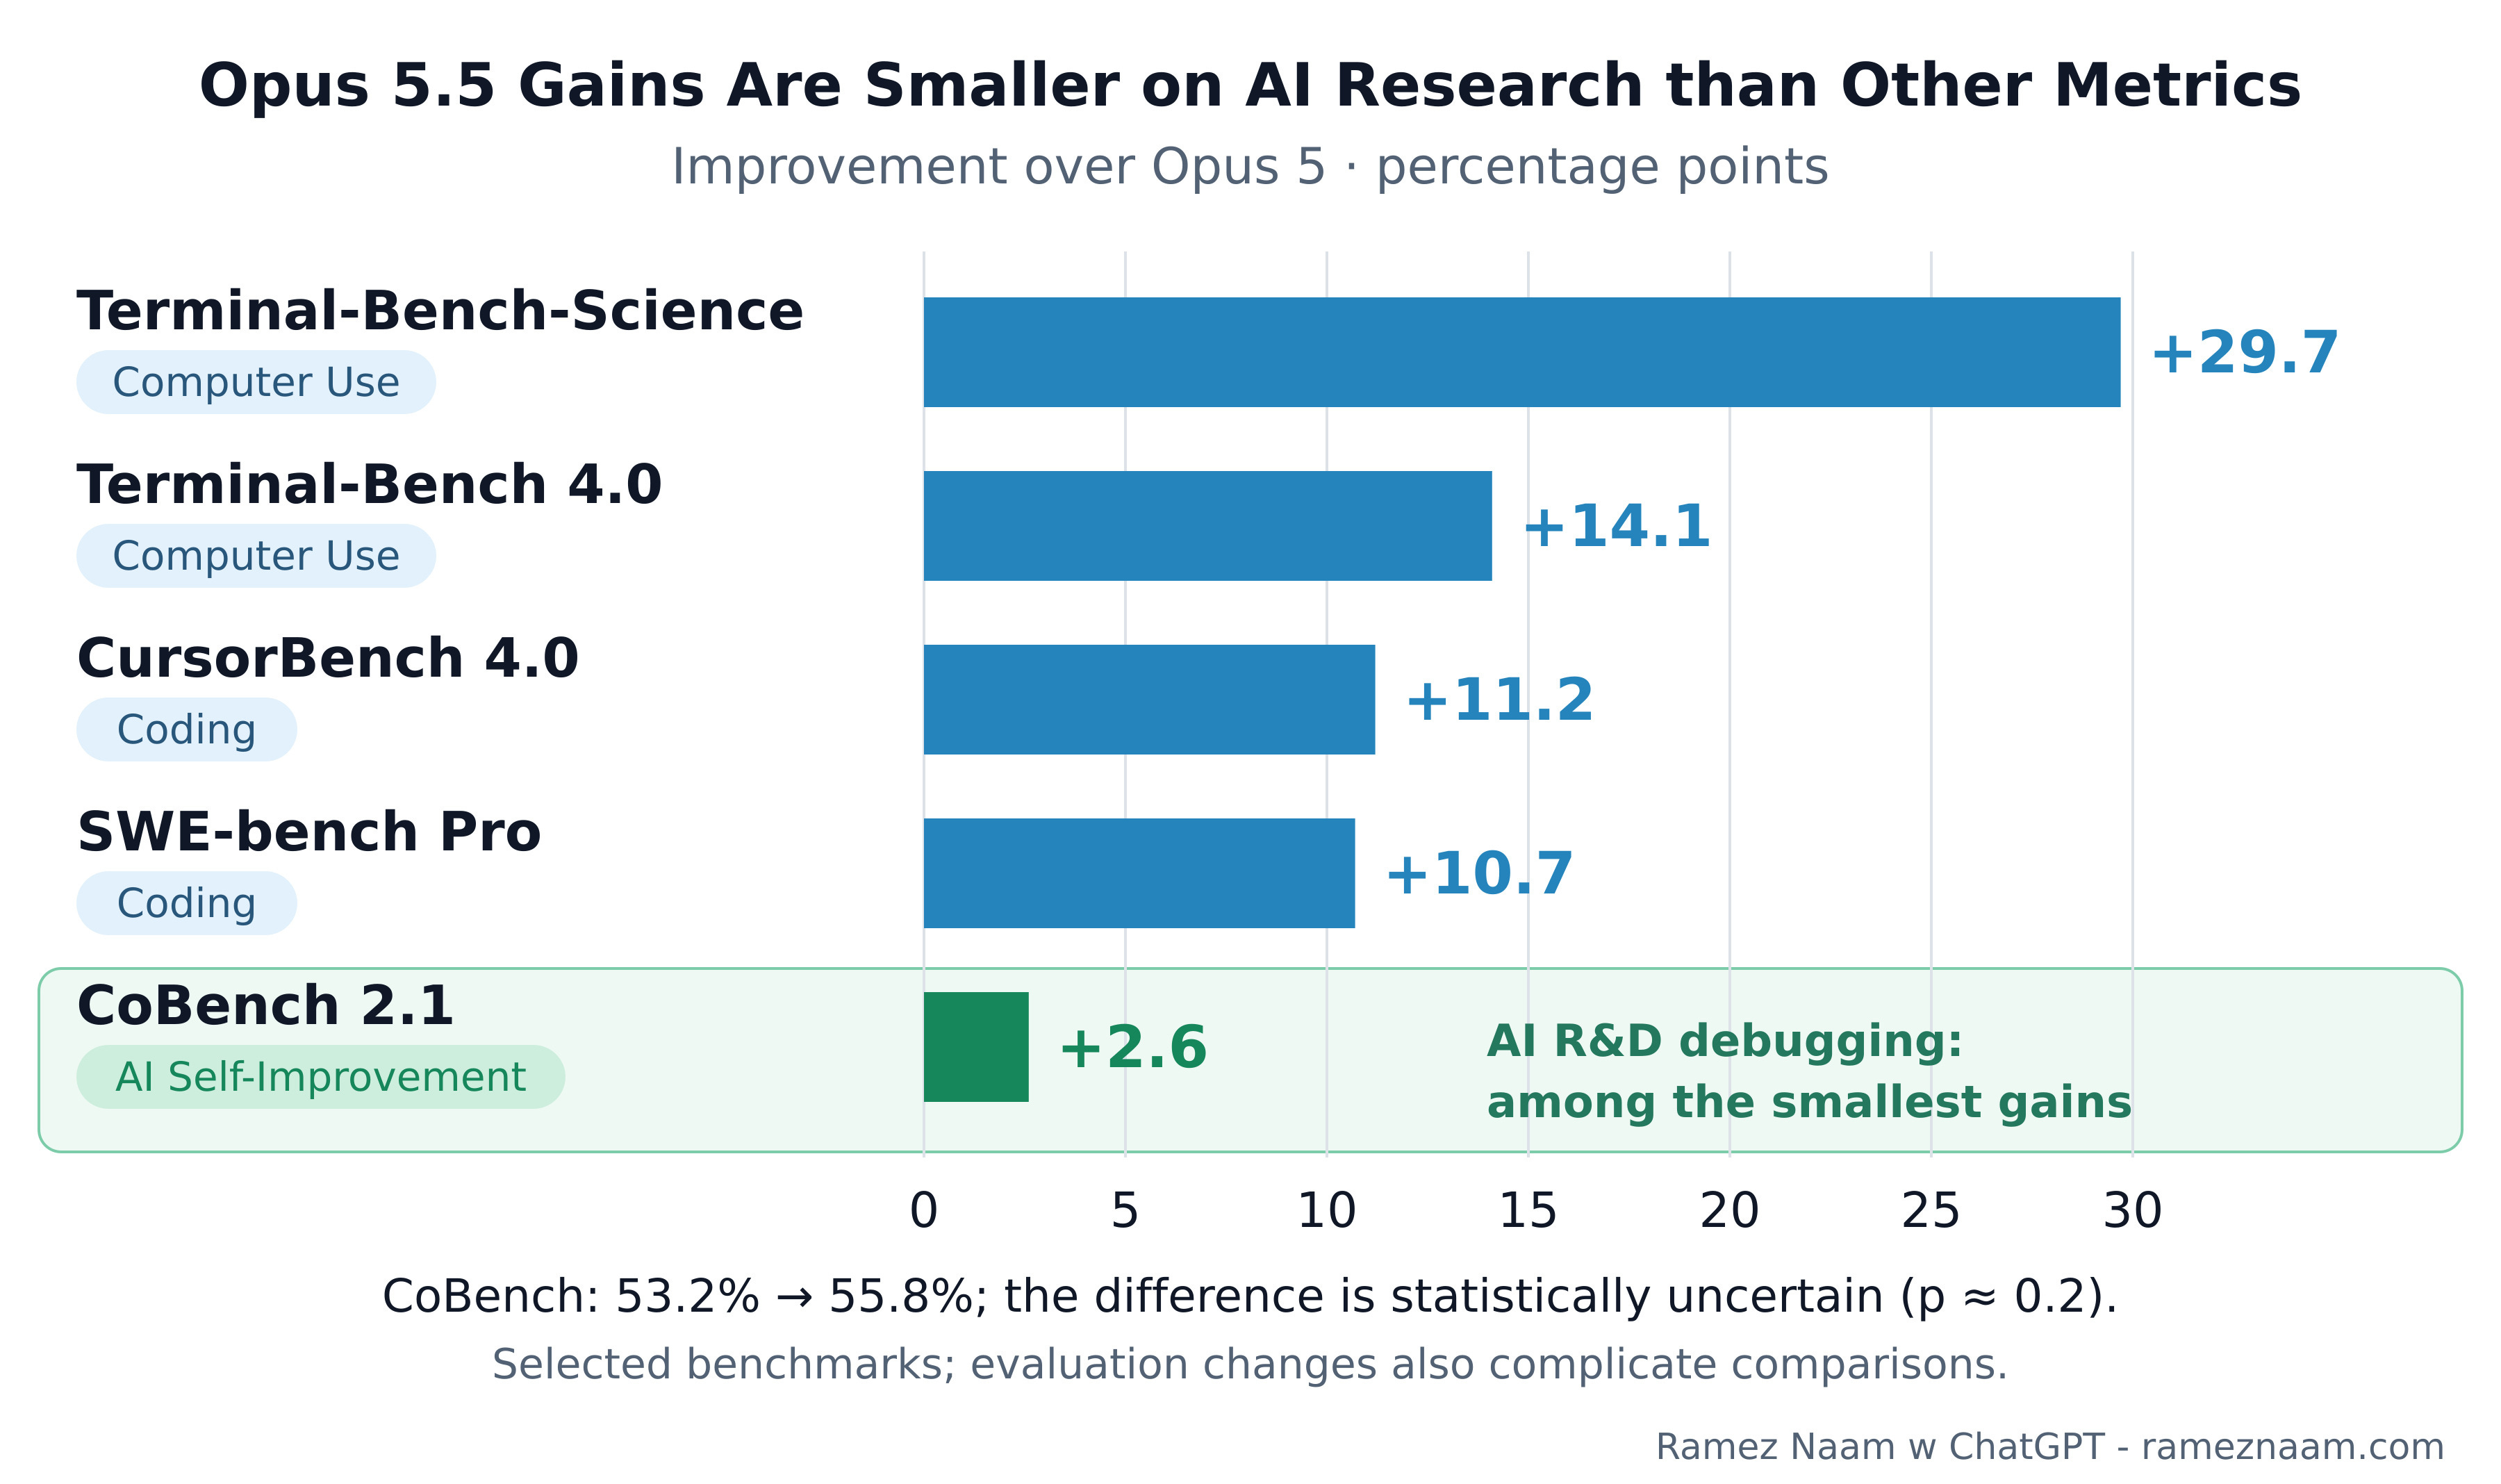
Determine 21. Opus 5.5 benchmark positive aspects. Supply.
Why the smaller achieve right here? Perhaps AI analysis is solely tougher than different duties. Keep in mind that CoBench isn’t testing the power to provide important discoveries. It’s far more restricted in scope. It asks fashions to analyze historic AI R&D issues utilizing code, logs, and paperwork. That’s helpful analysis debugging and productiveness work, but it surely doesn’t instantly check whether or not a mannequin can invent a brand new structure or make a conceptual breakthrough.
The proof on open-ended analysis suggests one other impediment: arising with helpful concepts that haven’t already been tried.
Why do helpful new concepts typically get tougher to seek out?
Tom Cunningham and Manish Shetty have a helpful apple-picking metaphor. An AI can decide the low-hanging fruit rapidly, whereas people can nonetheless attain concepts the AI can’t.
As soon as these apples are picked, one other copy of the identical agent discovering them once more doesn’t assist. A stronger mannequin can attain increased. So as to add my very own flourish, the apples might also get sparser and farther aside as you climb. The RSI query is whether or not every harvest offers us sufficient to construct a greater apple-picker.
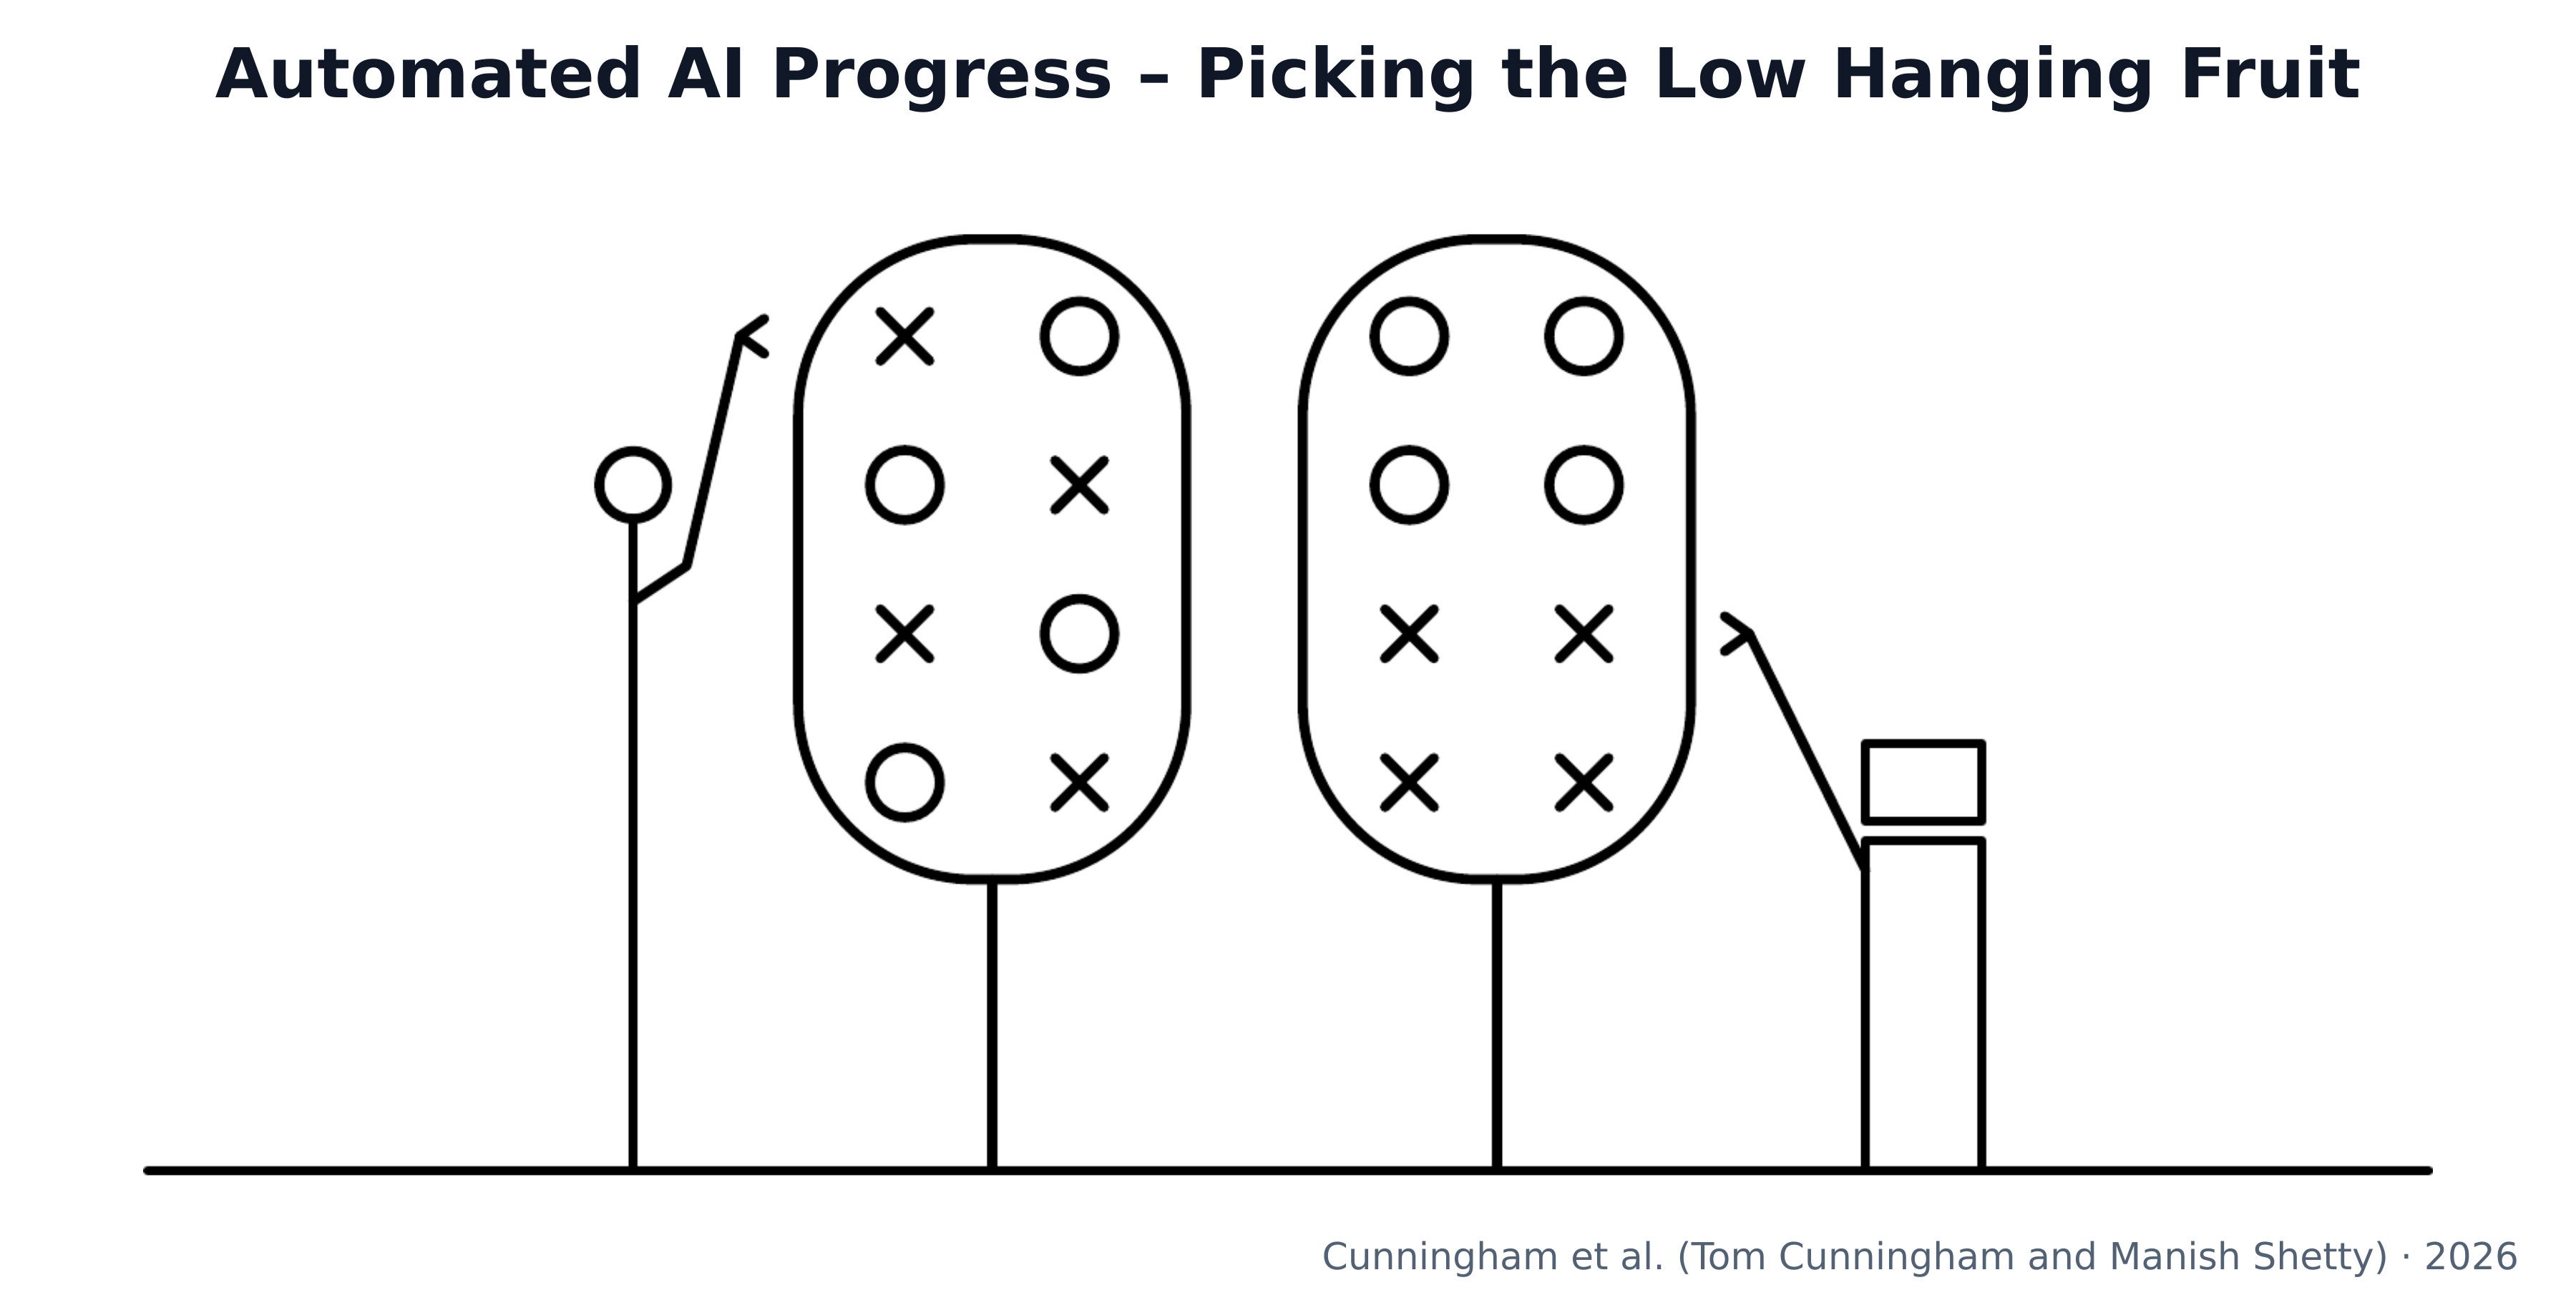
Determine 22. The apple-picking mannequin of AI R&D. Supply.
This sample exhibits up throughout R&D. Bloom and colleagues doc fields the place analysis effort grows whereas analysis productiveness falls. A well-known instance is Eroom’s Legislation: within the historic drug-development knowledge, the inflation-adjusted R&D price per new accredited drug roughly doubled each 9 years.
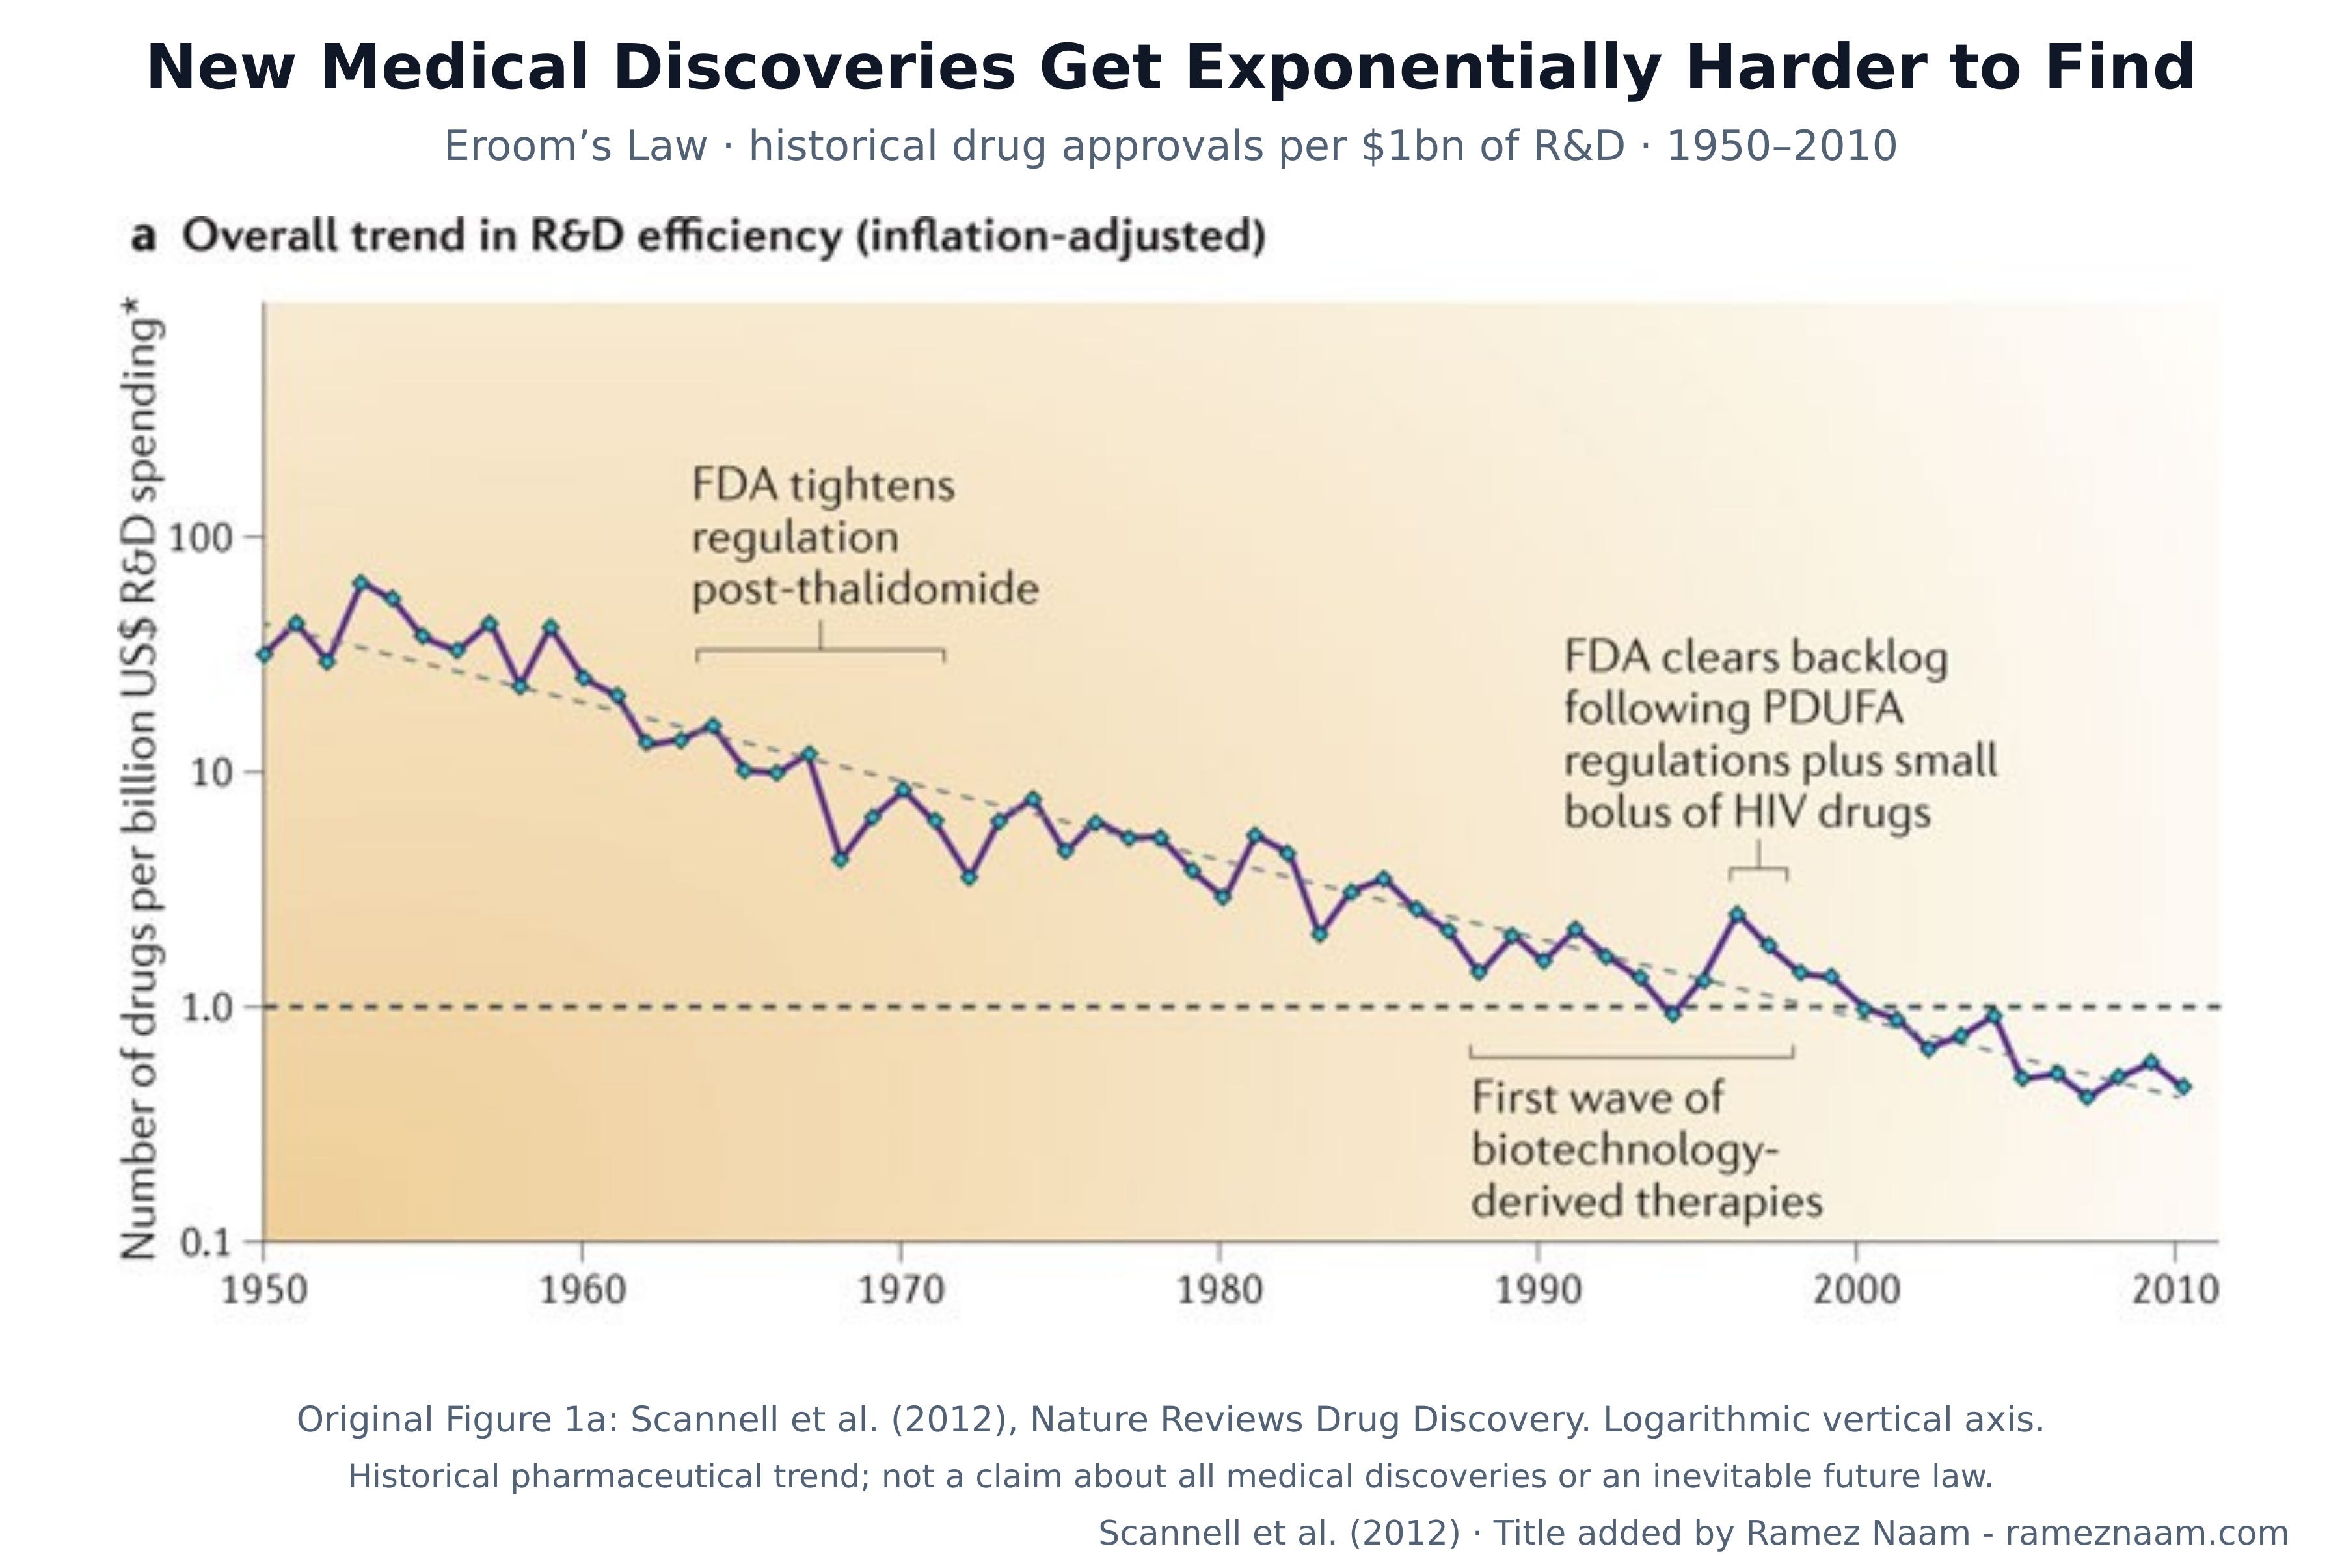
Determine 23. Eroom’s Legislation in drug improvement. Supply.
Pharma has different issues, together with regulation, tough scientific trials, and rising expectations for security. Present remedies also can elevate the bar for a helpful new drug. However a few of this problem might also be that the low-hanging fruit has been picked.
Stockfish, the chess engine, offers us a extra direct take a look at software program analysis. Now we have data of experiments aimed toward bettering it and the positive aspects that adopted. This provides us a real-world dataset to have a look at the positive aspects of experimentation in software program. Because of this, a number of RSI fashions draw on this knowledge. That stated, not all of the enhancements got here from these experiments. A number of essential concepts additionally got here from outdoors the challenge, so we shouldn’t give its experiments all of the credit score.
Epoch’s evaluation of software program R&D estimates returns to analysis effort at about 0.83 for Stockfish, a bit slower than linear. These are diminishing returns, however mild ones. These returns, nevertheless, are enhancements in computational effectivity. And extra compute doesn’t flip instantly into extra AI functionality. As we noticed earlier, AI functionality additionally has steep diminishing returns from including extra computational energy. So we shouldn’t learn that 0.83 because the return from experimentation to AI functionality itself. AI functionality grows far more slowly than compute, as we’ve seen already.
Andrej Karpathy’s autoresearch demonstration will get nearer to the method we wish to perceive. A “trainer” AI agent adjustments a smaller “scholar” AI mannequin’s coaching code, runs it, checks the outcome, and tries once more. The trainer agent itself doesn’t enhance, but it surely is ready to enhance the “learner”. That is my Kind 2: A stronger AI improves a weaker one.
One public run, posted by an agent working on Karpathy’s behalf, reported 89 experiments over roughly 7.5 hours. About 92% of that session’s achieve arrived by run 44. Features got here rapidly, then slowed. The setup was intentionally small, with a five-minute coaching price range per experiment. However the agent might change the structure, optimizer, and coaching settings; it wasn’t restricted to a handful of knobs.
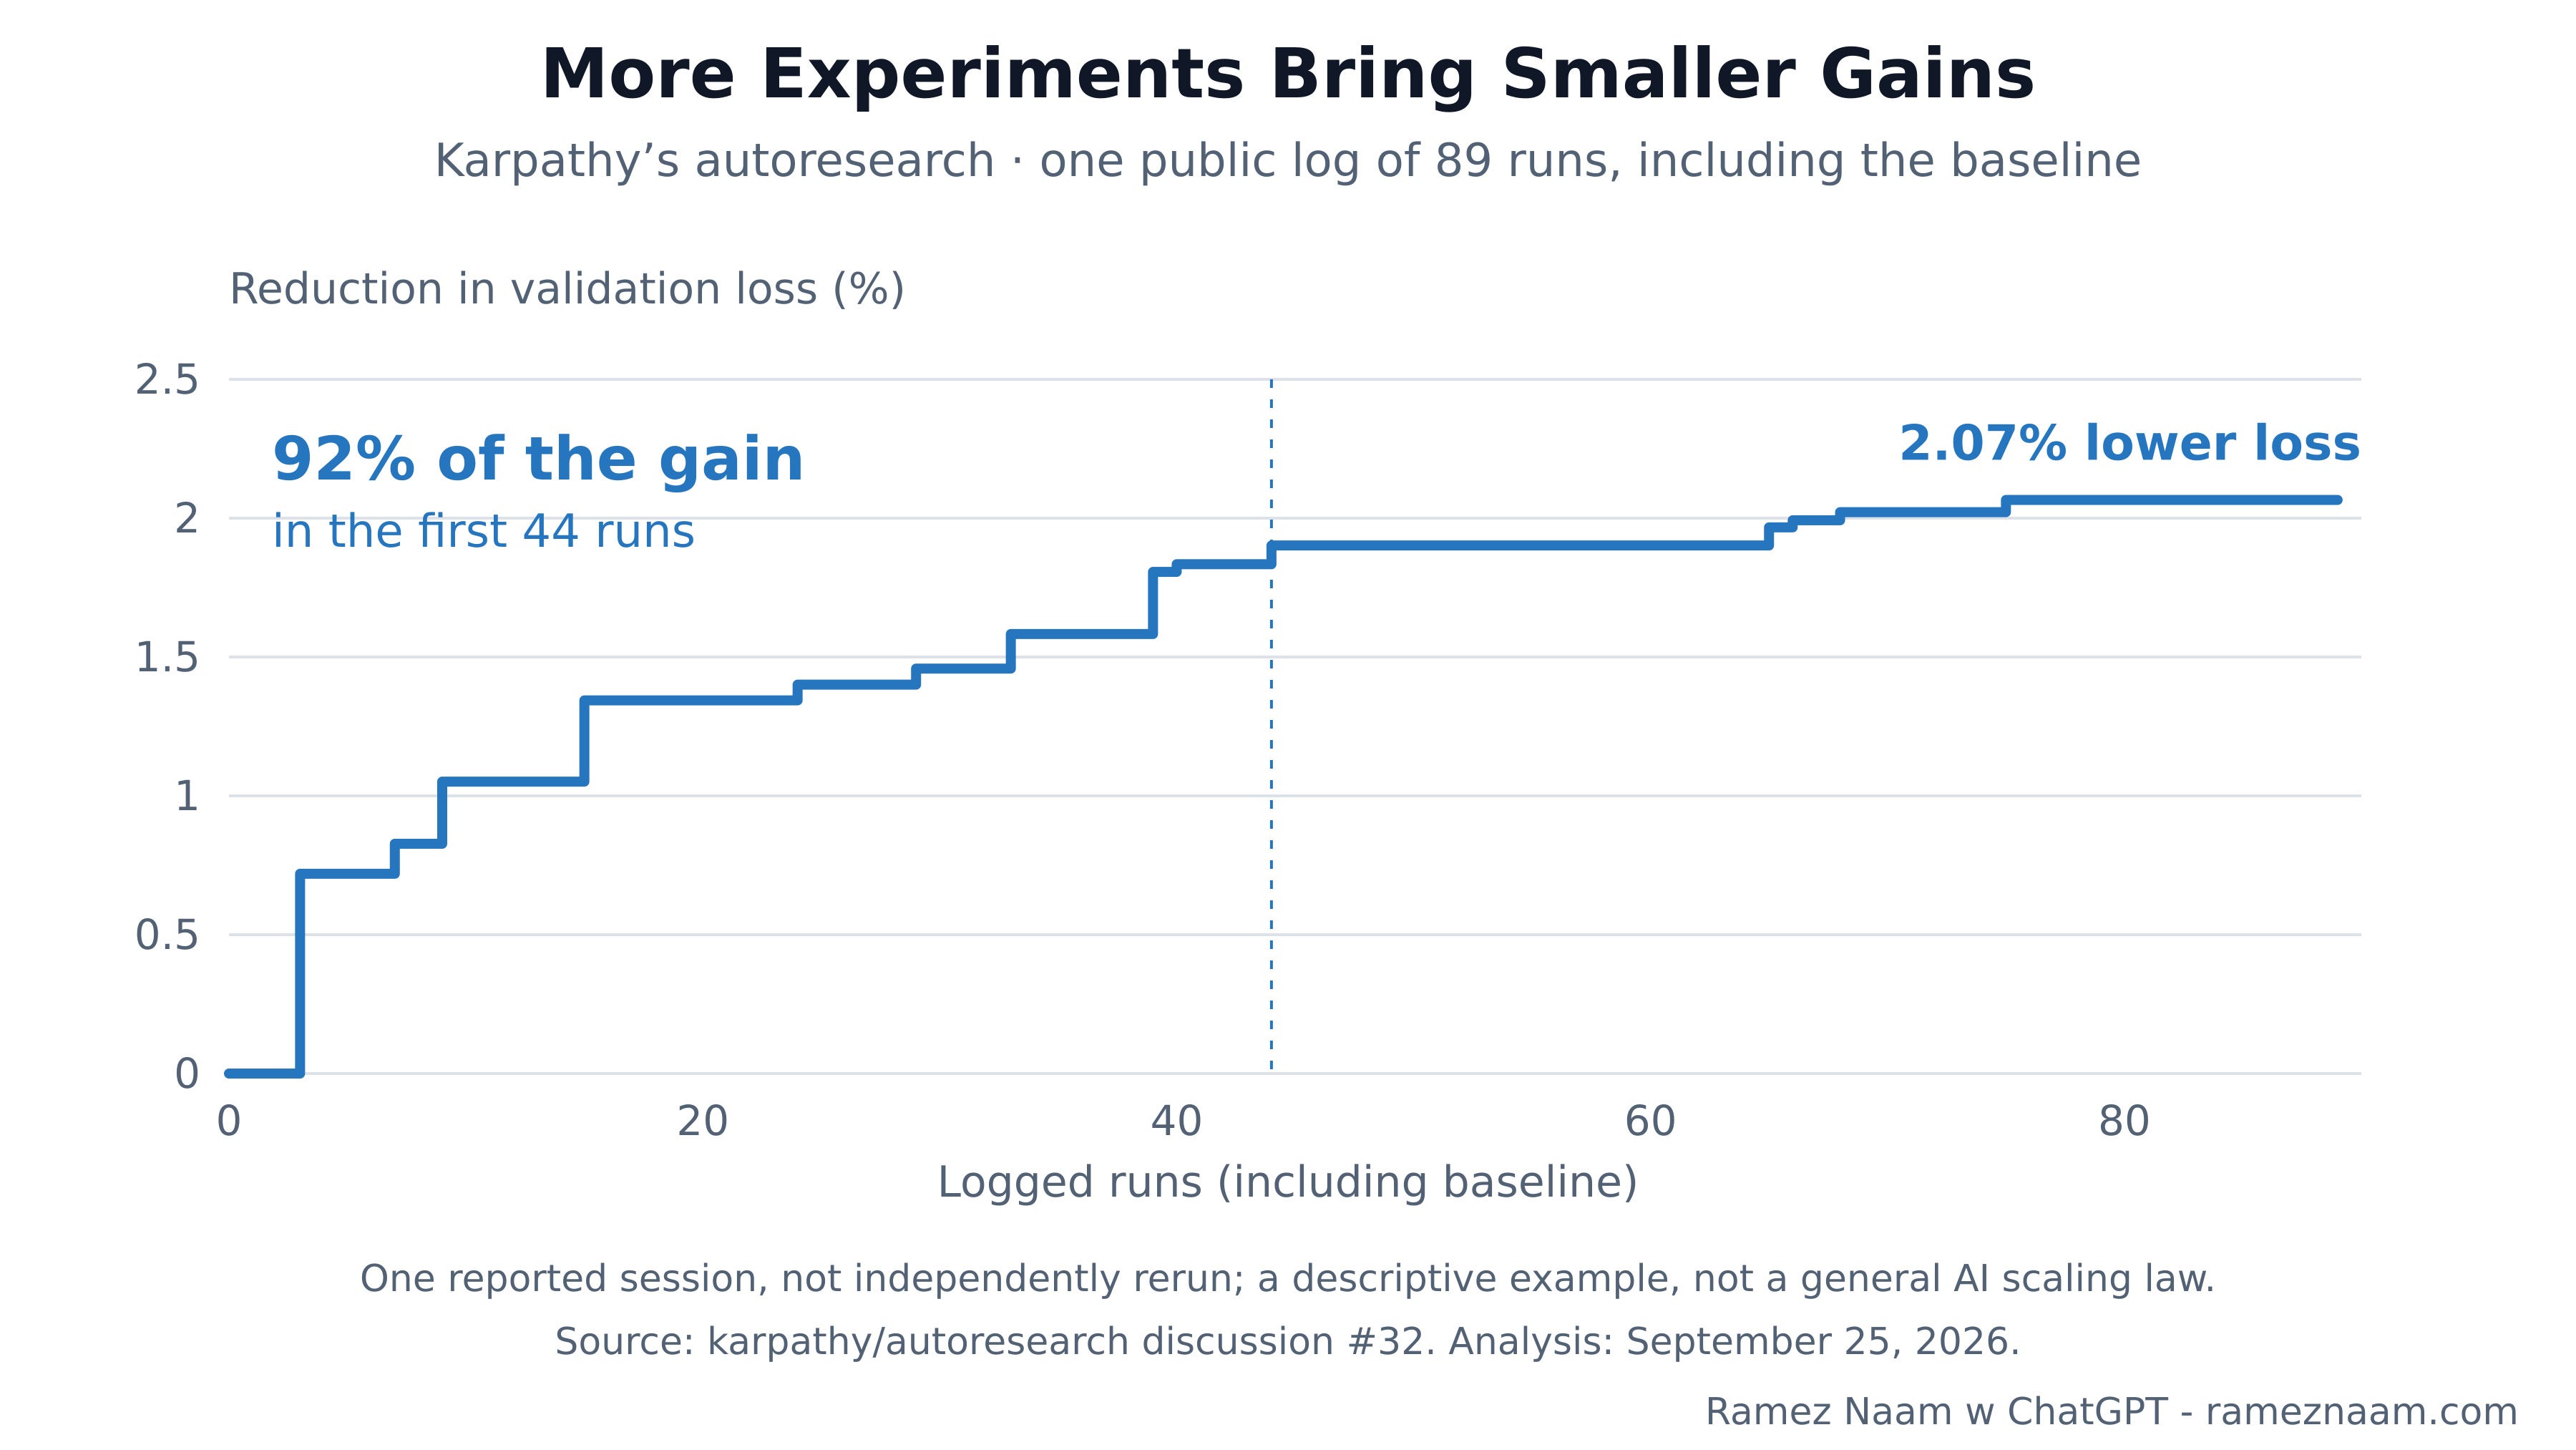
Determine 24. Features in a single autoresearch run. Supply.
A later public run acquired additional, so the primary run hadn’t hit a tough ceiling. This can be a helpful early instance of autonomous analysis, and yet one more place the place we see the diminishing returns endemic in AI analysis. That stated, this was a really early experiment. I anticipate future programs to do significantly better. This specific AI enchancment loop will seemingly develop stronger.
That is the place the excellence issues. Extra tokens should buy extra code, and extra code can assist us run extra experiments. However experiments solely enhance AI in the event that they uncover one thing helpful.
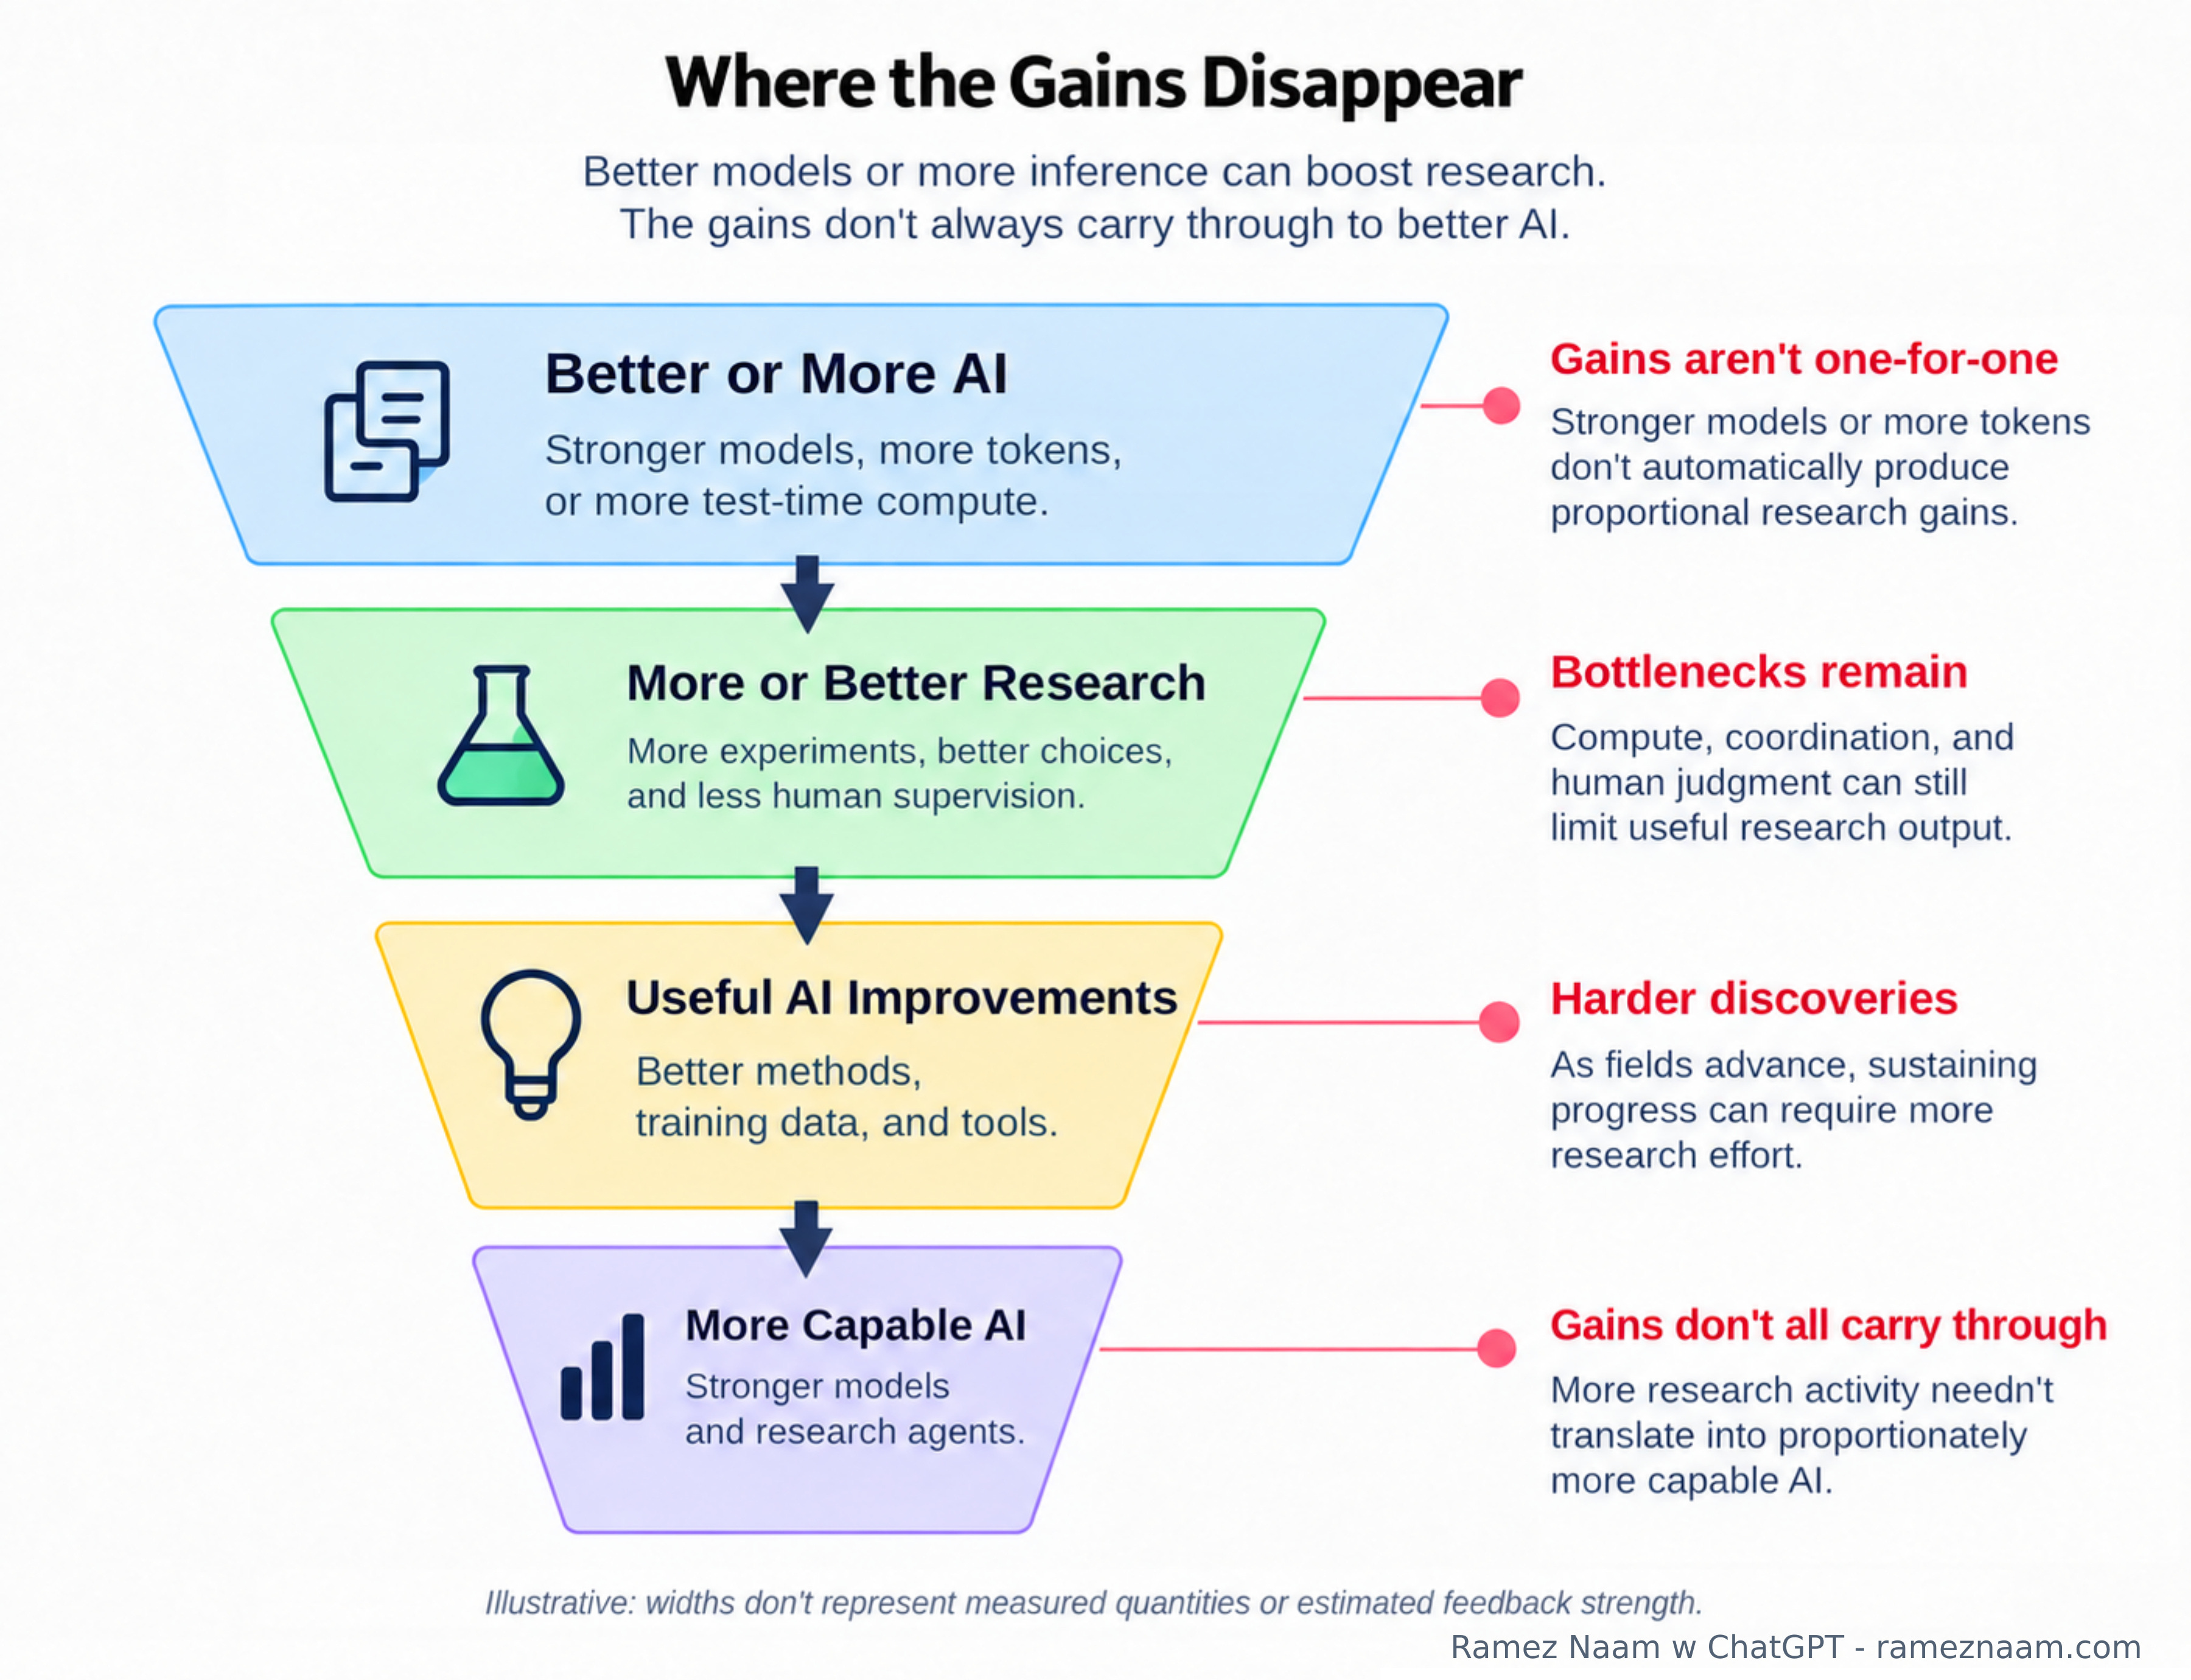
Determine 25. From AI exercise to helpful enhancements.
The larger query is whether or not AI can give you formidable new analysis concepts or conceptual breakthroughs.
Anthropic’s description of Opus 5.5 is blunt:
“As with earlier fashions, it’s weaker on open-ended analysis: inside customers report that it largely exams incremental concepts and prefers much less formidable hypotheses, and in our human-run biology train, it deferred to the printed literature and struggled to develop novel concepts (Part 2.2.2).”- Anthropic, Claude Opus 5.5 System Card, part 2.3.3; emphasis mine
METR’s evaluation in the identical card identifies what should be lacking:
“That is extremely unsure, however we anticipate that full automation of AI R&D would require giant enhancements in foresight, prediction, creating one’s personal suggestions loops, and customarily different expertise that may usually be known as researcher ‘judgement’ or ‘style’.”- METR, quoted within the Claude Opus 5.5 System Card, part 2.3.6
In these examples, people nonetheless provide a lot of the course and judgment.
Future fashions will in all probability get higher at this. However on the earth’s stockpile of potential coaching knowledge, we’ve got many extra examples of incremental work than of breakthroughs. I ponder whether that makes novelty tougher to study. That’s hypothesis, however price watching.
That is additionally powerful to deal with by merely working extra copies of the AI. An enormous variety of parallel brokers can assist with the incremental enhancements or looking over a big set of parameters, however for breakthrough concepts they might run into the homogeneity downside: Extra parallel brokers nonetheless suppose alike.
How far are we from the self-improvement loop being robust sufficient to maintain itself, or to propel itself into runaway super-intelligence? Can we quantify this?
We are able to make a tough estimate. Higher AI helps with analysis; helpful analysis produces higher AI. For the loop to maintain itself, every spherical should produce sufficient positive aspects to propel the system via the subsequent loop, whilst enhancements get tougher to find.
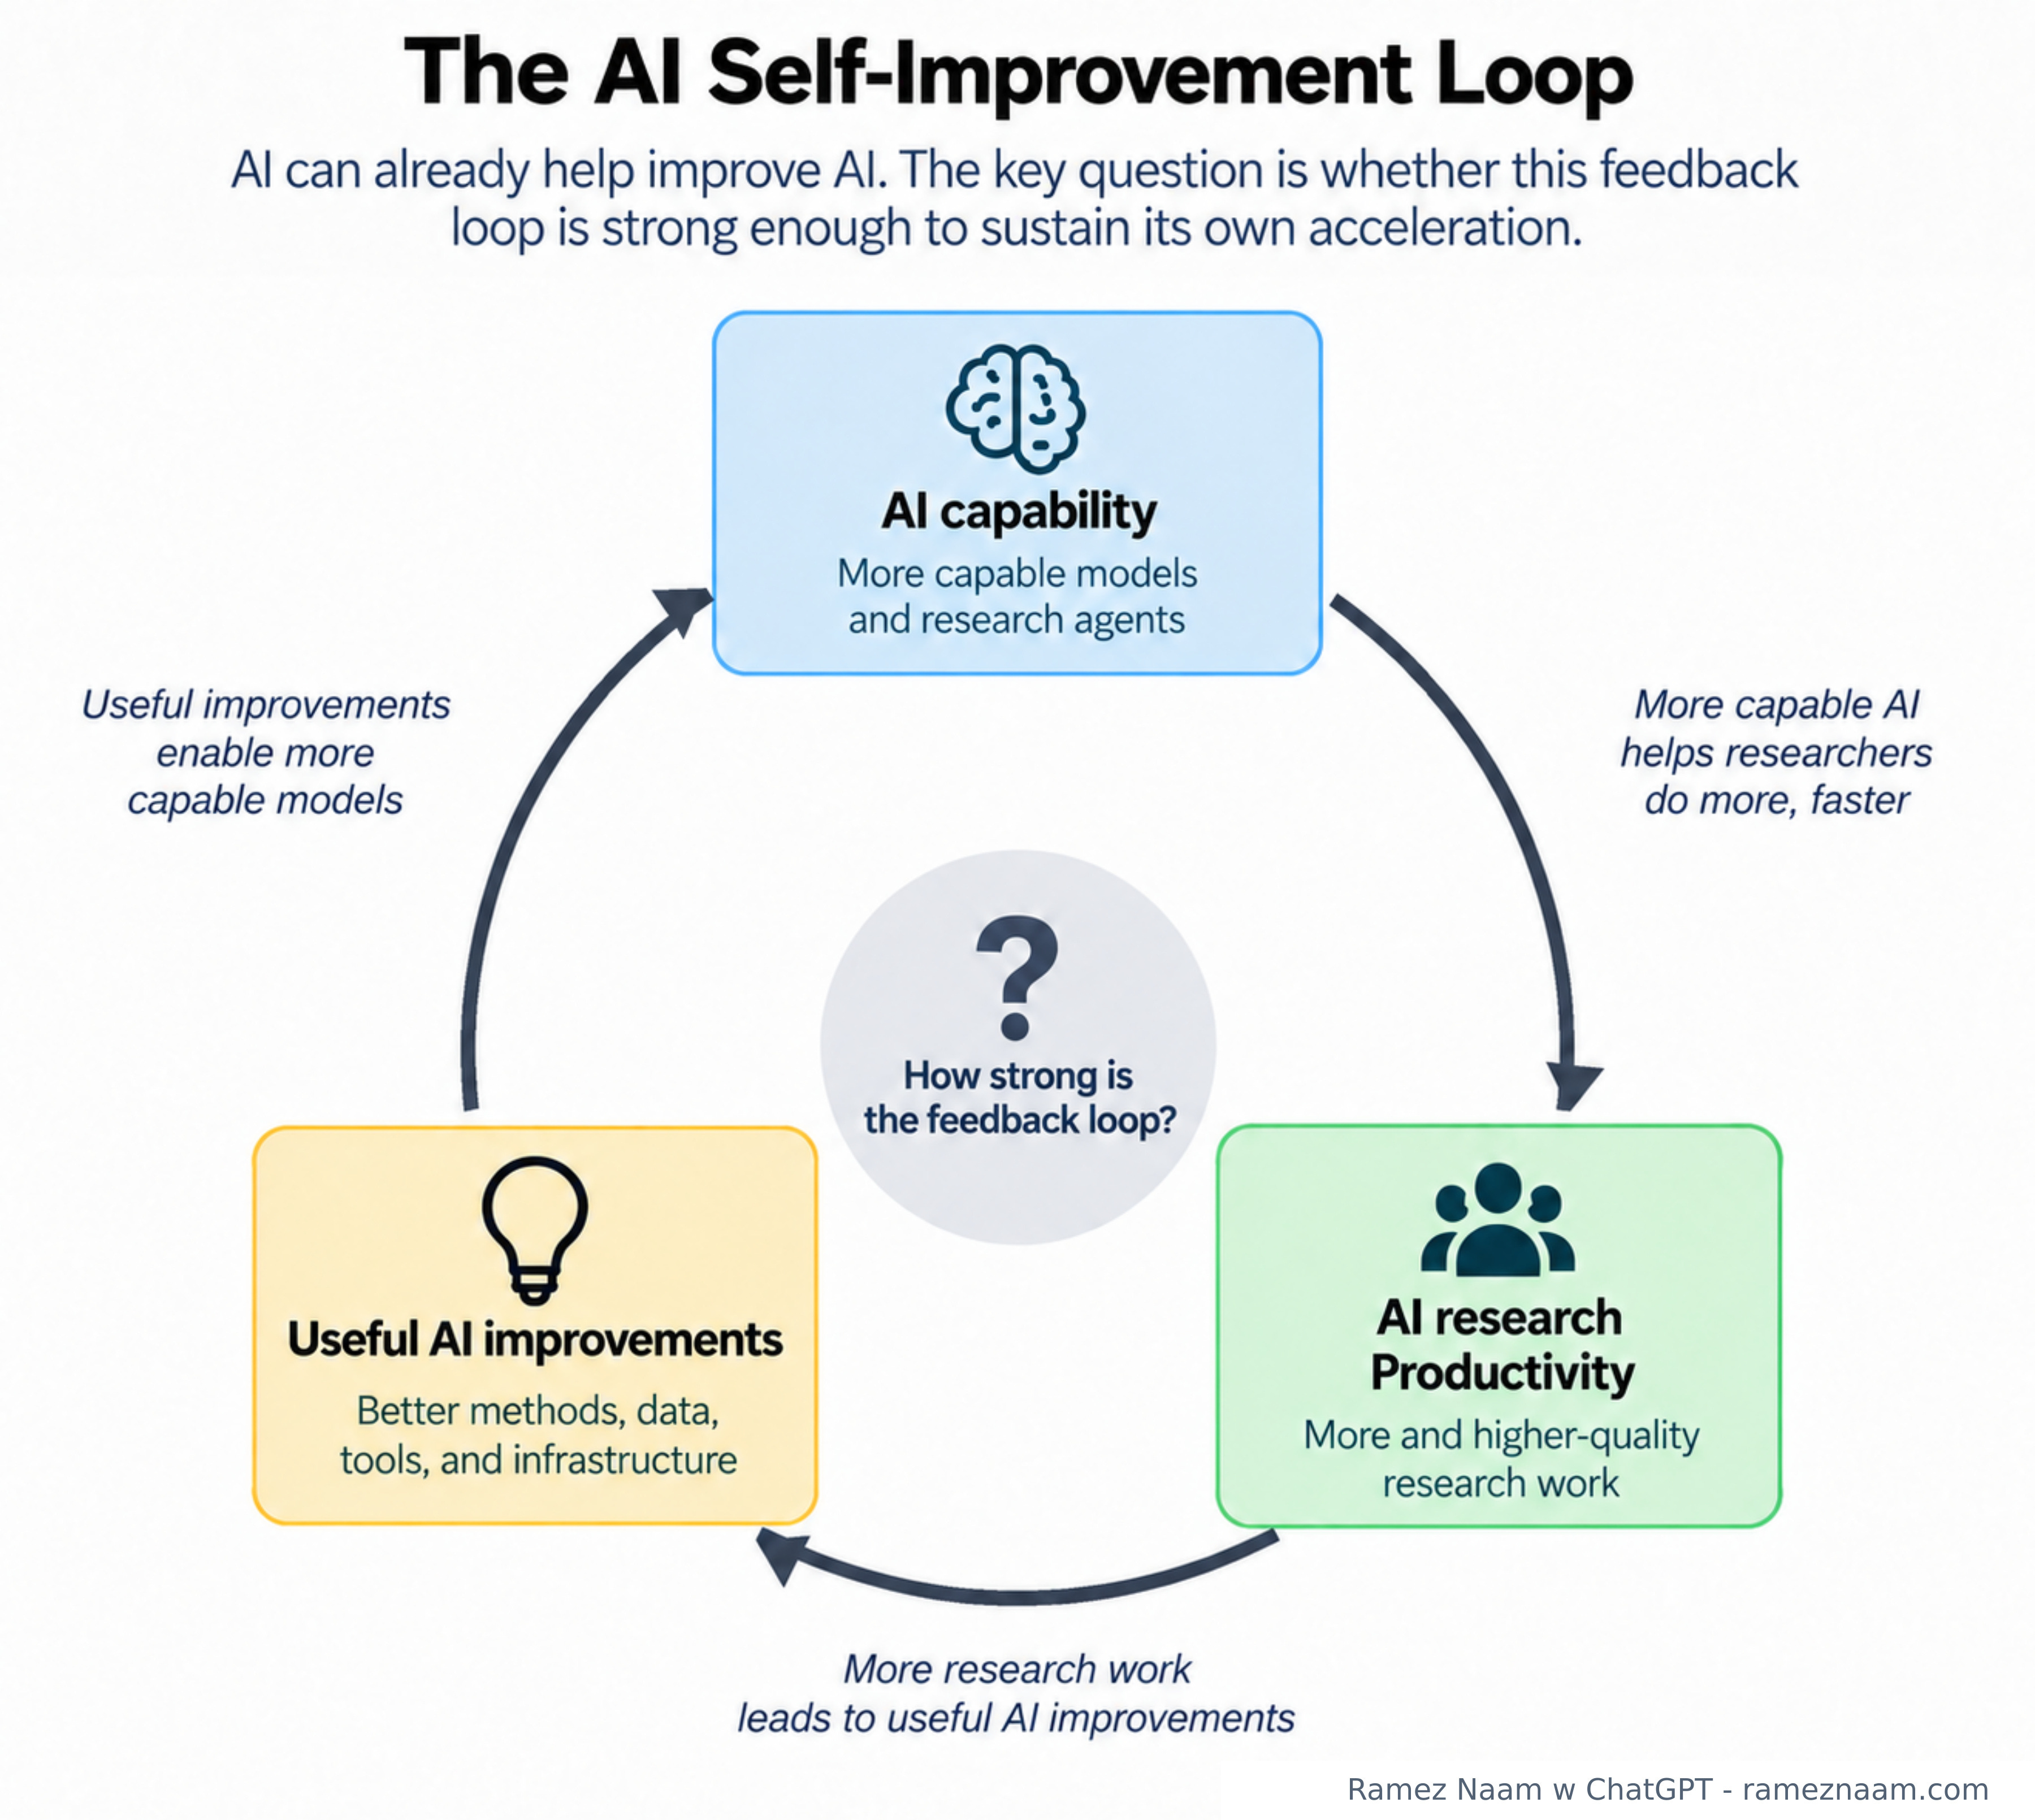
Determine 26. The AI self-improvement loop. Mannequin.
In a current paper, The Economics of Recursive Self-Enchancment, Tom Cunningham and colleagues modeled this from the standpoint of how far more productiveness each level of extra ECI produces from an AI. They ask in the beginning what that quantity would have to be to create a self-sustaining suggestions loop. And secondly, they attempt to decide what that productivity-per-ECI-point quantity is at this time.
First, they discover a self-sustaining RSI threshold of roughly 15% extra analysis productiveness per additional ECI level. Of their mannequin, that’s about the place higher AI would generate sufficient progress to maintain the loop.
The image beneath exhibits the thought. On the threshold, every cycle of positive aspects powers the subsequent. Above the edge, the suggestions loop accelerates. Beneath the edge, the suggestions loop is simply too weak, and the speed of enchancment it brings drops on every cycle. This mannequin isolates the software program loop; outdoors funding can nonetheless drive speedy progress.
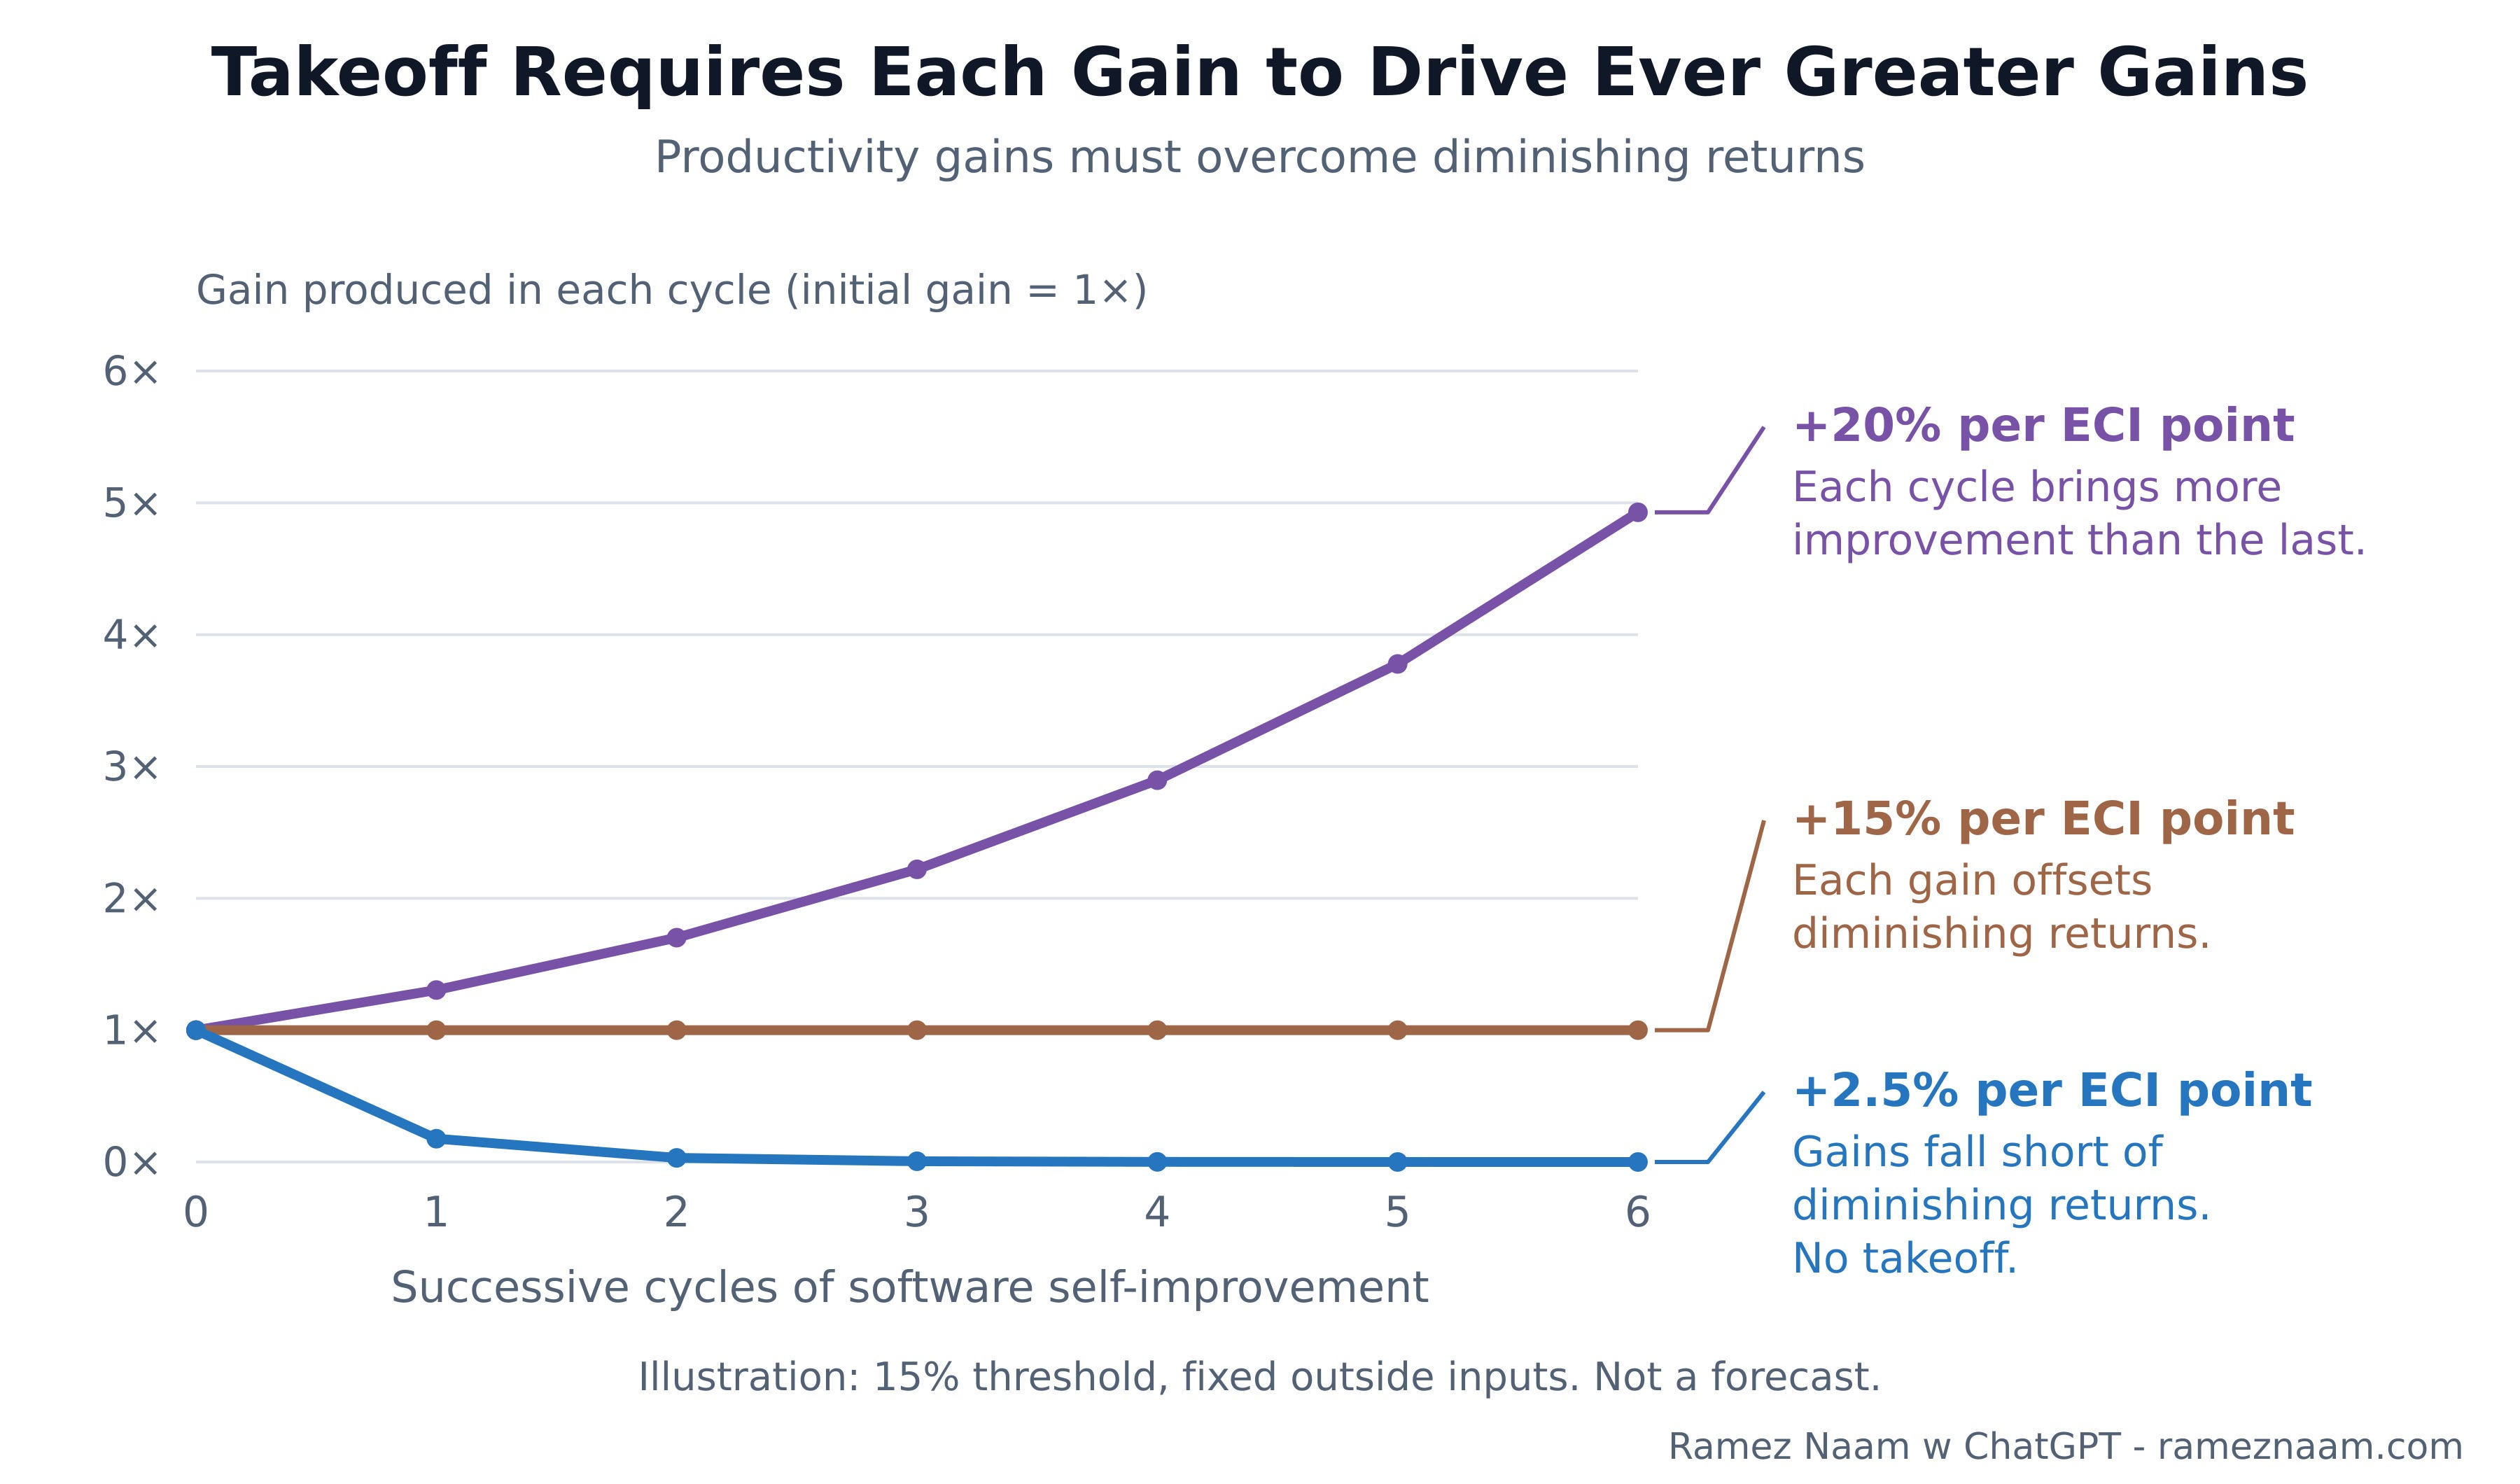
Determine 27. Three illustrative suggestions paths. Supply.
Updating this barely with knowledge from the Stockfish experiments places the edge a bit increased, at roughly 19% per ECI level. I wouldn’t put a lot weight on that exact distinction. Each estimates are unsure. However they offer us a means to consider the power of the suggestions loop and a tough band at which self-sustaining or runaway RSI could start.
The second factor Cunningham and workforce do is make a tough estimate that the present AI productiveness achieve is about 9% per ECI level. That’s beneath their self-sustaining threshold.
I just like the mannequin. OpenAI’s newer knowledge, nevertheless, suggests the loop could also be fairly a bit weaker.
Cunningham’s estimate of 9% productiveness achieve per ECI level is predicated on Anthropic’s survey of 130 employees, who reported roughly 4× the productiveness they’d have with out AI. Cunningham and colleagues examine that with a 16-point functionality achieve since early Claude Code.
That comparability assumes the sooner instruments added little or no productiveness, so ‘no AI’ is an inexpensive start line. The authors say this explicitly. I’m undecided the belief holds for a similar researchers doing the identical work, however that’s a smaller problem.
The authors themselves know that it is a tough calculation, and warn that the 4× survey estimate might be too excessive.
OpenAI’s newer knowledge offers us a firmer solution to test the quantity: Precise logged experiments over time, fairly than human estimates of their very own productiveness with and with out AI. I put extra weight on this for 3 causes:
-
Direct and broad measurement. As a substitute of counting on surveys, OpenAI truly tracked and measured experiments run on their infrastructure. Meaning they didn’t depend on researchers estimating their very own productiveness, which might be far off.
-
Full pattern, not opt-in. Equally, OpenAI’s knowledge catches each lively experimenter, whereas Anthropic’s solely displays the 130 workers who took the time to reply the survey – and who subsequently is probably not a consultant set.
-
Enormously extra knowledge. We don’t know what number of experiments are within the 32 weeks of OpenAI knowledge, but it surely’s seemingly a minimum of tens of 1000’s of particular person examples and probably a whole bunch of 1000’s.
Any means you slice it, the brand new OpenAI knowledge, launched after Cunningham’s paper was drafted, is a bigger, extra complete, extra consultant, and virtually definitely extra correct dataset than Anthropic’s inside opt-in survey of workers.
Now let’s use OpenAI’s experiment knowledge to calibrate the productiveness achieve per ECI level. We all know that in August, OpenAI researchers ran ~1.6× as many experiments per individual per thirty days because the 2025 common. If we pair that with roughly 16 factors of frontier ECI enchancment, it really works backward to about 3% productiveness achieve per level of ECI. Against this, 9% compounded over 16 factors would imply roughly 4× productiveness.
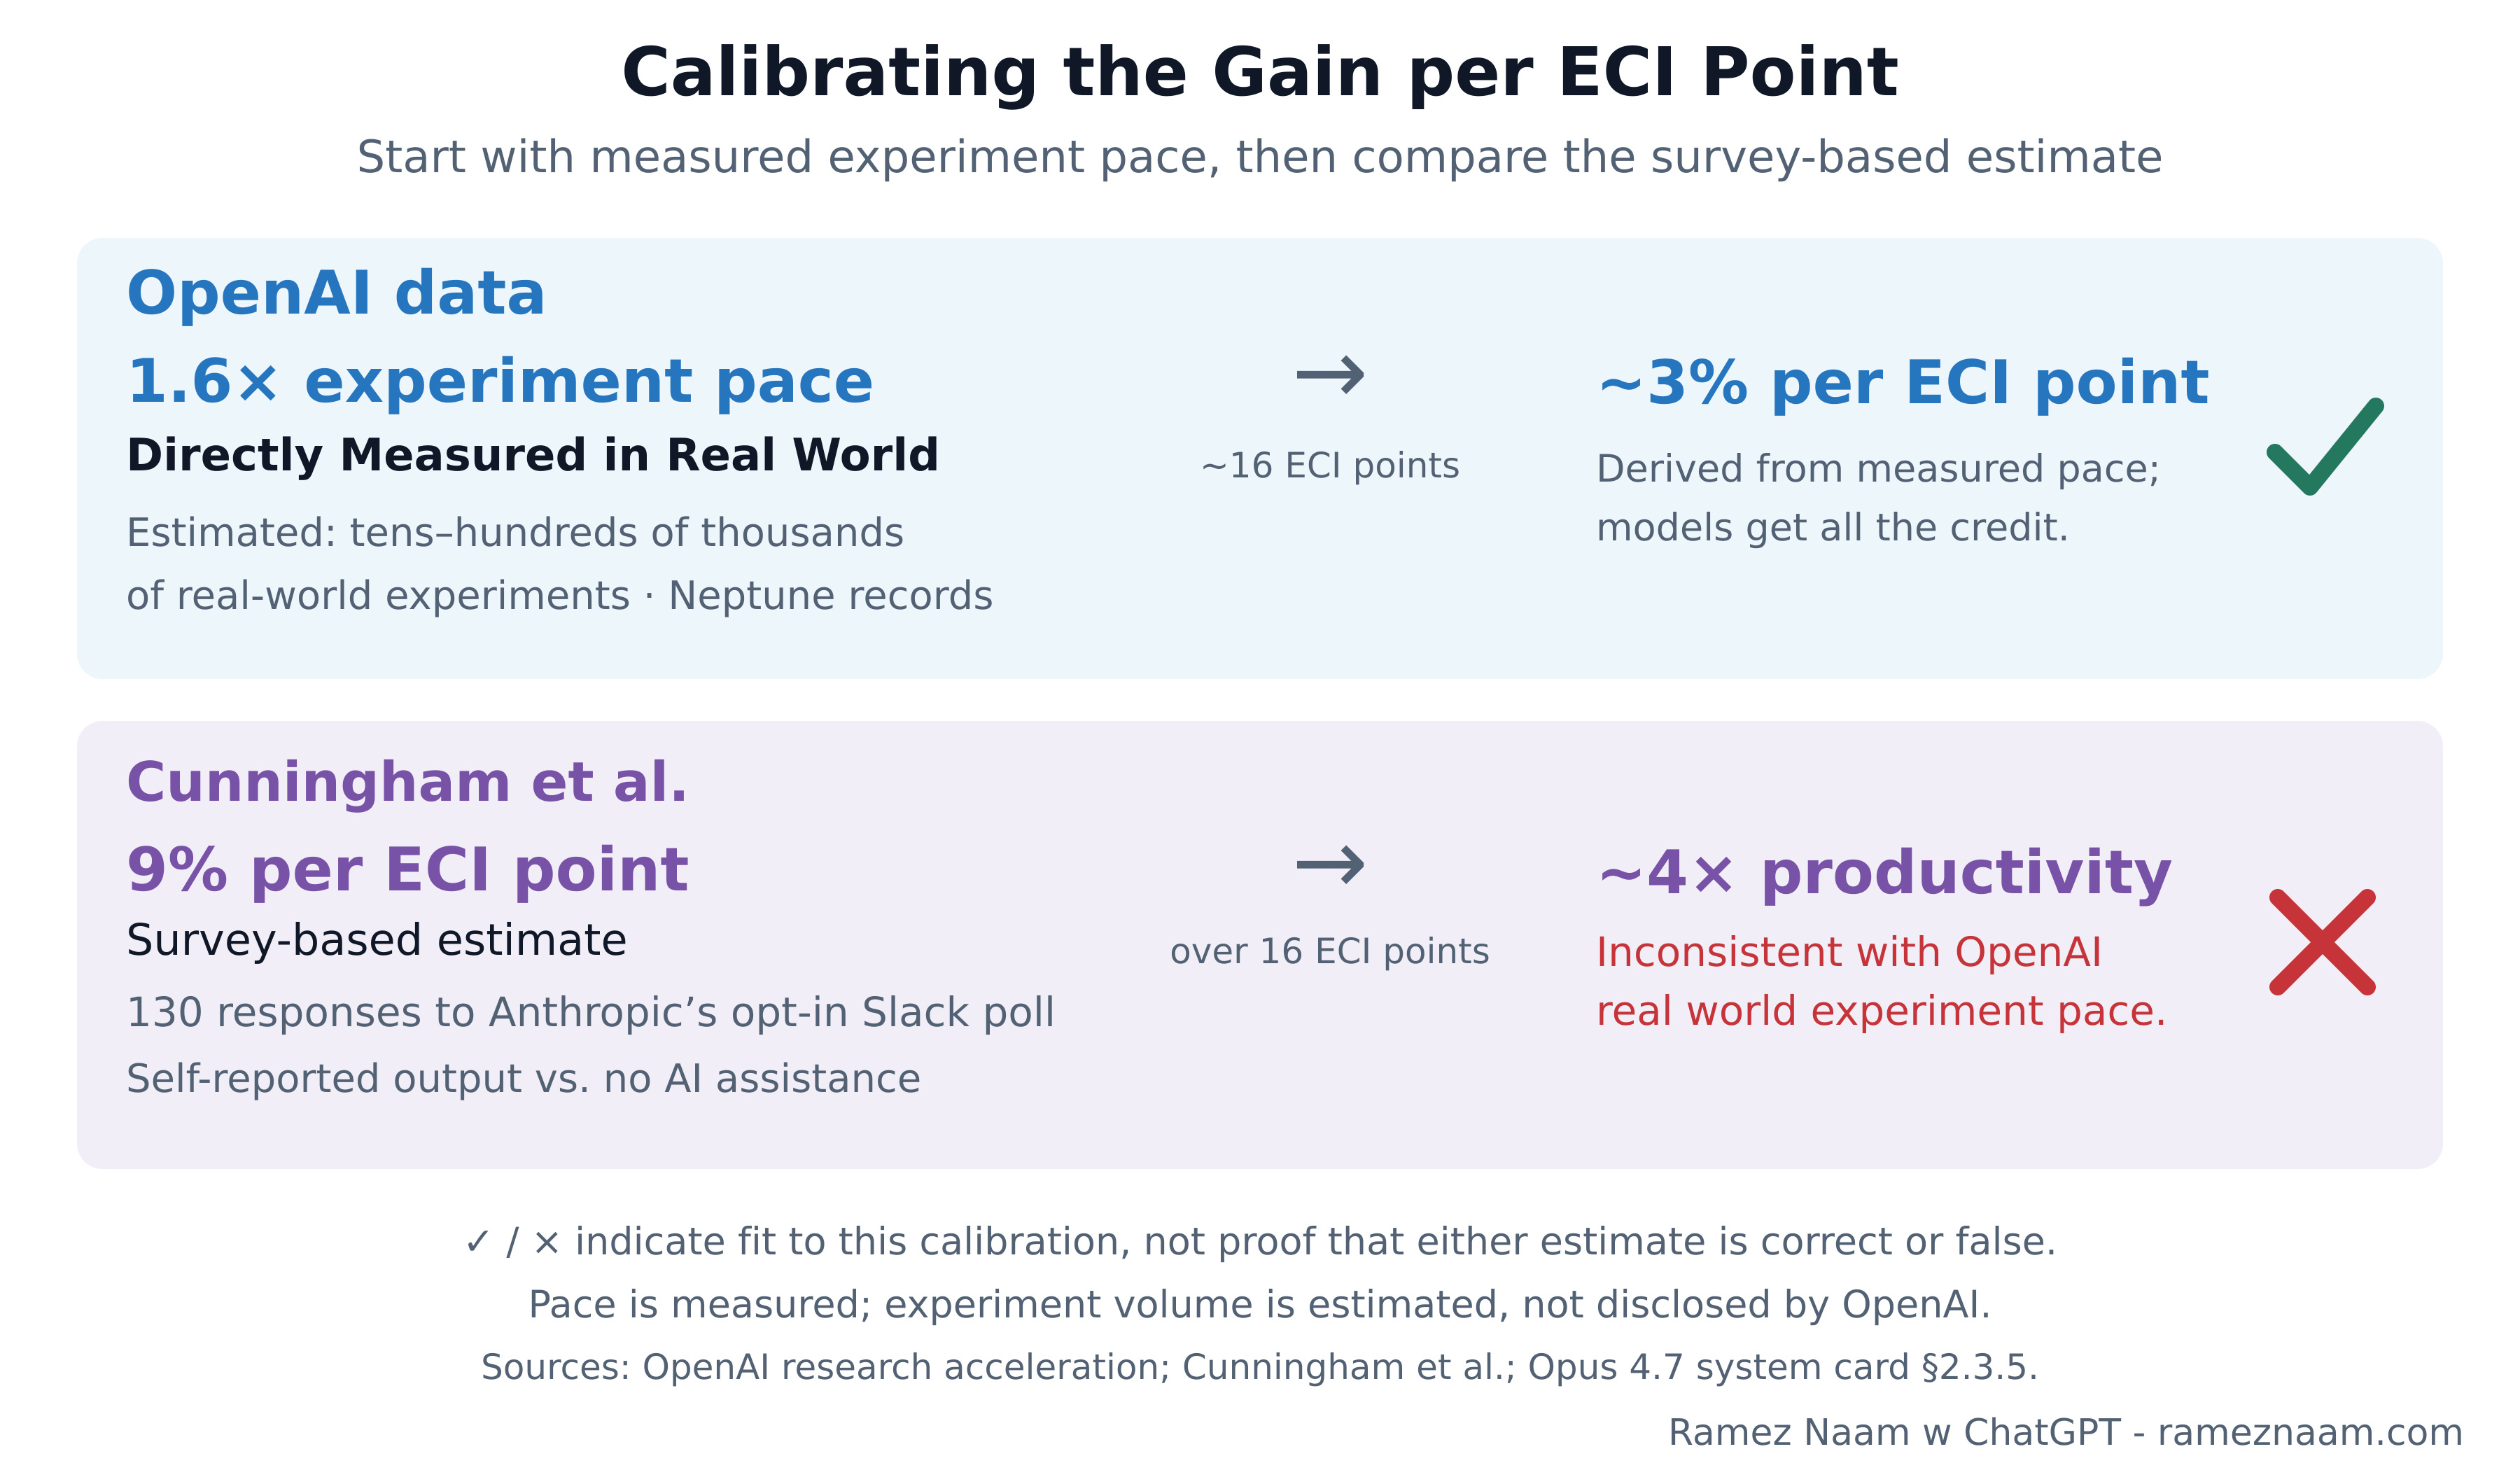
Determine 28. Evaluating productiveness estimates. OpenAI strategies.
Right here’s OpenAI’s printed weekly sequence alongside that hypothetical path of 9% extra productiveness per extra ECI level. The blue line ends at ~1.6×. The crimson line exhibits what 9% per level would indicate if 16 ECI factors have been unfold throughout this era. That doesn’t match what we see from OpenAI’s knowledge. I wish to be clear right here that each one knowledge units are noisy. We don’t know precisely what mannequin researchers have been utilizing on what days, or whether or not the brand new experiments have been additionally increased high quality than previous experiments. We’d like extra experiments and extra knowledge to additional calibrate these numbers. Working with what we do have, what we see is a fairly low enhance to productiveness from every extra ECI level.
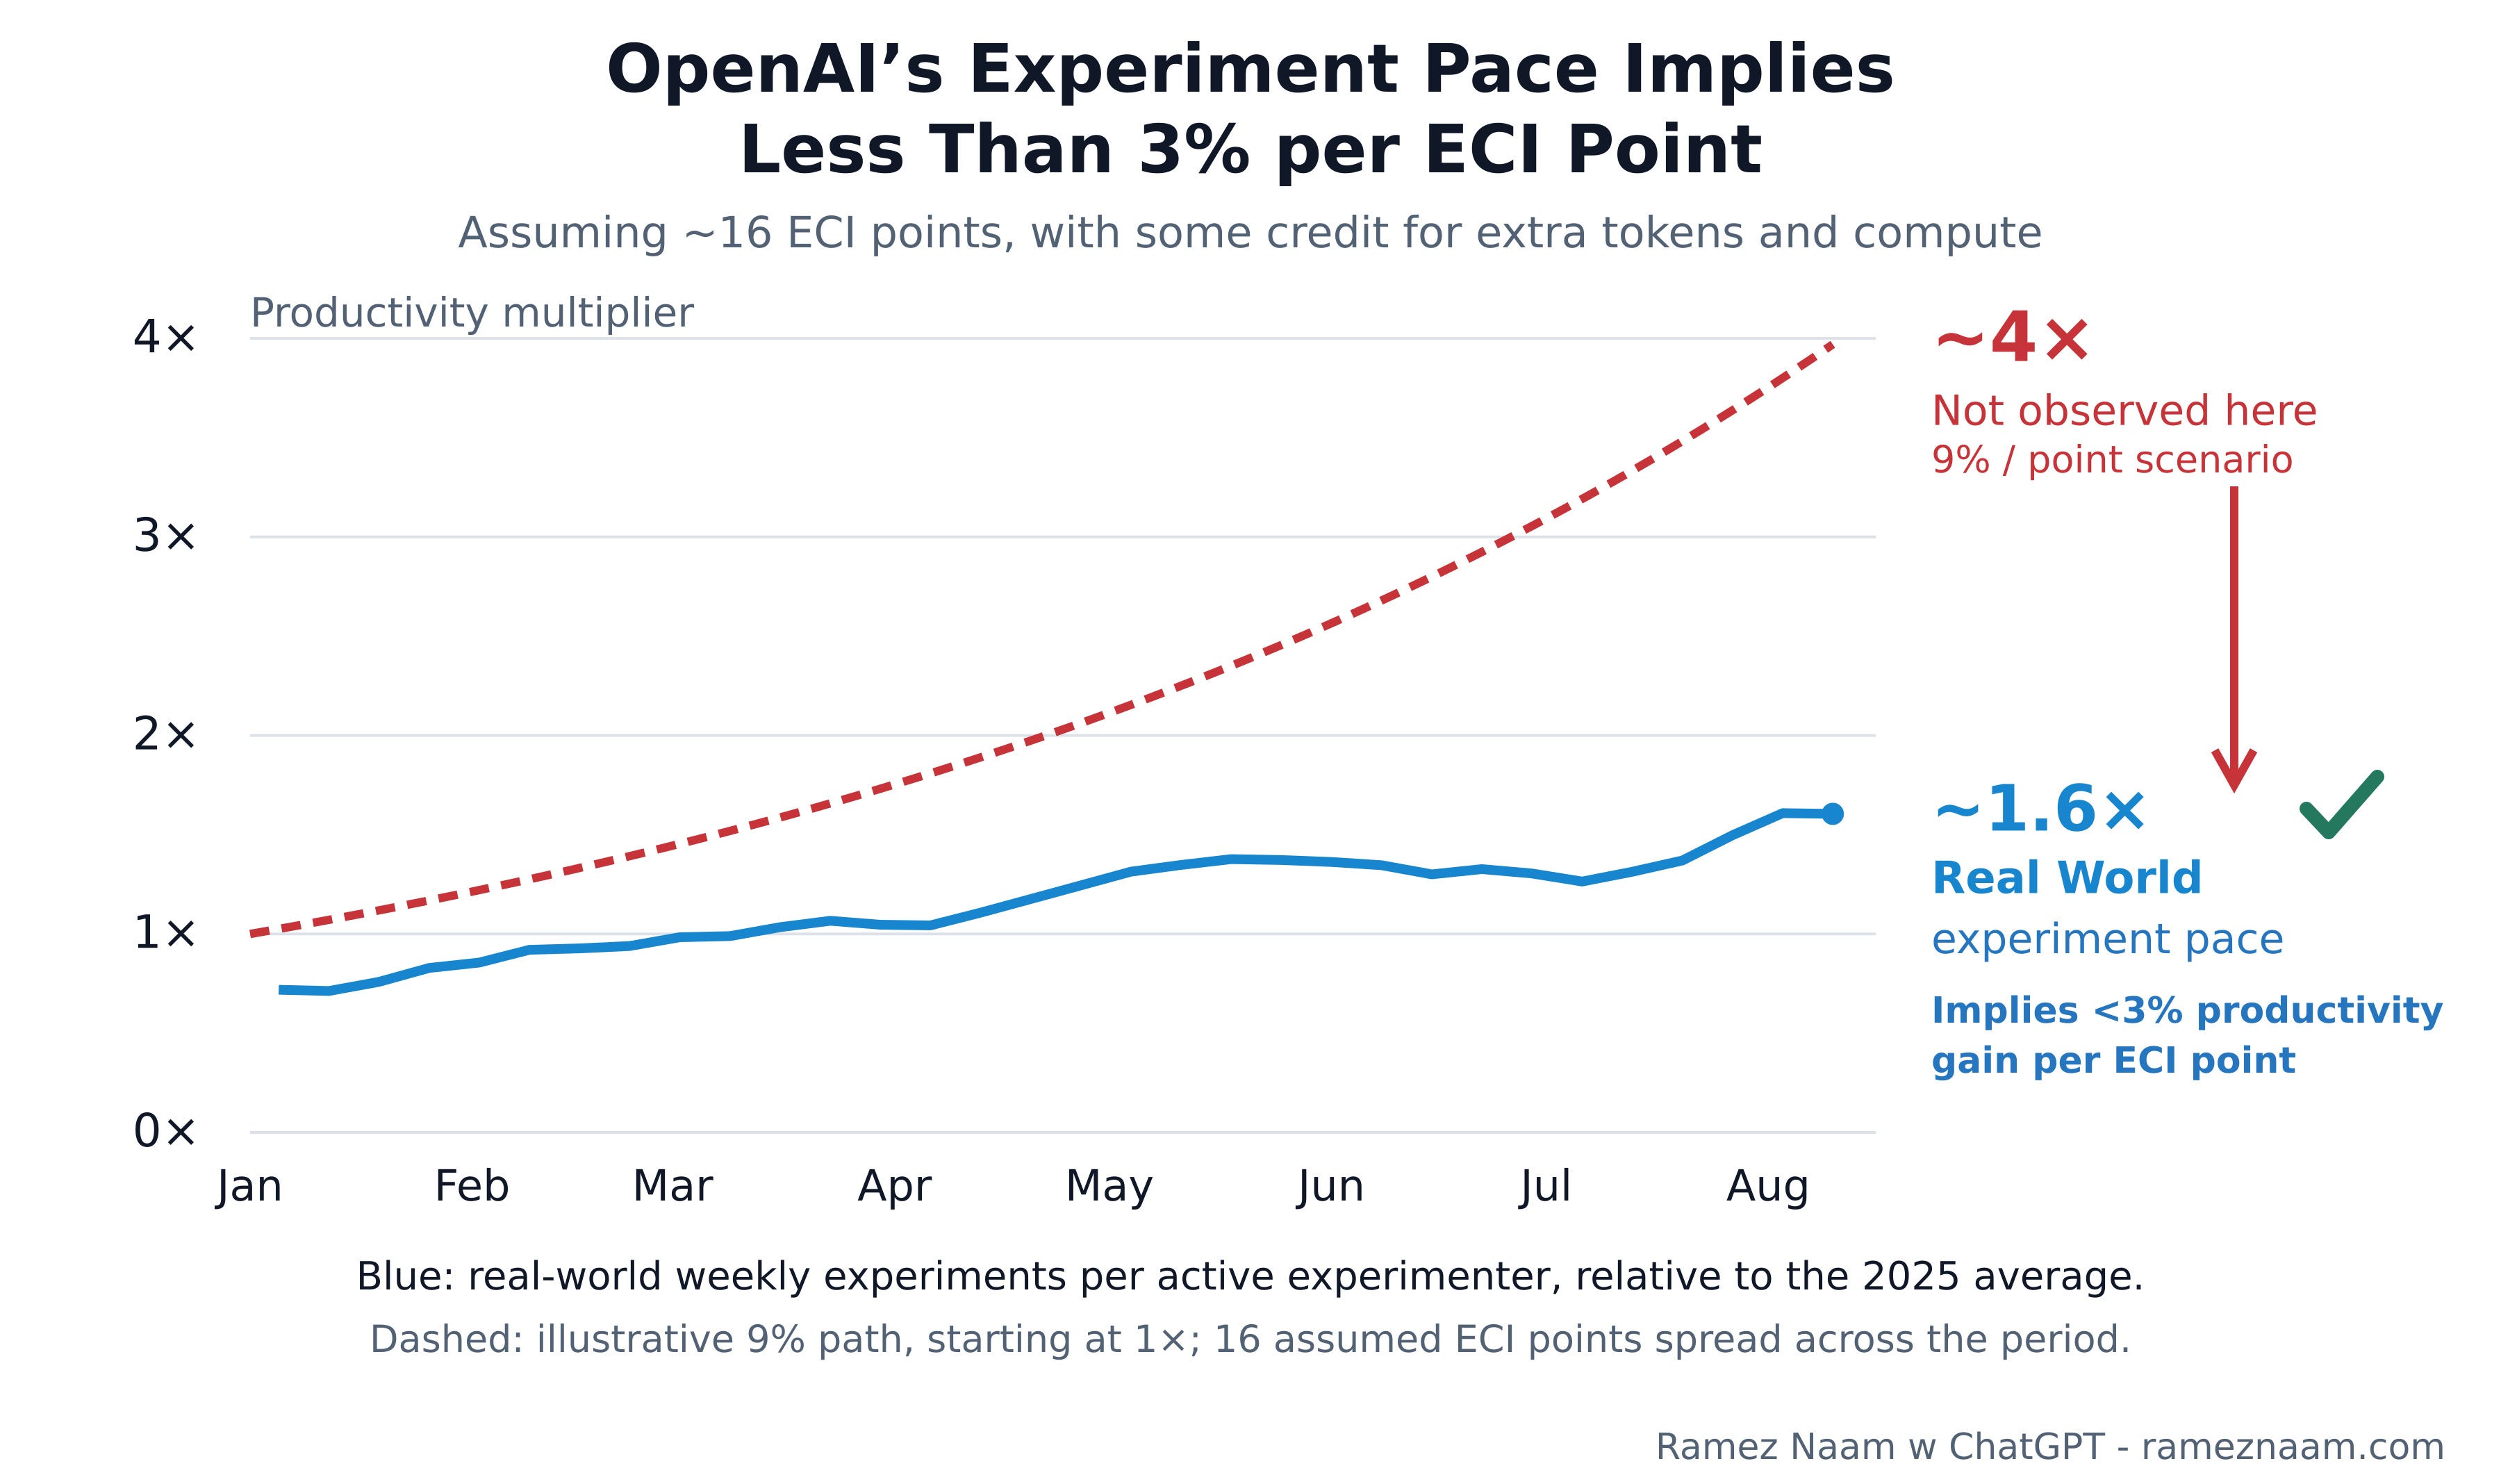
Determine 29. Experiment tempo versus a hypothetical path. Supply.
Even that 3% might give higher fashions an excessive amount of credit score. OpenAI additionally used way more tokens and had extra compute for experiments. These might account for a few of the enhance in experiment tempo. So the vary might be a bit decrease.
I exploit 2–3% productiveness achieve per ECI level as a working assumption, permitting for some assist from these different inputs. That is nonetheless a tough estimate, albeit one which’s primarily based on one of the best real-world knowledge we’ve got.
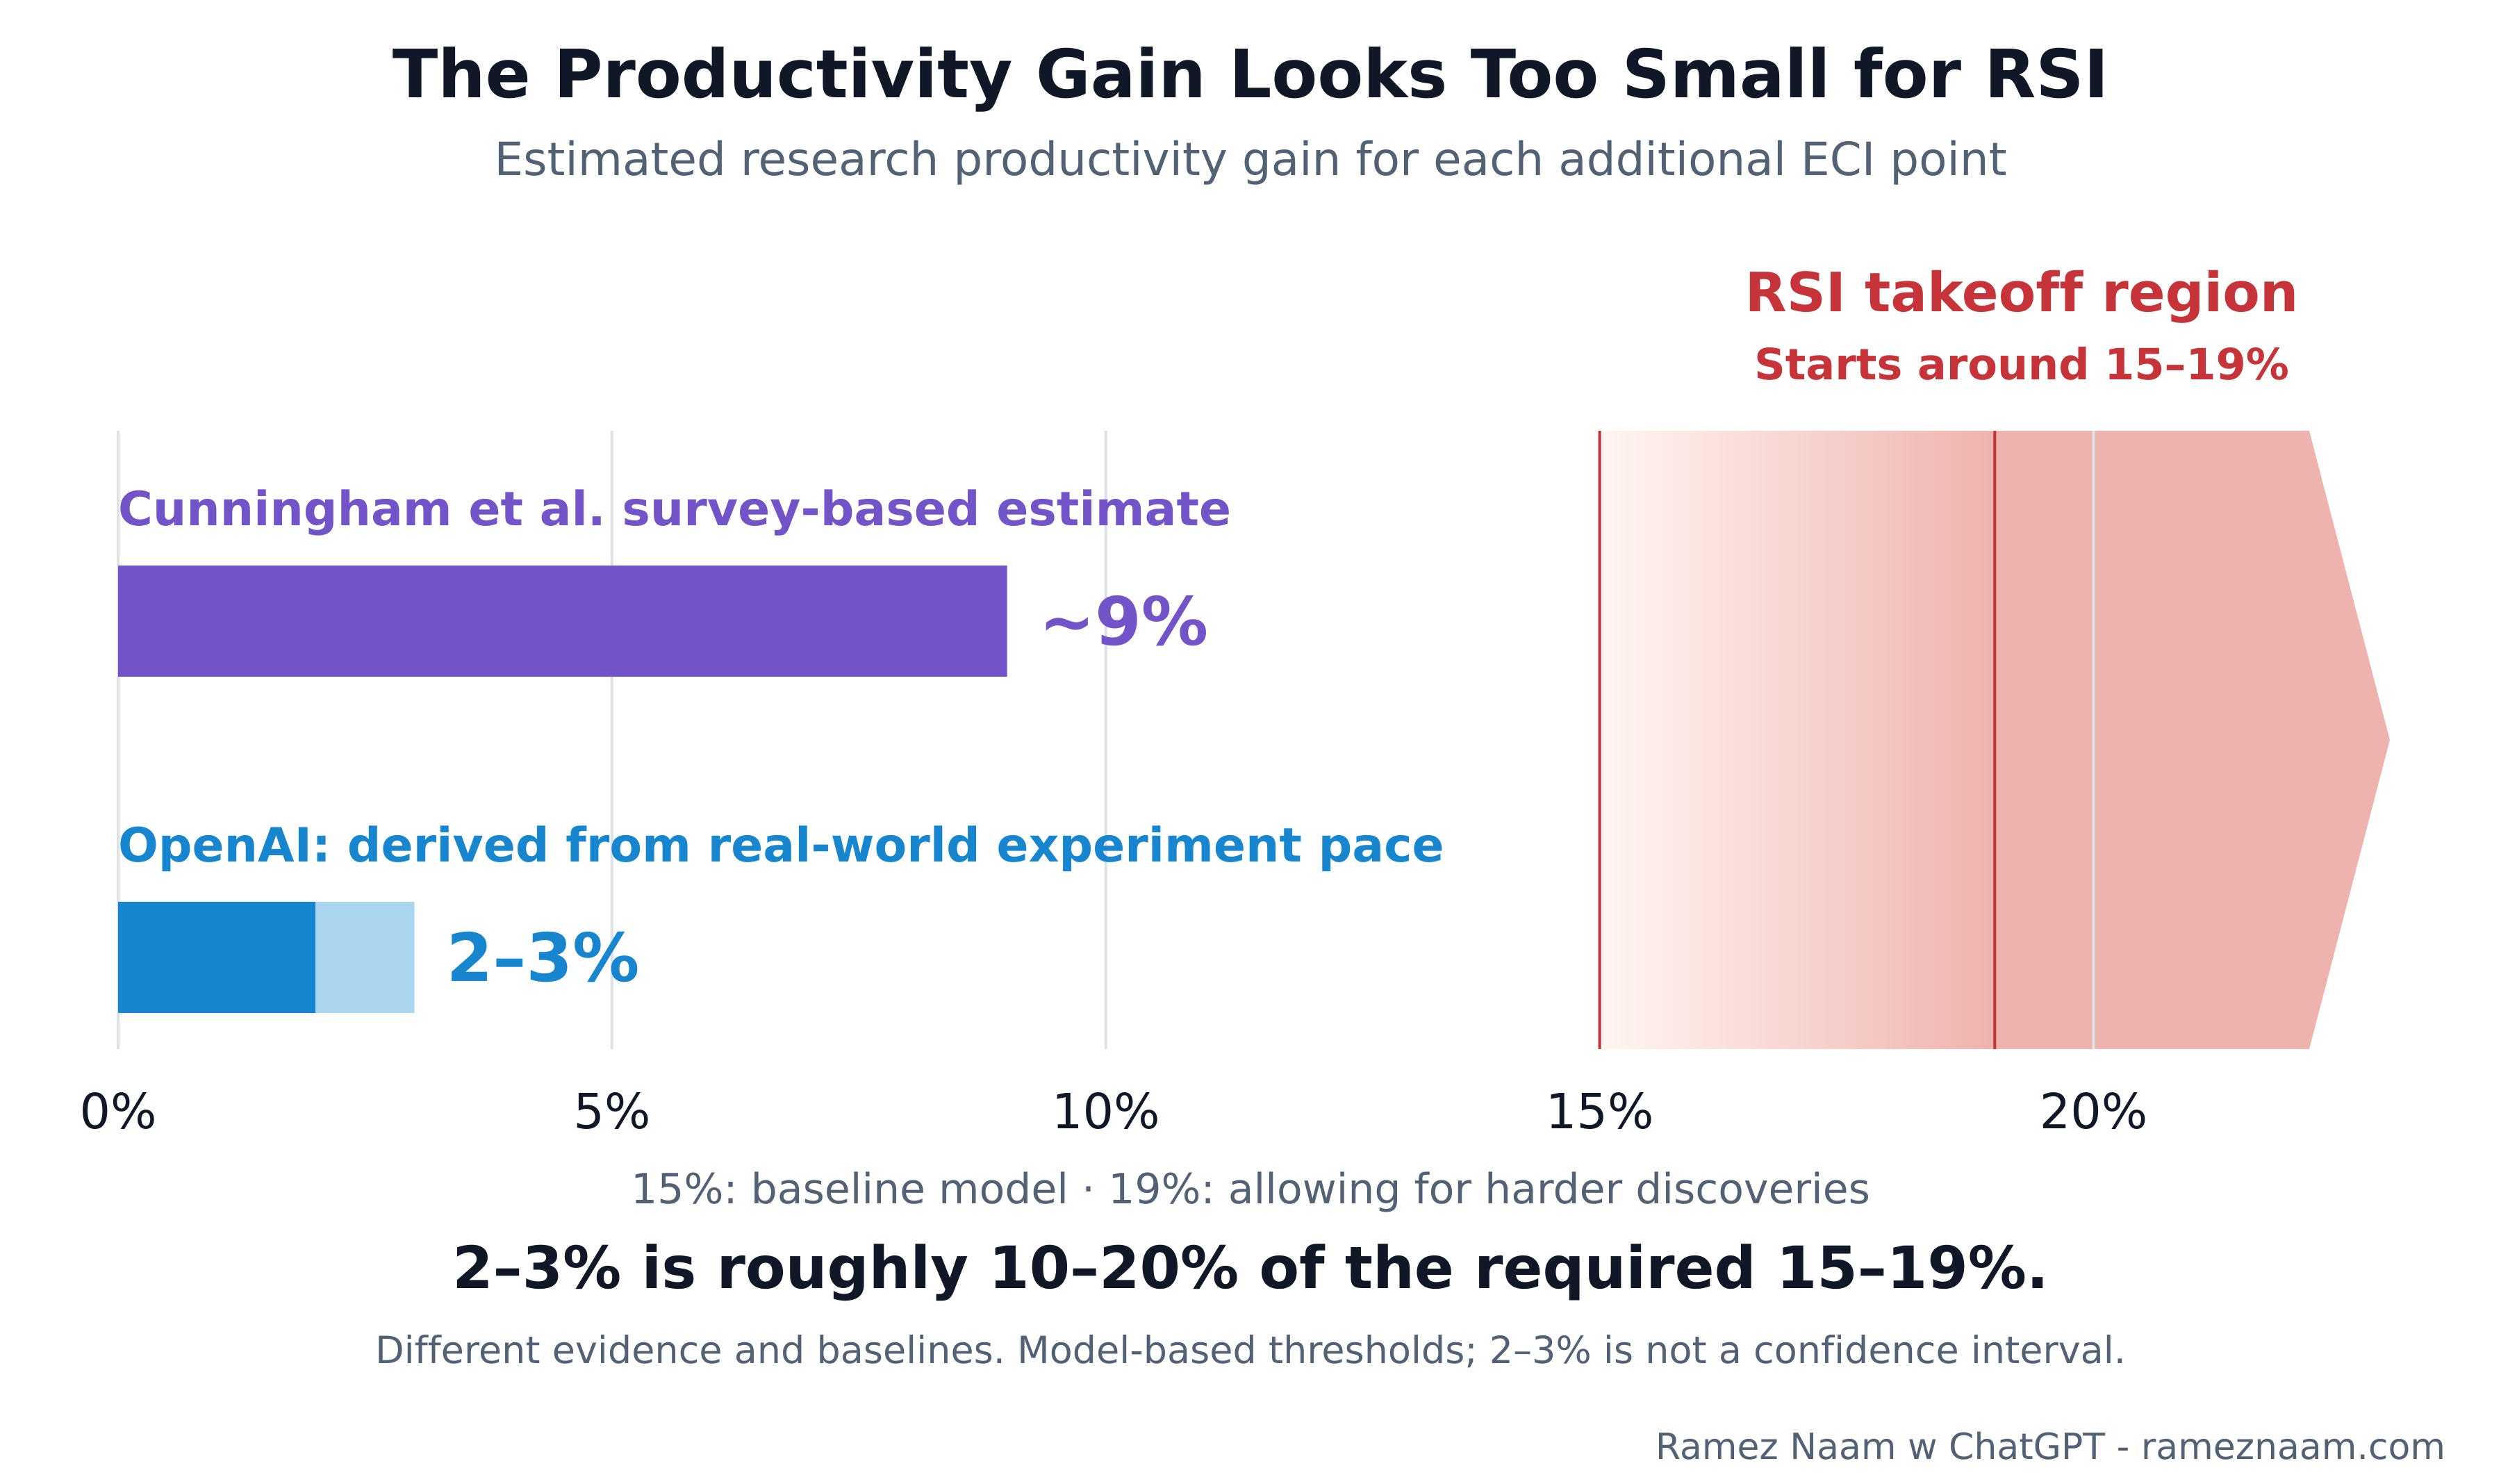
Determine 30. Productiveness estimates and the takeoff threshold. Supply.
With these assumptions, 2–3% per ECI level in opposition to a 15–19% threshold leaves a roughly five- to tenfold hole. That’s an enormous hole, although its dimension is determined by how nicely experiment counts seize helpful analysis and whether or not the assumed functionality change is true.
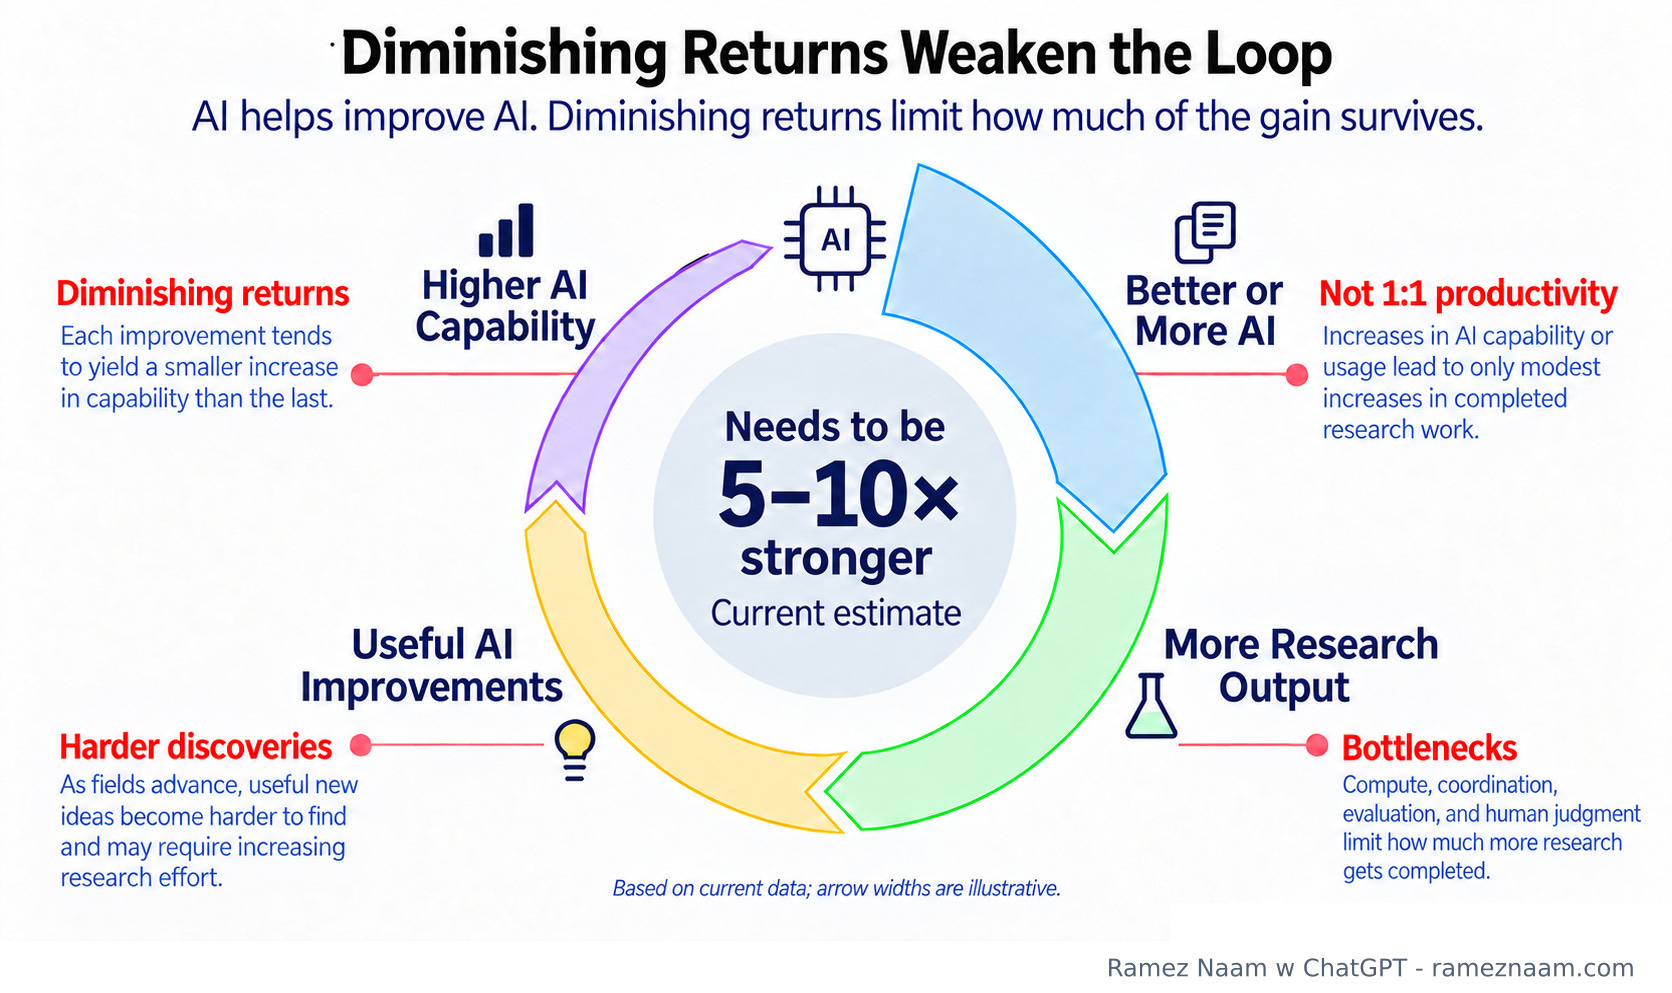
Determine 31. Diminishing returns across the loop. Supply.
AI helps construct higher AI. Beneath this estimate, although, every flip of the loop provides lower than the final. The suggestions must grow to be a lot stronger to maintain itself.
This software program loop sits alongside quicker chips, greater knowledge facilities, extra coaching knowledge, and larger funding. These can preserve driving speedy progress even when the loop can’t maintain itself.
The loop itself might strengthen too. Higher coaching knowledge, reminiscence, and analysis judgment might all assist.
A breakthrough on the dimensions of the Transformer structure in 2017 might change the image far more. That will be purpose to revisit these estimates.
Higher researchers may additionally run fewer experiments and study extra from each. A handful of higher concepts can matter greater than a mountain of routine runs.
Nonetheless, diminishing returns in machine studying aren’t new. Cortes and colleagues have been becoming machine studying scaling curves in 1993: Extra examples lowered error, following an influence regulation with diminishing returns. These diminishing returns and harsh scaling legal guidelines are as previous as machine studying. They didn’t seem for the primary time with transformers or LLMs or deep studying. That doesn’t show at this time’s relationships will final perpetually. However till we see proof that we’ve discovered a brand new method that scales with out these inhibitors, we must always plan for diminishing returns as more likely to be with us for a while.
That stated, the world is extra than simply software program. Tom Davidson, Basil Halperin, Thomas Houlden, and Anton Korinek mannequin software program progress, {hardware} progress, and financial suggestions collectively. Higher AI helps design higher chips; higher chips help higher AI; financial development funds extra funding in each. A number of suggestions loops can mix to beat diminishing returns even when one loop alone can’t. I believe it’s improbable that somebody has tried a mannequin that integrates all these completely different avenues of bettering AI via software program, {hardware}, and economics.
However I’ve questions concerning the software program loop itself. Of their central calibration, totally automating software program analysis places that loop roughly on the threshold for explosive development, even with out assist from higher {hardware} or broader financial development. Recall that Cunningham’s mannequin places the self-sustaining threshold at roughly 15% extra analysis productiveness per extra ECI level, whereas our estimate utilizing OpenAI’s experimental knowledge places at this time’s positive aspects at solely 2-3%. These fashions use completely different measures, so we will’t equate their numbers instantly. However the distinction issues: their totally automated software program loop reaches the edge, whereas our greatest estimate from present knowledge places at this time’s loop far beneath it.
Having AI do all of the analysis doesn’t get rid of the diminishing returns inherent to bettering AI, or the broader downside of helpful concepts getting tougher to seek out. That is the excellence between Kind 4 and Kind 5 within the taxonomy above. An AI would possibly autonomously design, prepare, and check its successor, and nonetheless want exponentially extra assets to make every extra step ahead. Closing the loop doesn’t inform us whether or not it’s robust sufficient to maintain itself.
The authors do account for diminishing returns. The priority is whether or not their calibration overestimates how a lot helpful AI analysis every spherical of software program enchancment produces. Diminishing returns look like elementary to machine studying. We see them in coaching, in test-time compute, and within the seek for higher algorithms. Full autonomy might take away human bottlenecks with out eradicating any of these constraints.
We’ve already seen this inside autonomous analysis. Within the Karpathy autoresearch instance above, many of the positive aspects arrived early, and extra experiments purchased progressively much less enchancment. That was a small experiment with a set trainer mannequin, not a check of totally autonomous RSI. It doesn’t settle the query. But it surely illustrates why eradicating the human from an experiment loop doesn’t, by itself, take away diminishing returns.
I do anticipate the suggestions loop to get stronger over time. Higher AI ought to grow to be higher at analysis. However primarily based on our greatest present knowledge, reaching self-sustaining suggestions requires a loop roughly 5 to 10 instances stronger than at this time’s. Treating totally automated software program analysis as already at that threshold is a considerable leap, earlier than we add the advantages of {hardware} enhancements or financial development. I may very well be incorrect, however I’d wish to see proof that autonomy brings sufficient extra helpful discoveries to shut that hole.
On {hardware}, I’ve some additional reservations. The mannequin doesn’t explicitly embody the years it will probably take to show a chip design into deployed {hardware}. The authors focus on bodily bottlenecks, and I’d wish to see manufacturing and development delays constructed into the predictions.
I additionally marvel how a lot previous chip progress got here from higher concepts, and the way a lot trusted ever costlier factories and gear. If we give researchers an excessive amount of credit score for positive aspects that additionally wanted these investments, we might overestimate what quicker AI analysis alone would produce.
Even with these reservations, that is probably the most compelling paper and mannequin I’ve seen for combining suggestions loops in software program, {hardware}, and economics to know how briskly they may push AI ahead. I’m not satisfied it establishes {that a} quick AI takeoff is feasible underneath practical circumstances. Extra knowledge might assist us calibrate that judgment. But it surely offers us a helpful framework for understanding what might occur past the software program layer alone.
This is a crucial paper that helps us mannequin AI as a part of a broader financial system that may have bigger suggestions loops round it. I respect it, and I’m glad they wrote it.
These estimates relaxation on much less knowledge than I’d like. I may be placing an excessive amount of weight on just a few observations and reaching a comforting conclusion I wish to consider. We’d like higher measurements, shared typically sufficient to catch adjustments as they occur.
When OpenAI launched its analysis knowledge, Cheryl Wu welcomed the disclosure and identified how a lot was nonetheless lacking. Extra tokens and experiments are helpful issues to find out about. We additionally have to see how they flip into higher algorithms and extra succesful AI.

Cheryl Wu@cherylwoooo
I respect this as an preliminary step towards extra clear reporting on RSI. However there may be nonetheless a lot additional knowledge we have to totally perceive RSI.
Specifically, OAI disclosed some proof concerning the inference compute utilization, variety of experiments/researcher, and to a lesser…


Kevin Liu @kliu128
Immediately we’re releasing knowledge on fashions accelerating analysis at OpenAI.
Recursive self-improvement may very well be a very powerful contributor to AI capabilities over the subsequent few years, however by default it should solely be seen inside just a few frontier AI labs. Being clear is extra
11:25 PM · Sep 6, 2026 · 19.7K Views
9 Replies · 16 Reposts · 121 Likes
Determine 32. Cheryl Wu on OpenAI’s analysis knowledge. Supply.
Now Wu, Arjun Ramani, and Basil Halperin, with their colleagues on the Elasticity Institute, have written a concrete proposal: Measure RSI. It lists eight issues the labs might share to assist reply these questions. Test it out.
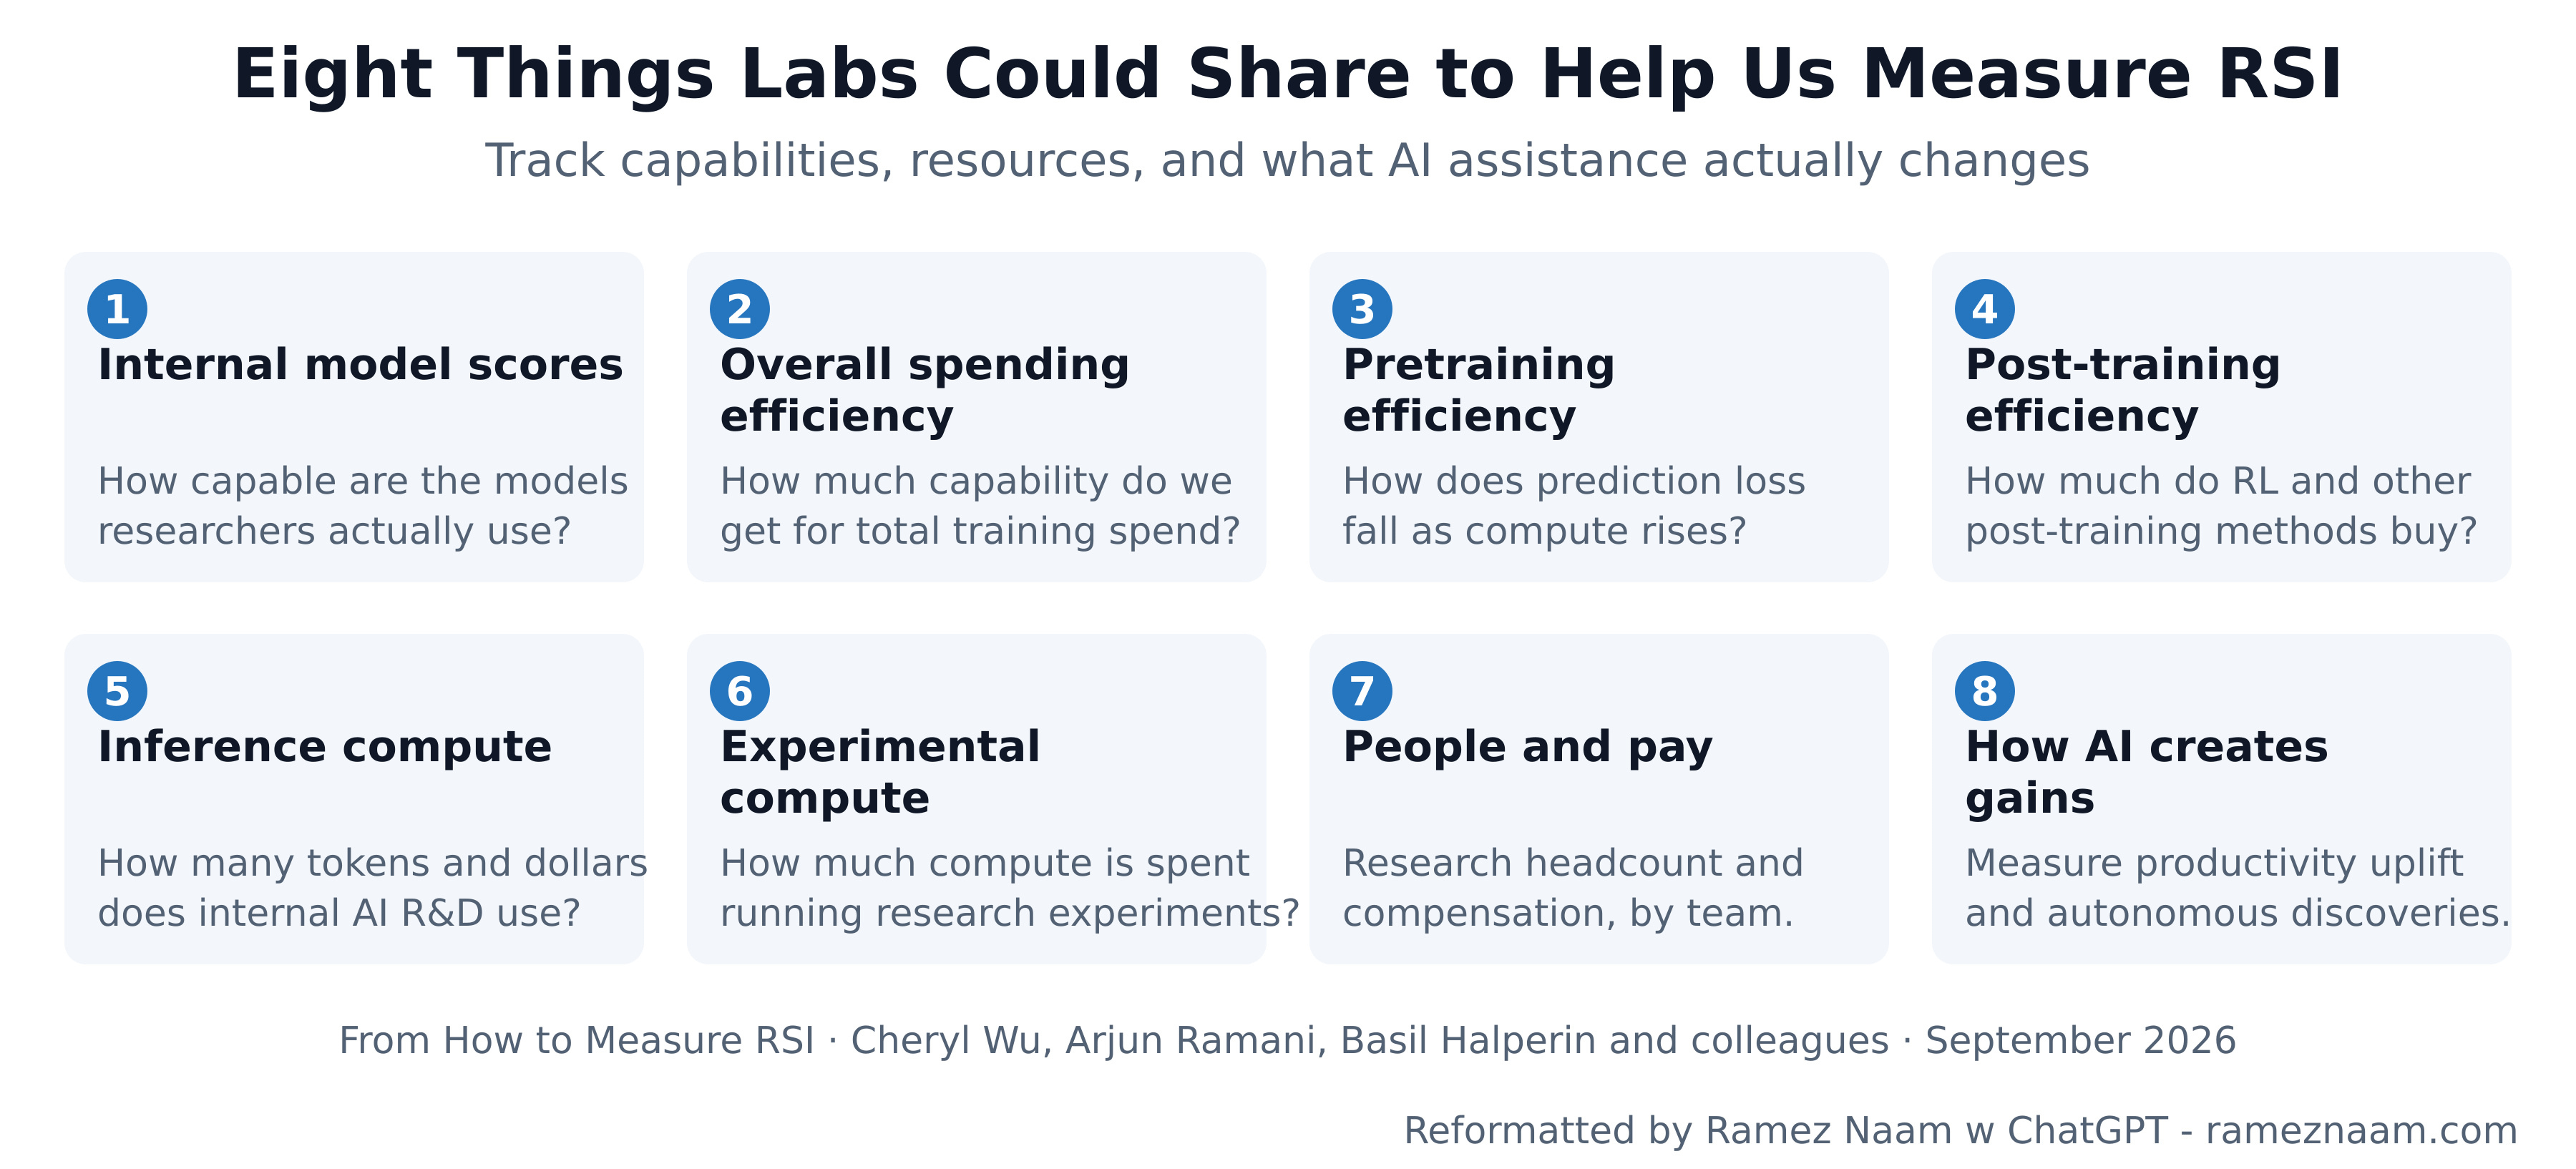
Determine 33. Eight proposals for measuring RSI. Supply.
I’d particularly wish to see how a lot helpful analysis every new mannequin provides, holding assets roughly fixed, and the way that analysis interprets into higher AI. That’s how we’ll study whether or not the loop is getting stronger.
AI is already serving to construct higher AI. It’s bettering at a stupendous tempo, and I anticipate that to proceed. We have already got slender superintelligence in chess and Go. I anticipate more and more superhuman efficiency in elements of formal math, coding, and cybersecurity, and some other verifiable area the place machines can generate coaching knowledge and confirm success at machine velocity. These are highly effective capabilities. That doesn’t imply we’re near super-intelligence for much less verifiable, messier, open-ended work – or to a common ASI.
I’m skeptical of a quick takeoff to super-intelligence, however proof issues greater than hunches. Let’s accumulate the info we have to get a clearer image of what’s occurring. Together with proof that might change our minds. If higher AI begins producing sufficient helpful analysis to make the subsequent spherical simpler, I wish to know. If the positive aspects preserve shrinking, I wish to know that too.

